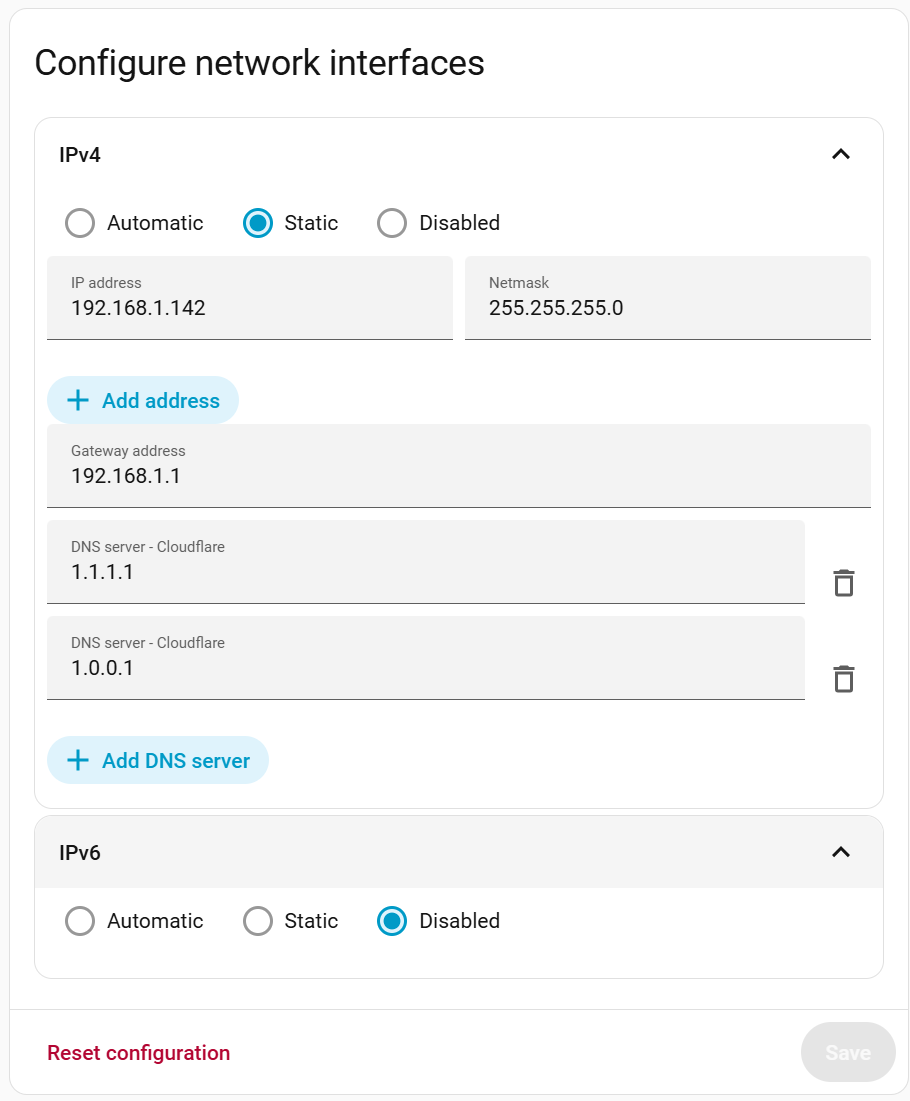
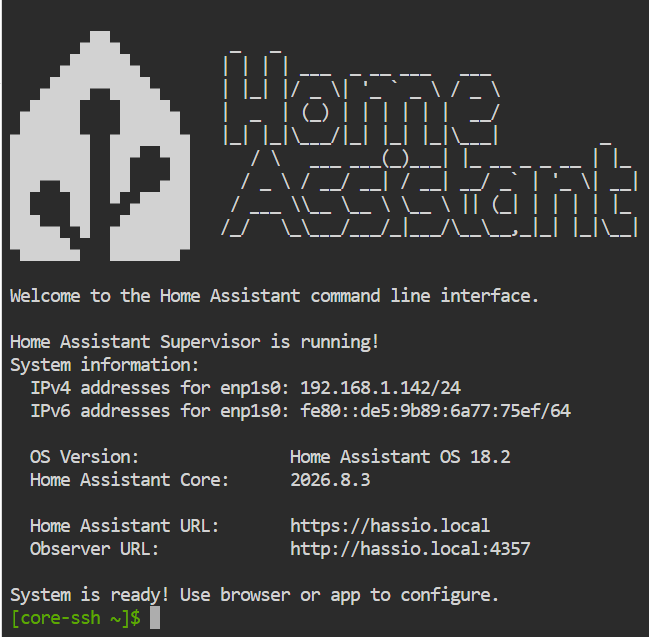
I run HA in a VM and noticed that my other Linux VM was having network communication problems also, which lead me to believe that this is NOT a HA issue, rather an unRaid Issue.
I used Claude to diagnose my unRaid diagnostics file and discovered this.
Docker manages its own iptables rules and frequently sets restrictive FORWARD chain policies for its own bridge (docker0). If br_netfilter is pulling your VM’s bridged traffic through that same FORWARD chain, and there’s no explicit ACCEPT rule for br0, that would explain exactly this: VM has a valid IP, br0/tap attach cleanly, but even gateway pings get silently dropped.
This is a live, reversible test — no reboot needed:
-
1
Disable bridge netfilterIn the Unraid terminal, run: sysctl net.bridge.bridge-nf-call-iptables=0 net.bridge.bridge-nf-call-ip6tables=0 net.bridge.bridge-nf-call-arptables=0 — this tells the kernel to stop passing br0’s bridged traffic through iptables’ FORWARD chain.
-
2
Re-test the gateway pingImmediately re-run ping -c 4 192.168.1.1 from inside the Hassio VM’s real shell. If it now gets replies, we’ve found the cause.
-
3
Persist the fix if it worksIf it works, make it permanent by adding the same sysctl line to /boot/config/go so it’s applied on every boot, then reboot once to confirm it sticks.
Try that and let me know if the ping goes through this time.
I then said “WOOOOO HOOOOO!”
That’s the fix. Glad the gateway ping is finally getting through 
To make sure it survives your next reboot, don’t forget step 3: add this line to /boot/config/go:
sysctl net.bridge.bridge-nf-call-iptables=0 net.bridge.bridge-nf-call-ip6tables=0 net.bridge.bridge-nf-call-arptables=0
Then reboot once just to confirm the VMs still get internet access on a fresh boot — that closes the loop and rules out it being a one-off from the live sysctl change.
I then asked “What would cause this to become an issue all of the sudden? What could I have done to break it? I recently installed GluetunVPN in docker a few days back”
That confirms it — GluetunVPN is running and restarting with Docker each time (I see it in the syslog: GluetunVPN: started successfully! every time the Docker service came up). Here’s the mechanism:
Gluetun needs NET_ADMIN capability and heavily manipulates iptables inside its own container — that’s how it implements its VPN “kill switch” (blocking any traffic that tries to leave outside the VPN tunnel). To do that kind of iptables/NAT manipulation for a container, the kernel needs the br_netfilter module loaded, since that’s what lets iptables see and filter bridged network traffic in the first place.
Before Gluetun, your system probably never needed br_netfilter loaded, so bridge-nf-call-iptables sat at its default (effectively “off” in practice, since nothing was pushing bridge traffic through iptables). Once Gluetun came online and triggered that module to load, the kernel default kicked in — bridged traffic on every bridge on the host, not just Docker’s own, started getting routed through the iptables FORWARD chain. Docker manages its own FORWARD chain rules (allowing its containers, but not necessarily anything else), so your br0 traffic — which Docker knows nothing about — started getting silently dropped there. Your VMs’ bridge setup itself never changed; the ground shifted underneath it.
This is a fairly well-known interaction in the Unraid community specifically with VPN containers (Gluetun, WireGuard-based ones, etc.) that need heavy iptables control. It’s not something you misconfigured — it’s a side effect of Docker + a NET_ADMIN container both wanting the same kernel subsystem, with your VMs caught in the middle.
One thing worth knowing: this can resurface if a future container update or Docker restart re-triggers the module load in a way that resets the sysctl before your go file line runs (order-of-operations at boot). Since you’re setting it in /boot/config/go, it should reapply every boot regardless — just keep it in mind as the thing to check first if this ever recurs after a Docker/VM update.
Thanks Claude and thanks all.