Every setup collects them over time: a switch that dropped off the mesh, a sensor whose battery died months ago, a camera that quietly stopped answering. Home Assistant shows them as unavailable and otherwise says nothing.
I used to cover this with a stack of hand-written template sensors – one device_class: problem template per domain, exceptions via label_entities('offline'), plus a regex reject for the handful of entities that are allowed to be gone. It worked, but every new domain meant copying 25 lines of Jinja, and after a restart everything screamed at once because entities need a few minutes to come up.
So I turned it into an integration.
What it does
- One
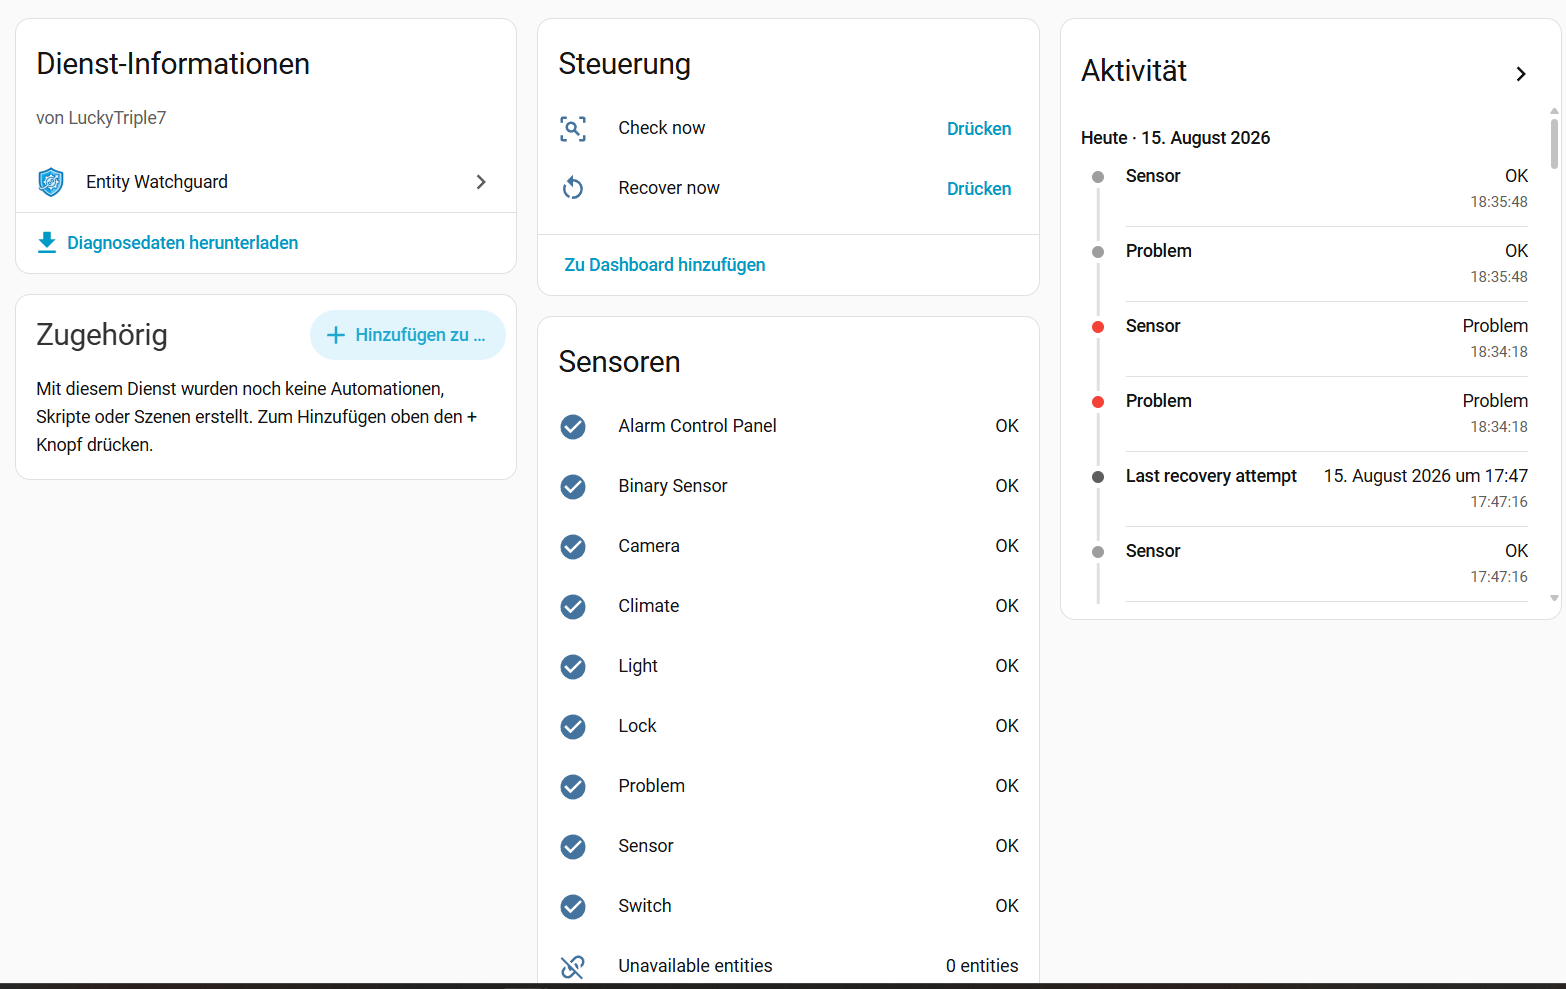
problembinary sensor per watched domain (light,switch,sensor,binary_sensor,climate,lock,camera, …), with the affected entities in its attributes, plus one overall sensor - Startup grace period – after a restart it stays quiet for a configurable time, because half your devices aren’t up yet
- Recovery attempts in two stages – neither is a guarantee, a device that’s physically off stays off
- Stage 1:
homeassistant.update_entity– gentle, just asks for a re-poll - Stage 2: reload the config entry the entity belongs to – more effective, and off by default because it’s invasive
- Stage 2 repeats on a slow interval and gives up after N attempts, so a device that’s simply switched off isn’t reloaded forever
- Stage 1:
- Exceptions by label, entity, device, area, integration, or regex on the entity ID – for the things that are supposed to be offline
- Three reporting channels, each switchable: persistent notifications (one per domain, self-updating, auto-dismissed), repair issues (ignorable per domain), and an optional notify service for mobile push
- Dashboard card included – no resource setup, it registers itself
- Fully configured through the UI, English and German
Why not just template sensors?
Fair question – that’s what I ran for two years. This is a comparison, not a sales pitch:
Cost. A template that iterates states.sensor subscribes to the whole domain. Home Assistant throttles those to at most once per second (DOMAIN_STATES_RATE_LIMIT in helpers/template/render_info.py), and sensor changes constantly – so it really does re-render that often. In my old config each state and each attribute was its own template: 3 per domain × 8 domains = 24 templates, each re-rendering up to 60 times a minute, each one walking every entity of its domain in Jinja. The integration does one in-memory scan per interval – 60 seconds by default – with no template rendering and no state-change listeners at all.
Restarts. Templates evaluate immediately, so every restart lit up every sensor for a few minutes while devices were still coming up. The integration has a startup grace period that starts counting once HA has finished booting.
Flapping. A template flips the moment an entity blinks. Here an entity has to stay unavailable for a grace period before it’s reported.
Templates only tell you. They never act. No re-poll, no reload, no escalation, no giving up.
One place instead of N copies. Adding a domain is a checkbox, not 25 lines of copied Jinja. Same for exceptions – and beyond labels and regex you also get device, area and integration.
Database. Template attributes with long entity lists get written to the recorder on every change. Here those lists are capped and excluded from the recorder.
If all you want is “is anything unavailable, yes or no”, a single template sensor is genuinely fine and you don’t need this. The integration earns its place once you want per-domain detail, exceptions that survive being edited, quiet restarts, and something that actually tries to fix the problem.
Two details I’d like to highlight
It doesn’t restart your MQTT broker over one dead sensor. Stage 2 reloads a config entry – but hub integrations like MQTT, ZHA or Z-Wave have one config entry for hundreds of entities. So before reloading, it checks how much of that entry is actually down. One sensor out of 213? No reload. All 213? That’s the broker, reload it. The threshold is configurable.
Stage 1 is skipped for push integrations. update_entity can’t do anything for MQTT or ESPHome entities, so those go straight to stage 2 instead of wasting an attempt. Detected from the integration’s iot_class.
The card
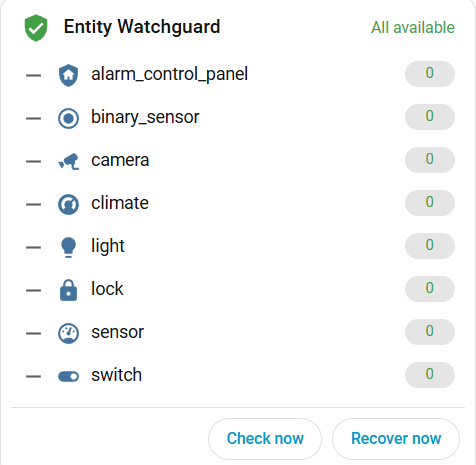

One row per domain with a counter, click to expand. Each entity shows how long it’s been gone, how many recovery attempts ran, and whether Watchguard gave up. Click an entity for its more-info dialog, or use the label button to exclude it from future scans – the label is created on first use. Check now and Recover now at the bottom for when you don’t want to wait.
Installation
HACS → three-dot menu → Custom repositories → https://github.com/LuckyTriple7/ha-entity-watchguard → Integration → Download → restart Home Assistant.
Then Settings → Devices & Services → Add Integration → Entity Watchguard and pick the domains you care about. Everything else has sane defaults.
Defaults, so you know what you’re getting
| Startup grace period | 5 min after HA has started |
| Check interval | 60 s |
| Grace period per entity | 2 min before it’s reported |
| Stage 1 | on, after 5 min |
| Stage 2 | off, after 15 min |
| Notifications | on, after 15 min |
Feedback welcome, especially on the recovery side – I’m curious which integrations actually come back from a config entry reload and which ones need something else entirely. Issues and ideas go here: Issues · LuckyTriple7/ha-entity-watchguard · GitHub