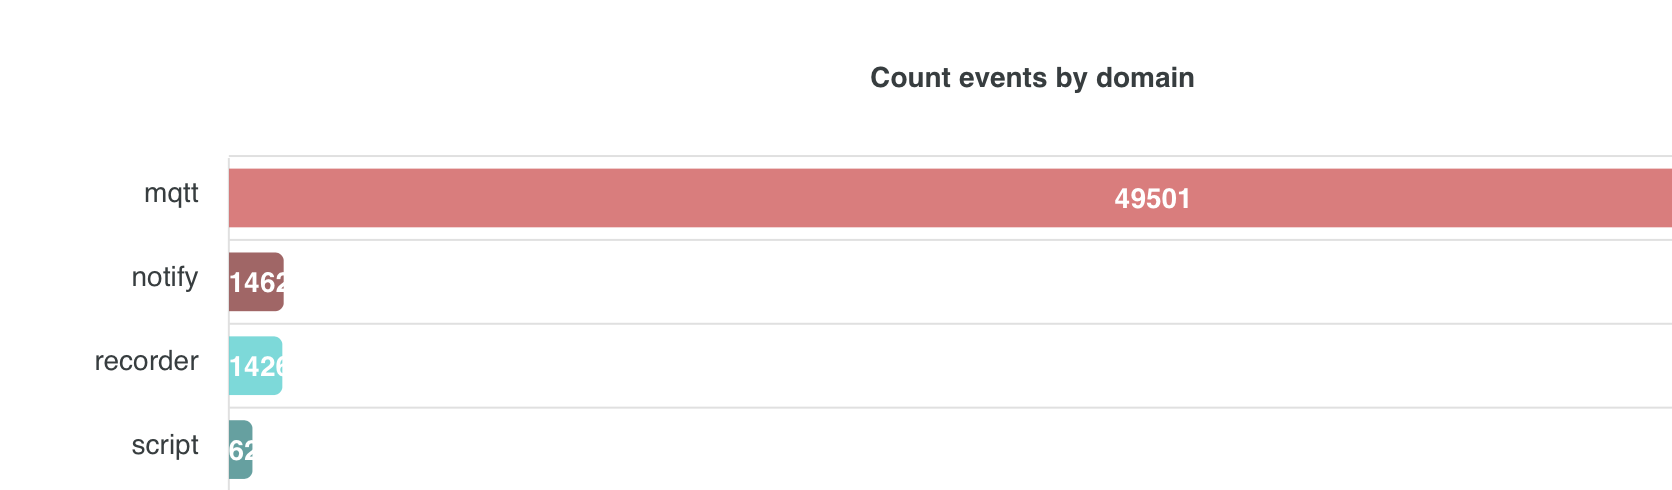
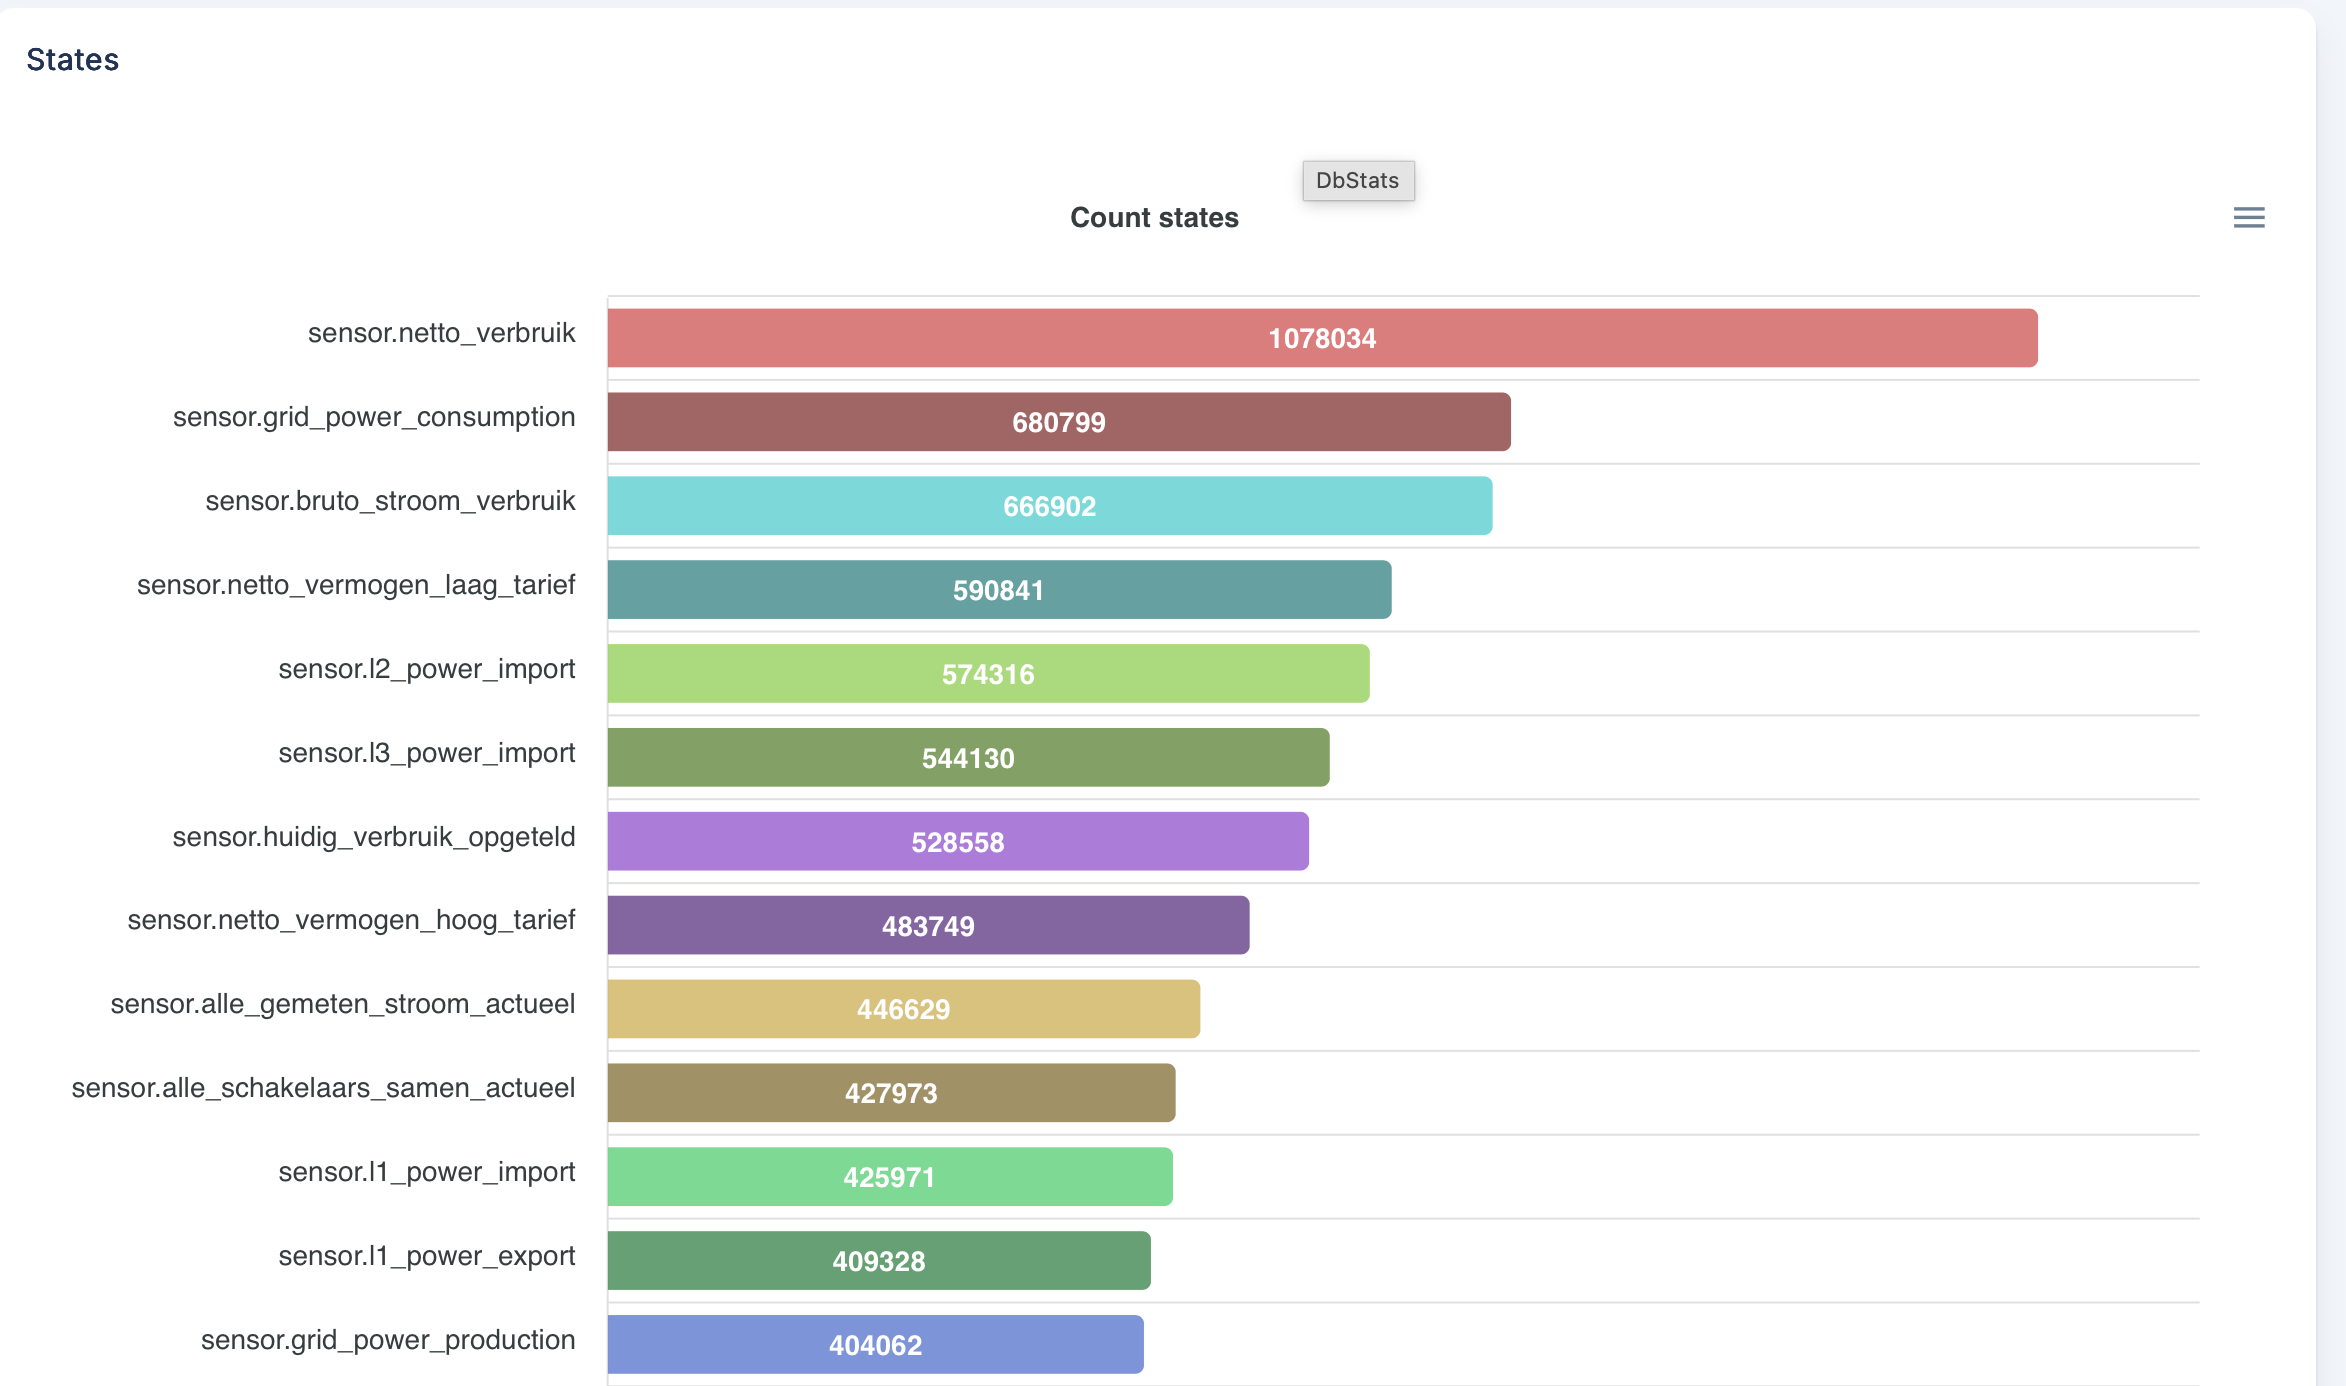
indeed, i’ve used same approach to start choosing excludes from recorder and have now 1 entity showing which entity it biggest updater. now it is a energy measure thats updating each 2 seconds doing 25k updates each day, up for exclusion soon when i find the time
but back to topic, this is getting out of hand for a Backup type of question… db being part of that..
pardon me for deranging…
Yeah, I possibly shouldn’t have started this as well. Just thought people might be interested in how to find the high consumption entities for their big databases / backups.
And just for info… My snippet was a direkt shell command when logged in via e.g. ssh or when you start the Advanced SSH App directly in Home Assistant.
but on db and backup topic specifically, hosting HA in its docker and dB in separate one, makes my backup around 400mb and a restore never overwrites my db data.
There are sooo many ways now, that just a ‘how big is yours’ doesnt really cut it.
What on earth are you talking about? This thread is for gathering information for a specific bug regarding restoring backups linked in the first post.
Settle down - chill man!. You were also abrupt in your other thread. The thread digression and meandering here was useful, and has spinoffs that are related to database pruning, and the underlying bug you initially reported there (with little detail) seems to have been identified as related to the restore subroutines failing, rather than the database size you were so keen to gather statistics for. What you forgot to clarify was what version was running, the recent core changes being the critical detail, rather than the database size or container modality. This highlights the necessity for a structured, methodical process of elimination for efficient problem solving.
The proposed temporary workaround to increase the size of MAX_CLIENT_SIZE may affect other tasks that use the core HomeAssistant aiohttp subroutines, and may result in unnecessary performance impacts. Certainly use it to be able to do your restore, but put it back when you have finished.
Now we wait for the official fix, fingers crossed that nothing else breaks.
I’ve wonder from start what the purpose of knowing peoples backup-size, cant really see what it would help Dev’s in the Github reported “issue”
I pretty sure they are aware it’s variate from 2 digits MB to 2 digits GB
If there is going to be an upper limit, it’s work finding out if that upper limit will still cause problems.
There will always exist an Upper limit in a Processing Environment , That is what have evolved Disk/CPU/Ram etc , and so will it continue to work 
I.E 2 decades ago a home network was at 100mb, now some have 10gb, driven by “upper limits”
PS: Fact is also your +300mb backup is far from existing limits, for i.e a HA installation
2.9G as expected due to sensor table since I keep a long window.
I concur about absolute limits, but there is also the well understood concept that any backup you cannot restore is not a backup. At some point Home Assistant dev team need to make a choice of what is, and what is not a backup, and while you say 300+ is far from existing limits, it is not. The existing limit is 16MB if you are trying to restore using a container deployment.
" chunk-size " in read
Where did you get the idea it has anything to do with the size of a backup ?
I was mislead by the fact you didn’t mention “chunk-size” at all in your previous comment and only vaguely talked about “existing limits” which I took to mean “The existing limit of the backup restore tool on a contain deployment of HA” because that’s what the thread was about.
Please change your Topic-header to reflect your"findings" and current direction, as comparing/collecting size of peoples backup is still irrelevant
I’m finding your argument impossible to follow. In the linked issue in the first post people were sharing their backup sizes to get an idea of what an upper limit might be. I opened a thread for that here. It is doing its job.
Yes, it has highlighted that size doesn’t matter (I’ll skip the reference that comes to mind), as the subroutine the restore function uses ‘chunks’ the file into fixed sizes and processes these sequentially.
The problem about the faulty ‘chunking subroutine’ is in your other thread and the GitHub report there too.
I agree, a backup you cannot restore is not a good place to find yourself in time of crisis. Hopefully it will be comprehensively addressed soon.
This thread has probably served its purpose.
An update has been made to the algorithm. Details at
for 2026.9.1 release.
For those that used the unofficial workaround to increase the size of the variable MAX_CLIENT_SIZE should possibly check that it has reverted in the fix so it does not cause instability for other routines that depend on the aiohttp subroutine.