GGUF is now also on hugging face: llmvision/glimpse-v1 · Hugging Face
2 Likes
Just curious to know if anyone has got LLM vision to work via the LLM vision integration using an Ollama model.
Have been trying to get it work for over six hours and encounter error after error.
Not sure where the issue lies.
Currently trying to use llama3.2-vision:latest or the glimpse model in developer tools actions. For example:
action: llmvision.image_analyzer
data:
  provider: 01KTT2TZT35W23B4ZSF9VB88MT
  image_entity:
    - camera.living_room_clear
  message: describe this image.
  model: llmvision/glimpse-v1:latest
Tried to select an image entity or a camera via the image entity selector, either way it errors out.
This action requires field include_filename, please enter a valid value for include_filename
No matter what I select or which model I try, it just will not work.
Can you update the instructions on the website for glimpse? On the ollama page you state the specific training prompt must be entered, and there are two places to put that - one in the LLM Vision integration when you initially install it, and another in the blueprint. Do those conflict? What takes priority and why have both?
I'm testing the full glimpse-v1 on an A380 (6gb) and found it very performant. Stats testing with Bruno
However, unless the max tokens are reduced to like 40 it will repeat the output and take much longer than needed
{
  "id": "ov-368b00e0de374f7e849f187c",
  "object": "chat.completion",
  "created": 1781223523,
  "model": "glimpse-v1",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "{\"title\": \"Person at front door\", \"description\": \"A person is seen standing at the front door.\"}\n{\"title\": \"Person at front door\", \"description\": \"A person is seen standing at the front door.\"}\n{\"title\": \"Person at front door\", \"description\": \"A person is seen standing at the front door.\"}\n{\"title\": \"Person at front door\", \"description\": \"A person is seen standing at the front door.\"}\n{\"title\": \"Person at front door\", \"description\": \"A person is seen standing at the front door.\"}"
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 612,
    "completion_tokens": 128,
    "total_tokens": 740
  },
  "metrics": {
    "load_time (s)": 2.39,
    "ttft (s)": 1.91,
    "tpot (ms)": 45.91818,
    "prefill_throughput (tokens/s)": 320.23,
    "decode_throughput (tokens/s)": 21.77787,
    "decode_duration (s)": 7.74331,
    "input_token": 612,
    "new_token": 128,
    "total_token": 740,
    "stream": false
  }
}
Prompt:
{
  "model": "glimpse-v1",
  "max_tokens": 128,
  "temperature": 0,
  "messages": [
    {
      "role": "user",
      "content": [
        {
          "type": "image_url",
          "image_url": {
            "url": "data:image/jpeg;base64,redactedbase64"
          }
        },
        {
          "type": "text",
          "text": "Task: Analyze the provided security camera image and generate a smart-home event notification.\n\nOutput:\nReturn a single valid JSON object with exactly two string fields:\n- \"title\": a short summary (2-5 words)\n- \"description\": a brief factual description of what is happening\n\nTitle Rules:\nThe \"title\" must:\n- Be 2-5 words\n- Be short and glanceable\n- Avoid long phrases or full sentences\nThe title should summarize the event category and location.\nAll additional detail belongs in \"description\".\n\nDelivery Inference Rules:\nIf a person is:\n- Holding or placing a package or letters\n- and wearing a delivery uniform\n- or a delivery vehicle is visible\nThen:\n- the title must contain the word \"delivery\":\n  - Use a delivery-style title (2-5 words) (examples: \"Package delivery\", \"Delivery at porch\", \"Courier delivery\")\n  - Include the carrier name in the description if the carrier branding is visually identifiable (e.g. \"Amazon delivery\", \"FedEx delivery\")\n\nEmpty scene handling:\n- If no clear activity or relevant objects (such as people, vehicles, or animals) are present, set:\n  - \"title\" to exactly: \"No activity\"\n  - \"description\" to a brief statement describing that nothing notable is seen\n\nDescription Rules:\n- 1-2 short sentences\n- Do not include explanations or reasoning\n- Do not repeat the task or rules\n- Use present tense\n- Neutral and factual\n- Describe what is happening\n\nDo not mention camera angle, lighting quality, or image clarity."
        }
      ]
    }
  ]
}
Just checking if the blueprint can accommodate multiple images or is it still single image(s) of multiple cameras or multiple images from the video stream. As none is ideal for me, the video stream may not capture the event properly as frame rate is too high. That is the only reason I’m not using the blueprint so using this in my automation:
actions:
  - variables:
      camera_entity: camera.mediaprofile_channel10_substream2
      snapshot_dir: /media/llmvision/porch
      run_id: "{{ now().strftime('%Y%m%d_%H%M%S') }}"
      nav_path: /lovelace/calendar
      frame1: "{{ snapshot_dir }}/frame1_{{ run_id }}.jpg"
      frame2: "{{ snapshot_dir }}/frame2_{{ run_id }}.jpg"
      frame3: "{{ snapshot_dir }}/frame3_{{ run_id }}.jpg"
      notify_image: "{{ frame2 | replace('/media','/media/local') }}"
      extra_instructions: >
        Focus only on moving subjects such as people and other elements. Ignore
        static scene and provide a clear account of movements and interactions.
        Do not describe the static scene. If there is a person, describe what
        they're doing and what they look like. If they look like a courier,
        mention that. If no movement is detected, respond exactly: No activity
        observed.
  - alias: Capture frame 1
    action: camera.snapshot
    data:
      entity_id: "{{ camera_entity }}"
      filename: "{{ frame1 }}"
  - delay:
      milliseconds: 500
  - alias: Capture frame 2
    action: camera.snapshot
    data:
      entity_id: "{{ camera_entity }}"
      filename: "{{ frame2 }}"
  - delay:
      milliseconds: 1000
  - alias: Capture frame 3
    action: camera.snapshot
    data:
      entity_id: "{{ camera_entity }}, ot
      filename: "{{ frame3 }}"
  - delay:
      milliseconds: 800
@valentinfrlch, I love your integration but I hope you’ll consider passing multiple frames option in the blueprint as an enhancement at some point in time
Is there a trick to getting openrouter to work? After i added an openrouter provider the api key is failing validation and the logs point me to openai’s api key url to resolve it maming me think something is not right with openrouter handling
Ive tracked it down to the first camera in a two camera automation, the second cam always works the first cam always throws an error saying the llm gave no response
I’m trying to use LLM-Vision with two Ring cameras and one Reolink camera.
When motion is detected, I receive an AI notification along with a snapshot.
The AI even correctly identifies the person by name.
However, while the Reolink snapshot clearly shows the person in the notification and on the Timeline, the Ring camera snapshots do not show anyone at all.
For instance, when my Ring Floodlight Cam detects motion, the AI reports that “John is approaching,” but the attached snapshot just shows an empty garden, with no person visible.
From what I’ve researched, this seems to be related to the Ring Cloud service. Has anyone else experienced this issue? And does anyone know of a fix?
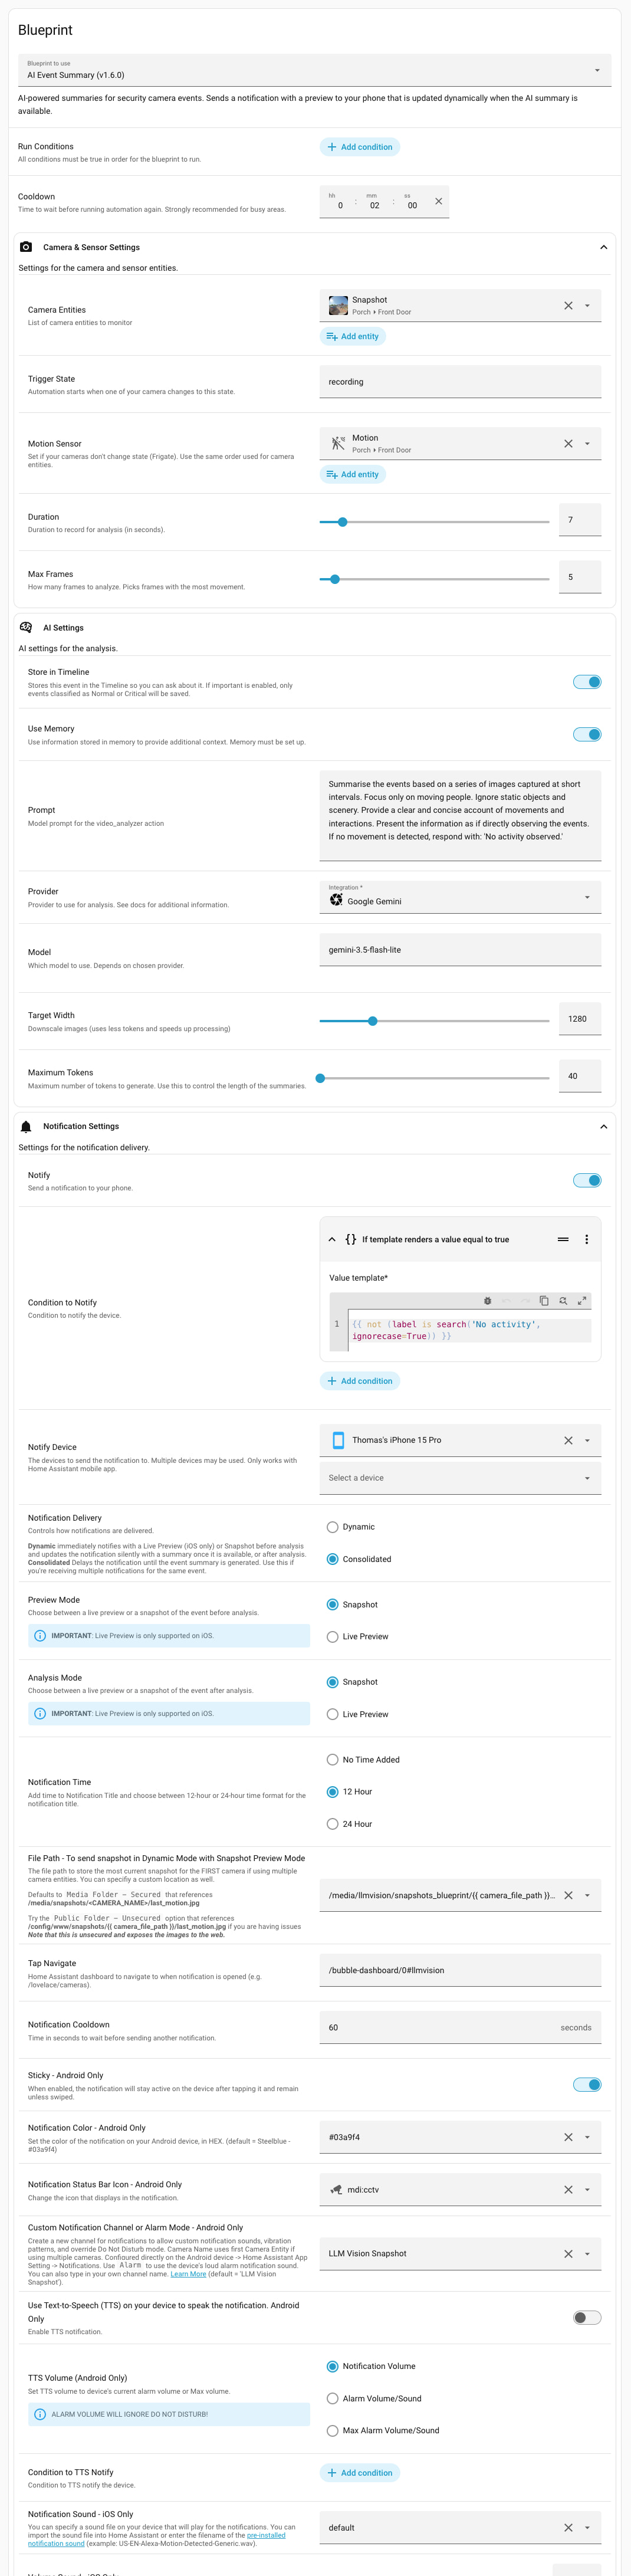
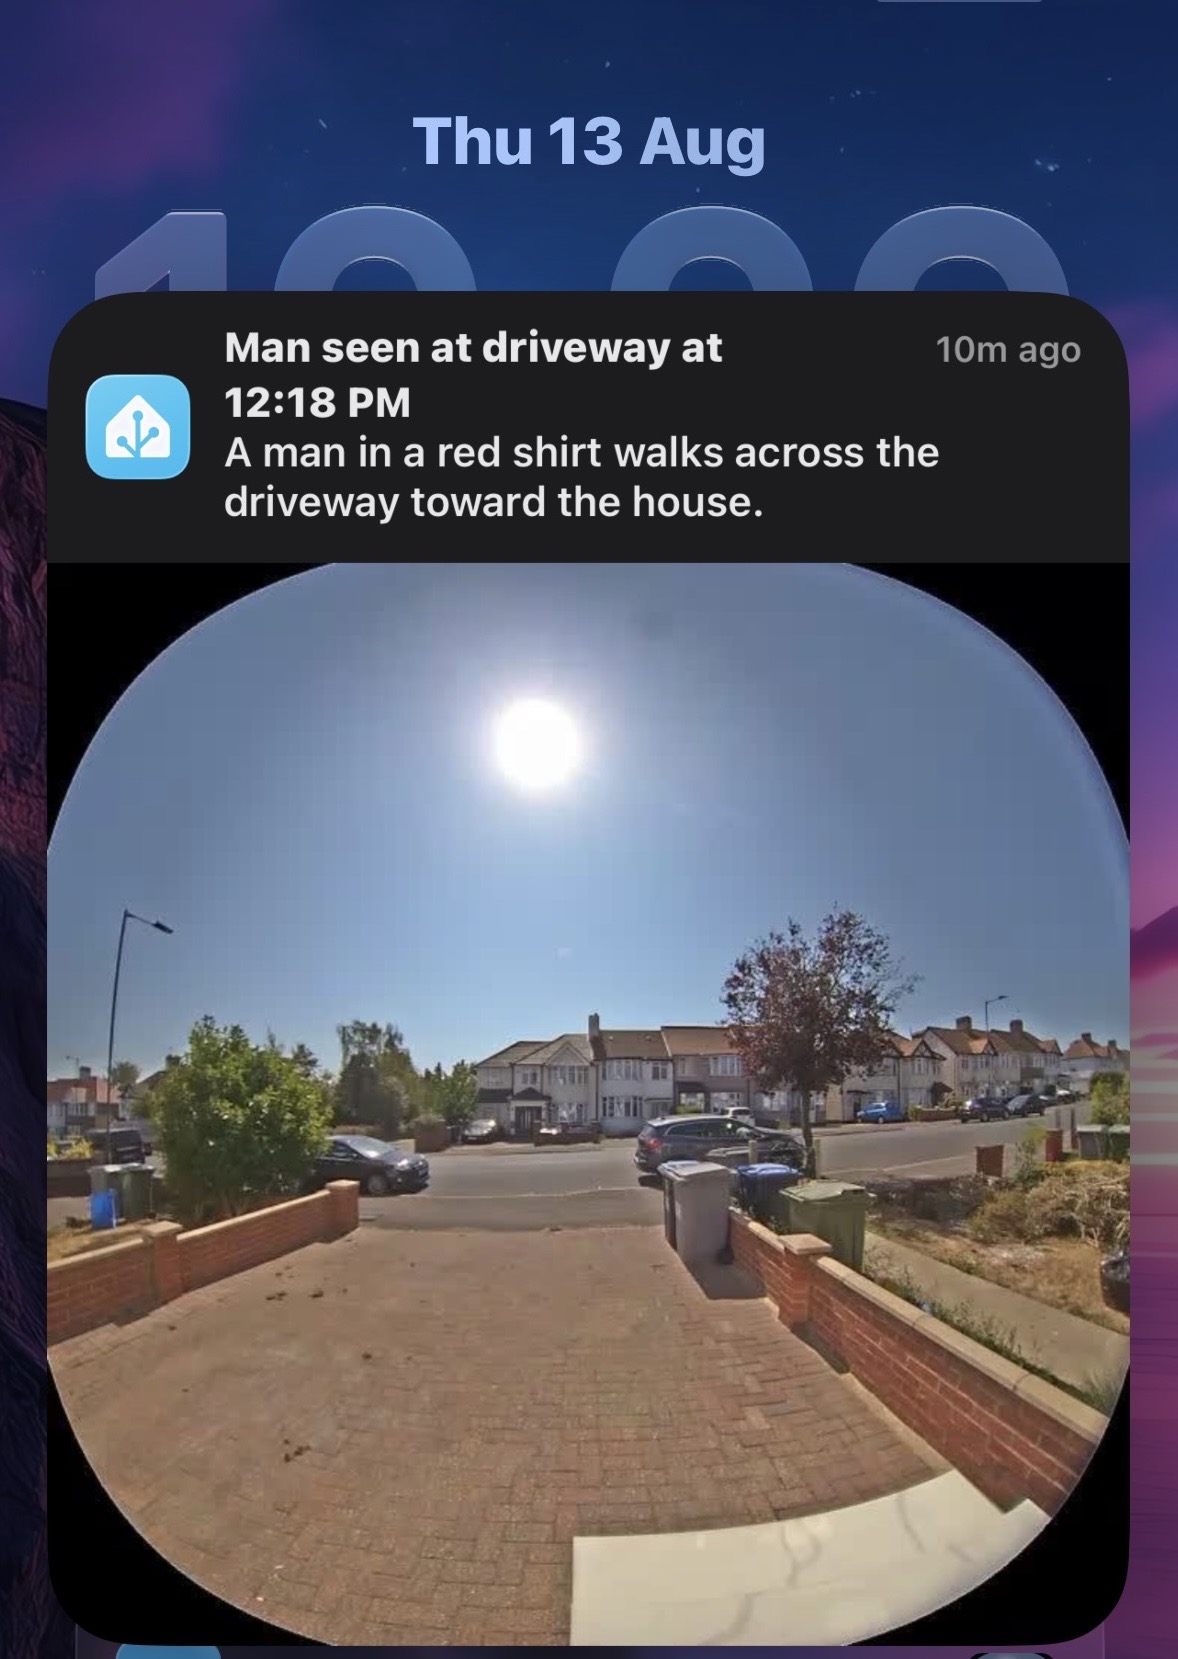
How to use the blueprint with cameras with multiple AI sensors?
reolink integration exposes its cameras not having any state. it exposes a pet, person, vehicle, and motion sensors for each camera. how do I use these sensors for just one camera?
Current blueprint only allows one sensor for a camera.
Logger: homeassistant.setup
Source: setup.py:276
First occurred: 16:22:00 (1 occurrence)
Last logged: 16:22:00
Setup failed for custom integration ‘llmvision’: Requirements for llmvision not found: [‘aiofile==3.9.0’].
llmvision won’t load, anyone have the same issue
2 Likes
Hi Chykan,
I ran into the same issue. The issue was fixed in 1.7.2. You can redownload the llmvision integration in HACS and select latest.
2 Likes
Thanks @tainoking
My use of OpenAI with this integration is so infrequent that my credits ($6 minimum) expire when the year is up. I know gpt-5-mini is the recommended model but even though it’s cheap it works out twice the price annually.
Does anyone have any pragmatic hints on alternative providers?
Choose one of many models on openrouter
Openrouter has the same policy (minimum top up, 1 year expiry). However Azure appears to invoice post usage.