I have been trying to solve this problem for a few days now and it’s proving to be way harder than it should be, so I want to check if I’ve missed anything obvious.
I want to put in monitoring so that if devices silently go dead I get prompted to investigate. Example reasons for this scenario include battery powered devices running flat, removal of one mesh network device damaging connectivity to another, or power cuts/spikes causing some mains devices to get locked up and need a power cycle. I have monitoring of battery degradation, but sometimes devices lose the ability to function before they get chance to report a low battery level - and some of these failures affect mains powered devices as much as battery ones.
I have investigated ‘Entity availability’ in HACS but it seems to need a significant amount of manual configuration, and the maximum configurable timeout doesn’t go high enough for (eg) a window sensor that might go days without checking in.
My ideal solution would be something that operates at device level, monitoring them across all their entities and attributes and watching for any signs of life, raising an alert if none is detected within a given timeframe. Ideally I’d like something that autodiscovers new devices to avoid manual admin.
This seems such an obvious need I’m surprised it isn’t built in to HA already, or that there is not an integration to handle it - or have I missed something?
I have put a longer update/conclusion in a post below, but TLDR:
Doing this for one device or one type of device is pretty easy. Doing it for an entire heterogeneous network is a mess.
The Proper Fix: I think HA needs to modify its developer guidance to integration maintainers to request they provide a health flag per-device. How this is determined is up to the integration using the best capabilities that transport/hardware provides, and there could be several tiers of accuracy along the lines of the bronze/silver/gold/platinum tiering already in use. This would be extra work for the maintainers but not much, given the knowledge they already have in their area, and it would abstract 99% of the complexity away from the user and deliver the zero-config dream
In short, get a list of unavailable entities, exclude some things and map that to a unique list of devices. You’ll see in the messages there are a couple of trucks involved, which I got to by analysing the device registry.
There might be other or better ways of doing this — I don’t know. I originally had this automation but for entities only, but that became annoying pretty quickly with the duplication involved.
I don’t know how this will work when there are subdevices involved.
  - alias: "Unavailable Devices"
    initial_state: true
    variables:
      # excluding update entities, because for some reason that can be unavailable for longer/more frequently
      # compared to other entities of the same devies. perhaps it has to do with how frequent the checks are,
      # so it remains unavailable until the next check and not when the device has become available again.
      # todo: once the water pulse counter has been installed it must be removed here.
      unavailable_devices: >-
        {{
          state_attr('sensor.unavailable_entities', 'unavailable')
            | reject('match', 'update.*')
            | reject('match', '.*test_.*')
            | reject('match', '.*water_pulse_counter.*')
            | reject('match', '.*sonoff_basic.*')
            | map('device_id')
            | reject('none')
            | select('is_device_attr', 'disabled_by', None)
            | unique
            | sort
            | list
        }}
    trigger:
      - platform: time
        at:
          - "06:30"
          - "09:30"
          - "12:30"
          - "18:30"
          - "21:30"
    condition:
      - condition: template
        value_template: "{{ unavailable_devices | count > 0 }}"
    action:
      - service: notify.mobile_app_ceres
        data:
          title: "⚠️ Unavailable Devices"
          message: >-
            {%- from 'utilities.jinja' import get_integration -%}
            The following devices are unavailable:
            {%- for device_id in unavailable_devices %}
              {%- set integration = get_integration(device_id) -%}
              {%- set name_by_user = device_attr(device_id, 'name_by_user') -%}
              {%- set name = name_by_user if name_by_user else device_attr(device_id, 'name') %}
              - {{ name }}{% if integration %} ({{ integration }}){% endif %}
            {%- endfor %}
          data:
            group: "devices"
            tag: "unavailable-devices"
            url: homeassistant://navigate/lovelace-system/devices
I have an automation that alerts me if any entity goes unavailable for 30 minutes. Unfortunately it is difficult to copy while on mobile. I’ll paste it here tomorrow.
Similar to the one above but it uses a template sensor and has an easily editable ignore list.
Lots of contributions from everyone but I wasn’t able to find anything that did what I wanted, so despite it being one of the first ideas suggested (on Reddit) and my least favourite idea in principle, I ended up writing something with Claude. Functionally I am now pretty happy with what I’ve got but I’m not going to share it (unless anyone particularly asks) as the internet does not need another pile of loosely human-understood AI waffle tailored to one individual’s requirements. However, here’s what I learned in the process. I am 100% convinced that this should be a core feature in HA, I hope someone in the team gets inspired to tackle the issue properly. This update was NOT written by Claude.. Claude has better grammar than me.
Problem statement:
I have a complex home automation system of sensors and actuators across multiple device types and integrations, some of which are directly human facing, some of which feed automations and fuzzier logic, and some are just data sources for archival. I have no way of being alerted if one of these devices goes offline, which means that failures are always an inconvenience - I only notice when they impact me.
Desired outcome:
A zero compulsory config monitoring system for devices (not entities) that alerts me to investigate if one stops doing what it’s supposed to do.
Characteristics of a BAD solution:
Manual enrolment required - if I’ve got a device enabled in HA it should be a safe bet that I want it to be working, I shouldn’t have to set each new device up.
False positives and noise - flapping at restart time, or overly twitchy thresholds mean getting buried in regular false alarms and people just learn to ignore them.
False negatives - the whole point of this is to remove mental load from the user so if the system says something’s working I should be able to trust it.
Excess bespoke configuration - if I need a whole family of similar automations/templates/whatever to get this to work, they will get out of sync with respect to bug fixes and improvements and then we’re back at a system I can’t really trust.
Why is this so difficult?
There is no consistent indicator of ‘this device is working’ in Home Assistant. Entities have ‘last_changed’ and ‘last_updated’ attributes, but those are on entities rather than the device and they are from Home Assistant’s perspective, which means that updated timestamps don’t always translate to confirmation that the device is operating. Eg: retained MQTT messages can make stale real-world values look new to Home Assistant.
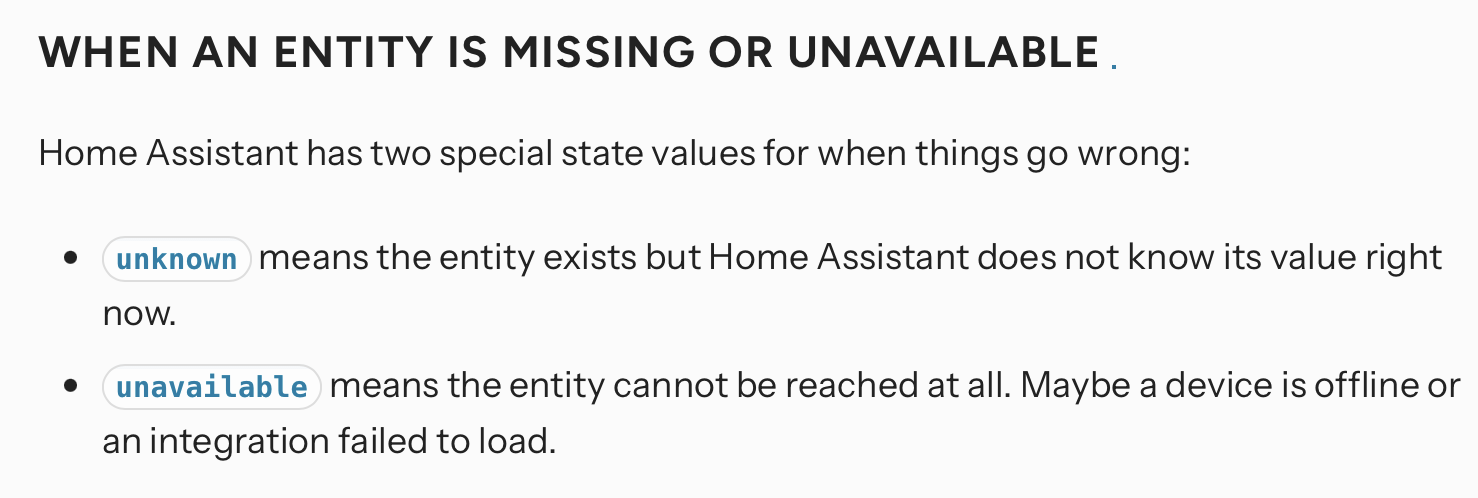
Entity value states of ‘unavailable’ and ‘unknown’ are superficially a good fit (and are what a lot of the proposed solutions depended on) but they create false signals in my experience, and there is no concrete pattern for which entity of a device should be tracked, implying bespoke configuration per device that is also fragile to entity renames.
Monitoring of payload (ie, not meta) data from the device for changes works around ‘unavailable’ flappery, but boiling down entity-level data to a device-level indication is not fire-and-forget as it sounds. You can’t just iterate over all of the entities because some of them may reflect state within the integration rather than the device itself and artificially bump the freshness signal. This means that for this approach to work not only do you need semi-complex (resource intensive?) iterative logic, but it needs configuration for each device type, and only long duration testing really shows if you’ve got it right.
A further issue is that some devices that have no need to report in may not update their payload values for a long time - an example being the Wiser signal booster/plugs, which only report in if they are powered on/off at the wall or the physical button is pushed.
Some integrations do provide health information directly.. ish. Eg:
z-waveJS provides Node Status, which sounds like it is what we’re looking for… BUT z wave handles battery devices and mains devices differently. For mains devices Node Status seems reliable, but for battery devices it will only ever say ‘asleep’ and never determine that the node has died unless that node is transmitted to (which is itself a flawed test, as battery devices can wake up and receive messages very infrequently).
Zigbee (via zigbee2mqtt) provides a last seen, BUT the value itself goes ‘unavailable’ when the device does, so you need a bespoke treatment to retain the last ‘non unavailable’ value. Plus, some devices go offline as part of their normal lifecycle (eg, Hue bulbs if powered off at the wall), so while determining network availability via ZB2MQTT is relatively easy, determining whether it’s a problem is another bespoke case.
Wiser (which is zigbee underneath) does not expose this information at all BUT you can turn on the signal strength indicator which fluctuates enough to provide an aliveness-reading.
I can only test with what I’ve got, so while I’m content that the above is accurate for me, it could be that a different brand of (eg) Zigbee devices introduces another behaviour.
To be useful the alerting thresholds need to be different per-device type - eg, a battery window sensor may legitimately go much longer without checking in than a mains powered device. Bumping up the threshold for all devices to allow for the quiet ones is not a good fit due to the larger window before an issue is detected, especially since many mains devices have a mesh boosting function and their absence might degrade the whole network.
What I wound up with:
Nearly 800 lines of yaml across templates, automations, sensors, scripts, dashboard cards and alert2 config, including documentation. I am NOT delighted with this aspect of the outcome. However, that gives me:
6 distinct tracking categories indicated by labels applied to devices: wiser battery, wiser mains, http services, zwave battery, zwave mains, zigbee intermittent. Applying labels doesn’t meet the zero config/enrolment requirement, but it is a relatively light compromise.
Each category tracks device health using whatever metric works best for that category (in order of desirability); the integration (eg zwave mains devices, wiser battery devices), specific trustworthy, high-chattiness entities (eg signal strength), or a hash of the entity values as a last resort.
Once labelled the monitoring of each device is automatic, with per-category timeout thresholds generating alerts via alert2 (Already in use, and I wanted to build on it because of the free repeat notifications, exponential backoff, anti flapping features, etc.)
Some auxiliary functionality like a self check of the watchdog itself, an ability to generate a one off report in a persistent message, an automation to ping all zwave devices to prompt a sign of life once a day, etc.
So I think the problem is (for me) solved, but I look forward to the day when 700 of those lines of code can go in the bin.
PS. I am not positioning myself as an HA expert, and this picture accumulated over 2 days of off and on experimentation so apologies if there is the odd erroneous or misremembered statement.
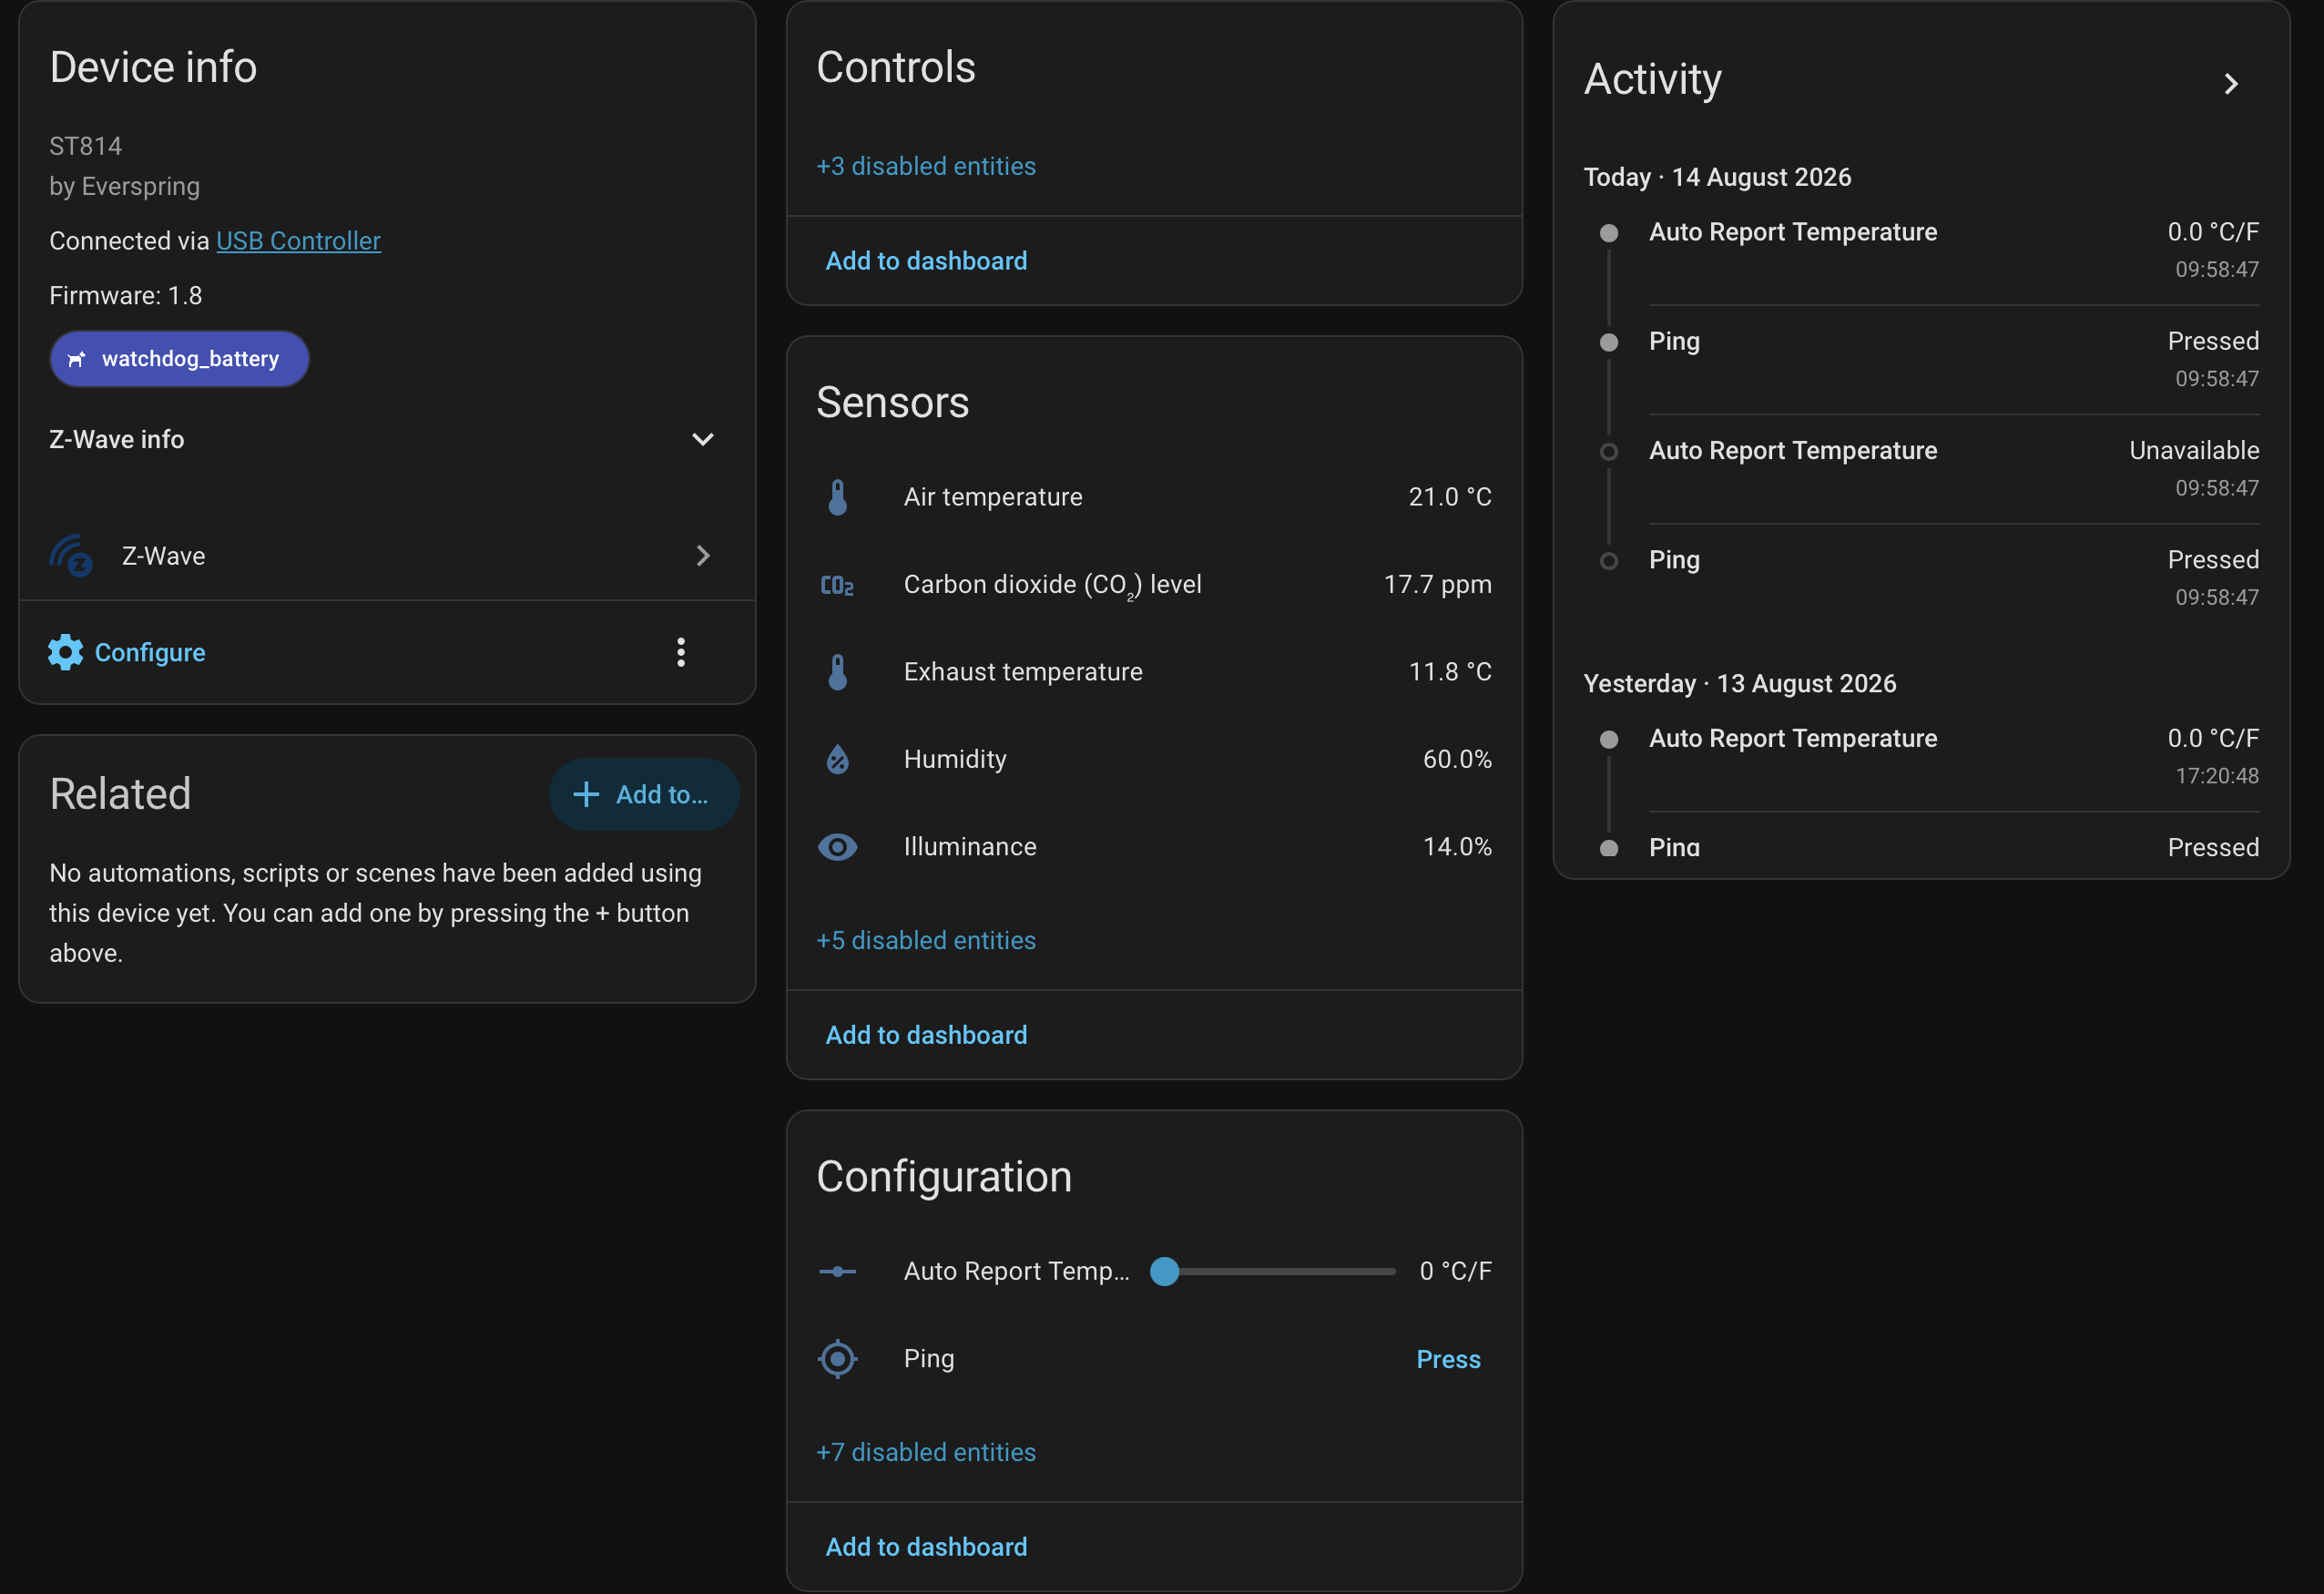
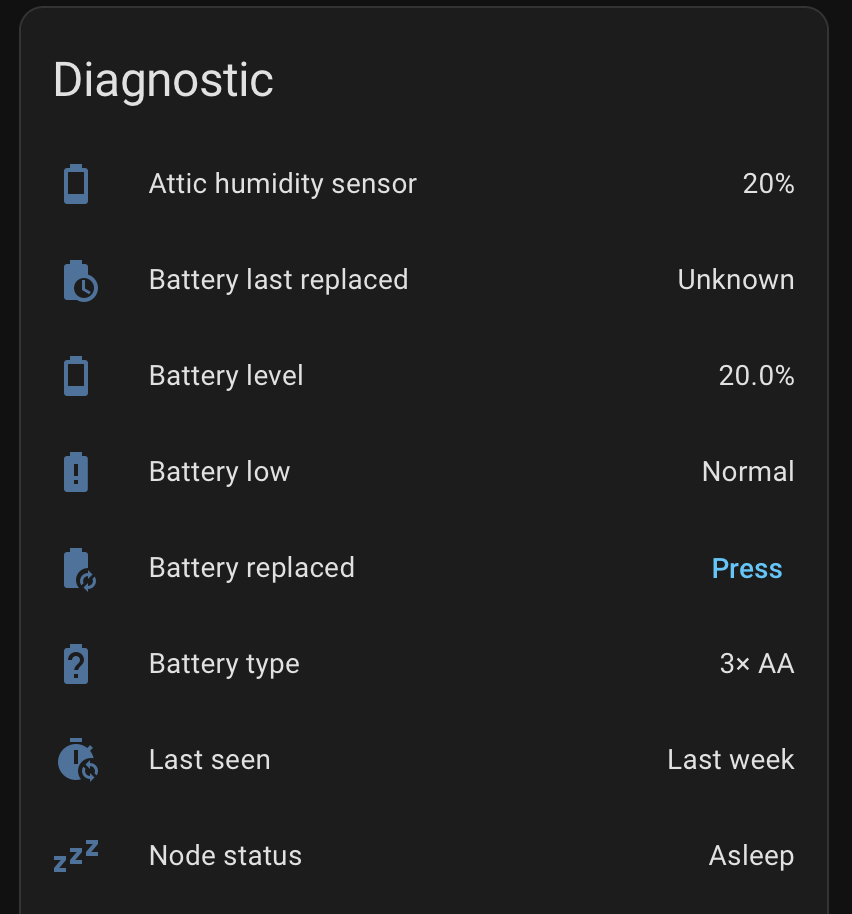
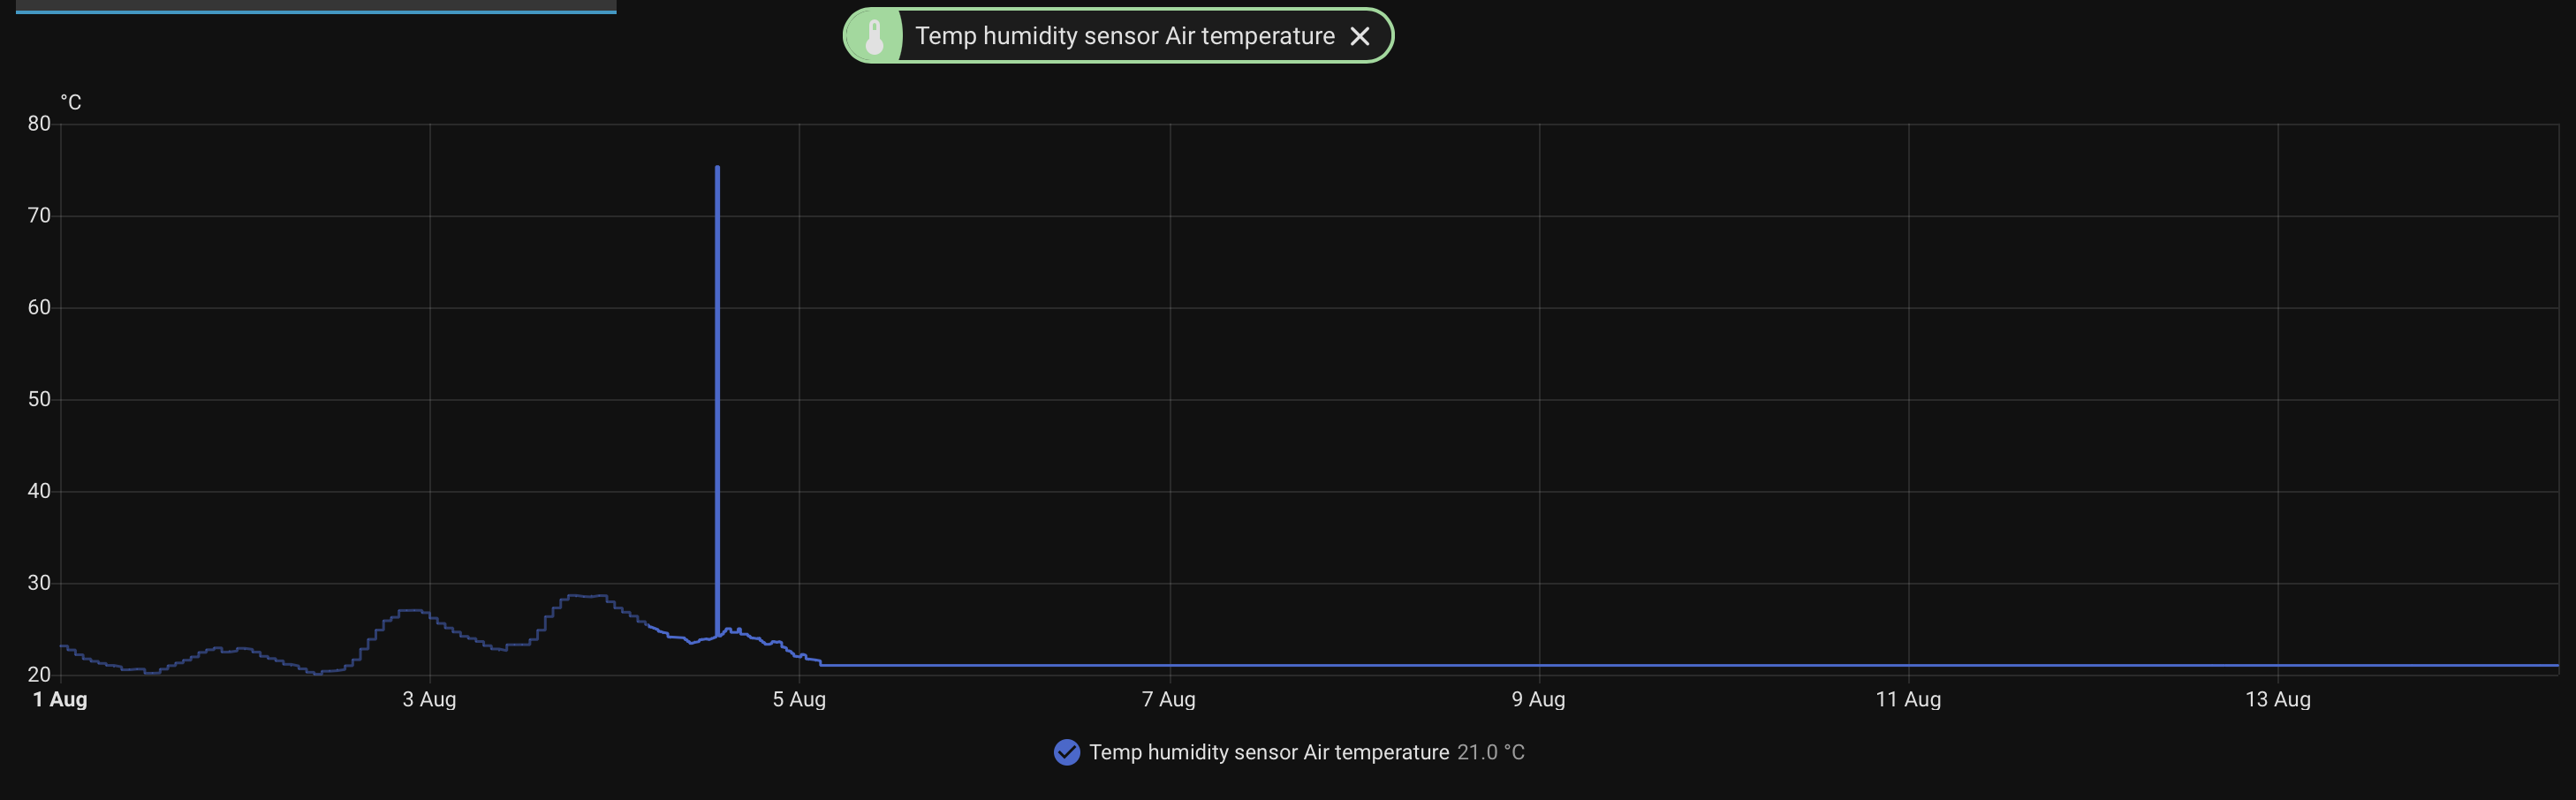
Even though it records that the last activity was a week ago.
And Home Assistant has been repeatedly restarted during that window, and the device has been pinged - but I don’t think the transport will report a failure for a ping to a battery device because of the periodic wake ups. All the payload data entities for this device claim to be not-unavailable.
So could I detect status by checking for ‘unavailable’ on ‘Auto Report Temperature’? Apparently so (based on this activity snapshot), but that is fragile to that entity being renamed or removed, and bespoke config in that many devices won’t have that entity and I’d have to determine an alternative, and if you take a step back - it’s a gap that this is necessary in the first place. The lack of a standardised ‘health’ flag is as if HA left the fetching methodology and normalisation of every sensor to the user instead of encapsulating it so you don’t have to even think about it.
And no criticism of your, or anyone else’s, provided solution was intended - they just don’t do what I needed across the portfolio of devices I have.
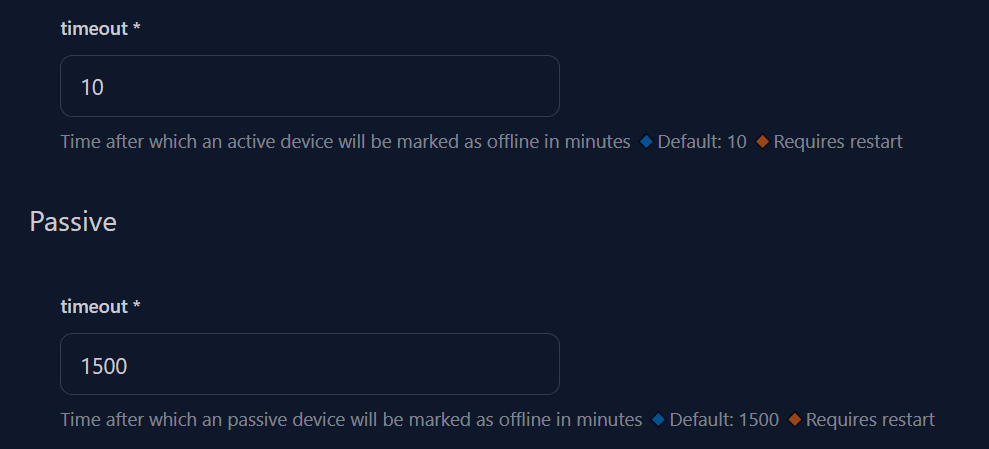
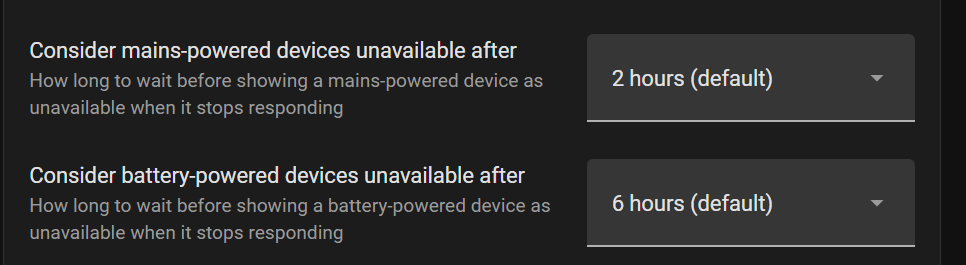
I don’t do zwave but zigbee has two time-out settings that will mark the device unavailable after if it has received no updated from the device, one for battery (1500 minutes by default) and one for mains powered devices (10 minutes by default). Does zwave not have this?
Speaking from a few years of very inexpert experience, no, I don’t think so. It will report node death if it fails to deliver a message, but battery devices generally only transmit when they have something to say and/or wake up and poll on a very infrequent basis, and I haven’t seen anything in the integration that offers to apply an inactivity timeout.
I only have Hue zigbee devices (all mains) via zigbee2mqtt, and Wiser (mains and battery) via its own integration. The hue bulbs do have a ‘last seen’ (once I worked out how to turn that on in the z2m gui), but that value itself goes unavailable at the same time the bulb does which seems a weird enough behaviour that perhaps it counts as a bug in the integration, now that I think about it.. Corrected in post below.
For another example of a difficult child, the HP printer integration that I use provides only passive, read-only sensors - I don’t think there’s a single thing it can do to provoke activity - and the nature of a printer means it can go a long time between any change to its sensors so I don’t think there is currently any way an end user could health monitor it. However, since it’s a polling based integration it would be really simple for it to provide a health flag based on whether it was able to poll for updated information.
At the risk of beating a dead horse, my point is not that none of these things are impossible to deal with at user level, just that the fact that we have to deal with them is incongruous with the efforts that the HA team have made over the last year(s) to make everything easy to use. The work involved in creating the GUI automation editor, for example, must have been absolutely massive compared to what would be needed to put a standardised treatment on this.
I only have Hue zigbee devices (all mains) via zigbee2mqtt, and Wiser (mains and battery) via its own integration. The hue bulbs do have a ‘last seen’ (once I worked out how to turn that on in the z2m gui), but that value itself goes unavailable at the same time the bulb does which seems a weird enough behaviour that perhaps it counts as a bug in the integration, now that I think about it.
Having played around with this it’s not as simple as I thought - I think the ‘last seen’ value goes ‘unavailable’ if the message is no longer available on the MQTT broker, not simply because the light has been turned off. I have found a device that still has a last seen value in zigbee2mqtt but shows ‘unavailable’ in HA.
This is a manifestation of what I meant by this:
There is no consistent indicator of ‘this device is working’ in Home Assistant. Entities have ‘last_changed’ and ‘last_updated’ attributes, but those are on entities rather than the device and they are from Home Assistant’s perspective, which means that updated timestamps don’t always translate to confirmation that the device is operating. Eg: retained MQTT messages can make stale real-world values look new to Home Assistant.
What HA is displaying makes sense from HA’s perspective - ‘There is no information on this available to me’, but requires an MQTT-specific workaround to use that value for health tracking.
Back in the Groovy days, SmartThings monitored device health in an opt-in manner, where device drivers would have to decide what “not healthy” meant on a 1-by-1 basis. Devices would support the healthCheck capability and emit a clock value (seconds since epoch in GMT) of when a device should be considered no longer healthy. Drivers would calculate this timeout value differently depending on the semantics of the device. For zwave sleepy devices, it tended to be “now + 2 * wakeup period + 5 minutes”, so a device would have to miss 2 checkins (plus a few minutes for clock skew) before it would be marked as offline.
With the Edge refactoring, ST took away the ability of drivers to calculate their own health status and instead pushed it to the internal system to try and calculate. Its been hit or miss with various implementations tried over the last X firmware releases. Check Your Device's Health | Developer Documentation | SmartThings
Hubitat decided to learn from the healthCheck ST mess and just doesn’t try to do it. There have been many threads on the forum discussing it and people have developed some addon solutions, but each is different. This one is a newer one thats interesting: [RELEASE] Device Health Monitor - Custom Apps - Hubitat
Its a complex problem and one that I can see that a one-size-fits-all approach doesn’t work in practice and tends to make a lot of noise or false positive alerts.
Zwave:
Sleepy devices could use their wakeup period as a good indicator of health.
Non sleepy devices tend to need polling of some state or attribute, as they don’t send any unsolicited events unless a local state changes (switch toggled, button pressed, etc).
Zigbee:
Sleepy devices usually support a minimum reporting period for the values they report, be it temperature or battery status or whatever. The coordinator could calculate the timeout value based on the soonest of these reporting periods.
Powered devices sometimes support setting a reporting period on an attribute, but often not. Items like smart plugs often don’t implement the timers or memory storage to track reporting periods, so those devices would need polling.
Other device types would all have their own semantics. ESPHome seems to implement a watchdog heartbeat type thing as it bubbles up online/offline status.
I’ve love to see a clean HA implementation for health monitoring, especially for the more critical devices like leak sensors or freezer temperature monitors.