My Journey to a reliable and enjoyable locally hosted voice assistant

your information is not up to date
extended_openai_conversation/custom_components/extended_openai_conversation/conversation.py at 5c5cd4c106450f65ab5ad487c7491b34916cfa70 · jekalmin/extended_openai_conversation · GitHub

Also, the provided context is not directly related to the conversation integration. It is determined by the module used (no_control/assist/mcp/…).

your information is not up to date

Thats a tad disingenuous given that is neither in the current release, nor even merged to main.

Infact, you can look at the OpenAI chat completions endpoint call and response handling here, again in the main branch:

So no, it seems my information is up to date. It does not however take into account unreleased work.

Also, the provided context is not directly related to the conversation integration. It is determined by the module used (no_control/assist/mcp/…).

Under normal integrations, yes, but I have Extended OpenAI Conversation installed, the latest release, and those options do not exist. The dev may be working to bring it up to date (after having abandoned it for 10 months or so last year, leaving it in a broken state), but the current release does not do handle it this way.

You can install existing beta versions through hacs without any effort.
Don’t worry about timing; I added streaming to my version of conversation integration before anyone else, but that doesn’t matter🙃.
The main thing is that there are plenty of alternative solutions for users.

So I realized I also needed to recompile llama.cpp as I was missing out on features on that end of things too (wanting to get vision working with Frigate so I can get Ollama off my system altogether since it no longer supports my GPU).

Well, updated llama.cpp to the latest build and figured I’d try out the “latest & greatest” models available and WOW…what an absurd difference.

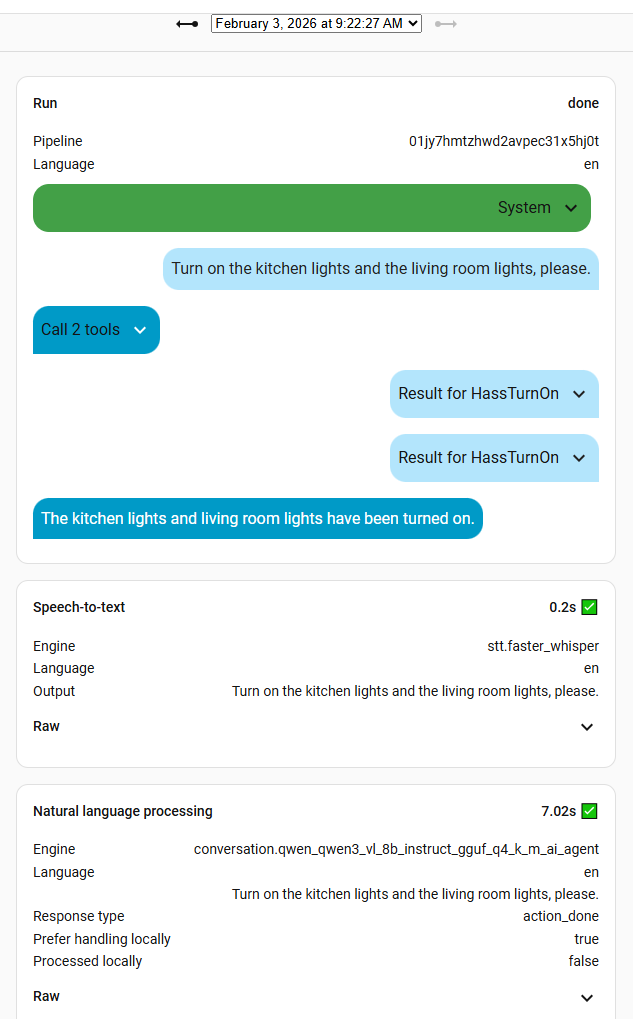
Actions are taken in 1/3’rd to 1/2 of the time than my old llama.cpp build and old model, and it’s even more accurate than before, even with deliberately confusing requests (here is a screenshot, not of a deliberately confusing one, but just to show the speed):

For anybody who is playing around and likes to try different models, I’m using this one for HA now:

And this one (loaded onto the same GPU simultaneously as the other but at a different port) is the one I’m using for Frigate (not really related to this thread, but I know the OP is a frigate user [bit of an understatement there lol]) and there are probably others as well:

They’re incredible models and combined with the latest llama.cpp…I’m just blown away.

Just to come back and touch on this, I’ve gotten everything updated (llama.cpp, tried both HACS integrations and the extended_openai_conversation is so much faster for me…though the “hass local openai” one no longer takes 25+ seconds but it’s nowhere near as fast still).

Here are my tests from earlier:

extended openai

hass local openai

While the second screenshot looks entirely different than the first, I can assure you they both completed the tasks successfully.

EDIT: Just to add, I asked the same command of each integration three times before taking a screenshot just to be sure everything was fully and completely loaded. Screenshots came from each after the third time.

I just run llama.cpp in docker pulling from their ghcr images, so update is as simple as docker compose pull && docker compose up -d

I am curious why you run them separately, I just use Qwen3-VL for everything. Would free up more VRAM for context or other things

It would be great to see a comparison from the llama.cpp logs, primarily to see the context size, context processing speed, generation size, generation speed of both

for example:

prompt eval time =    3314.86 ms /  4190 tokens (    0.79 ms per token,  1264.01 tokens per second)
       eval time =    1207.20 ms /   148 tokens (    8.16 ms per token,   122.60 tokens per second)
      total time =    4522.06 ms /  4338 tokens
slot      release: id  0 | task 4299 | stop processing: n_tokens = 4341, truncated = 0
srv  log_server_r: done request: POST /v1/chat/completions 192.168.50.105 200

I’ll have to look to see if my GPU is compatible with the docker images. When I first setup llama.cpp I had all kinds of issues getting it to work.

Because it’s so much faster having the 8B model for HomeAssistant. If I point it to the 32B model that same exact command (from the screenshot) that takes 1.47 seconds then takes 4.69 seconds.

It takes about 9 seconds for Frigate to return a summary of my security cameras using the 32B model, but the accuracy of the 32B model for the cameras is just so much better than a smaller model, and I don’t care about the speed of notification I get on my phone about the cameras. Not much is going to happen in the 9 seconds between when whatever was “seen” on the camera and when I get the notification.

When I’m interacting with my house, the ability to have what I asked be completed in a second/second and a half is way more important to me and the 8B model is more than accurate for the job it’s performing.

With regard to context, I actually still have room to spare on my GPU even while setting my context windows WAY larger than needed for both Frigate and HomeAssistant (and the GPU isn’t doing anything else…it’s just in there for HA and Frigate).

I’ll give this a shot tomorrow, curious to see those results myself. Something is happening to make one that much slower than the other, but I don’t know what it is. That would definitely give some good insight (and I’ll post it to “share with the group” so to speak haha).

That’s likely because you are running the dense 32B, that is why I use the 30B-A3B as it is a mixture of experts model, which means it is quite good while still being very fast

Alright, spent about an hour doing this (would be a lot easier if I didn’t have to uninstall one to install the other lo, but in any case, it’s done).

I ended up having to do this four times instead of two…because the first set of results grabbing the responses only lead to more questions than answers.

I have 36 entities exposed and repeated the phrase “turn off hallway lights and kitchen lights” three times for each integration, taking the logs from the third time each time. During this run for each (and the subsequent dual run, as I needed to repeat) Extended OpenAI is around 1.4 seconds to process and Hass Local OpenAI is 7+ seconds to process. I just copy/pasted my prompt from Extended OpenAI into Hass Local.

Have a look:

Extended OpenAI Conversation logs:

Feb 04 08:03:02 mediaserver bash[1612383]: Template supports tool calls but does not natively describe tools. The fallback behaviour used may produce bad results, inspect prompt w/ --verbo>
Feb 04 08:03:02 mediaserver bash[1612383]: srv  params_from_: Chat format: Hermes 2 Pro
Feb 04 08:03:02 mediaserver bash[1612383]: slot get_availabl: id  3 | task -1 | selected slot by LCP similarity, sim_best = 0.991 (> 0.100 thold), f_keep = 1.000
Feb 04 08:03:02 mediaserver bash[1612383]: slot launch_slot_: id  3 | task -1 | sampler chain: logits -> ?penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> ?top-p -> min-p -> ?xtc >
Feb 04 08:03:02 mediaserver bash[1612383]: slot launch_slot_: id  3 | task 302 | processing task, is_child = 0
Feb 04 08:03:02 mediaserver bash[1612383]: slot update_slots: id  3 | task 302 | new prompt, n_ctx_slot = 7168, n_keep = 0, task.n_tokens = 2029
Feb 04 08:03:02 mediaserver bash[1612383]: slot update_slots: id  3 | task 302 | n_tokens = 2011, memory_seq_rm [2011, end)
Feb 04 08:03:02 mediaserver bash[1612383]: slot update_slots: id  3 | task 302 | prompt processing progress, n_tokens = 2029, batch.n_tokens = 18, progress = 1.000000
Feb 04 08:03:02 mediaserver bash[1612383]: slot update_slots: id  3 | task 302 | prompt done, n_tokens = 2029, batch.n_tokens = 18
Feb 04 08:03:02 mediaserver bash[1612383]: slot init_sampler: id  3 | task 302 | init sampler, took 0.11 ms, tokens: text = 2029, total = 2029
Feb 04 08:03:03 mediaserver bash[1612383]: slot print_timing: id  3 | task 302 |
Feb 04 08:03:03 mediaserver bash[1612383]: prompt eval time =      88.83 ms /    18 tokens (    4.94 ms per token,   202.63 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:        eval time =    1036.00 ms /    62 tokens (   16.71 ms per token,    59.85 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:       total time =    1124.84 ms /    80 tokens
Feb 04 08:03:03 mediaserver bash[1612383]: slot      release: id  3 | task 302 | stop processing: n_tokens = 2090, truncated = 0
Feb 04 08:03:03 mediaserver bash[1612383]: srv  update_slots: all slots are idle
Feb 04 08:03:03 mediaserver bash[1612383]: srv  log_server_r: done request: POST /v1/chat/completions 192.168.0.104 200
Feb 04 08:03:03 mediaserver bash[1612383]: Template supports tool calls but does not natively describe tools. The fallback behaviour used may produce bad results, inspect prompt w/ --verbo>
Feb 04 08:03:03 mediaserver bash[1612383]: srv  params_from_: Chat format: Hermes 2 Pro
Feb 04 08:03:03 mediaserver bash[1612383]: slot get_availabl: id  3 | task -1 | selected slot by LCP similarity, sim_best = 0.989 (> 0.100 thold), f_keep = 1.000
Feb 04 08:03:03 mediaserver bash[1612383]: slot launch_slot_: id  3 | task -1 | sampler chain: logits -> ?penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> ?top-p -> min-p -> ?xtc >
Feb 04 08:03:03 mediaserver bash[1612383]: slot launch_slot_: id  3 | task 365 | processing task, is_child = 0
Feb 04 08:03:03 mediaserver bash[1612383]: slot update_slots: id  3 | task 365 | new prompt, n_ctx_slot = 7168, n_keep = 0, task.n_tokens = 2114
Feb 04 08:03:03 mediaserver bash[1612383]: slot update_slots: id  3 | task 365 | n_tokens = 2090, memory_seq_rm [2090, end)
Feb 04 08:03:03 mediaserver bash[1612383]: slot update_slots: id  3 | task 365 | prompt processing progress, n_tokens = 2114, batch.n_tokens = 24, progress = 1.000000
Feb 04 08:03:03 mediaserver bash[1612383]: slot update_slots: id  3 | task 365 | prompt done, n_tokens = 2114, batch.n_tokens = 24
Feb 04 08:03:03 mediaserver bash[1612383]: slot init_sampler: id  3 | task 365 | init sampler, took 0.12 ms, tokens: text = 2114, total = 2114
Feb 04 08:03:03 mediaserver bash[1612383]: slot print_timing: id  3 | task 365 |
Feb 04 08:03:03 mediaserver bash[1612383]: prompt eval time =      91.53 ms /    24 tokens (    3.81 ms per token,   262.21 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:        eval time =     187.35 ms /    12 tokens (   15.61 ms per token,    64.05 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:       total time =     278.88 ms /    36 tokens
Feb 04 08:03:03 mediaserver bash[1612383]: slot      release: id  3 | task 365 | stop processing: n_tokens = 2125, truncated = 0
Feb 04 08:03:03 mediaserver bash[1612383]: srv  update_slots: all slots are idle
Feb 04 08:03:03 mediaserver bash[1612383]: srv  log_server_r: done request: POST /v1/chat/completions 192.168.0.104 200

Hass Local OpenAI:

Feb 04 08:15:07 mediaserver bash[1612383]: Template supports tool calls but does not natively describe tools. The fallback behaviour used may produce bad results, inspect prompt w/ --verbo>
Feb 04 08:15:07 mediaserver bash[1612383]: srv  params_from_: Chat format: Hermes 2 Pro
Feb 04 08:15:07 mediaserver bash[1612383]: slot get_availabl: id  2 | task -1 | selected slot by LRU, t_last = 80846605254
Feb 04 08:15:07 mediaserver bash[1612383]: slot launch_slot_: id  2 | task -1 | sampler chain: logits -> ?penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> top-p -> min-p -> ?xtc ->
Feb 04 08:15:07 mediaserver bash[1612383]: slot launch_slot_: id  2 | task 680 | processing task, is_child = 0
Feb 04 08:15:07 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | new prompt, n_ctx_slot = 7168, n_keep = 0, task.n_tokens = 5567
Feb 04 08:15:07 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | n_tokens = 0, memory_seq_rm [0, end)
Feb 04 08:15:07 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | prompt processing progress, n_tokens = 2048, batch.n_tokens = 2048, progress = 0.367882
Feb 04 08:15:07 mediaserver bash[1612383]: decode: failed to find a memory slot for batch of size 2048
Feb 04 08:15:07 mediaserver bash[1612383]: srv  try_clear_id: purging slot 3 with 5820 tokens
Feb 04 08:15:07 mediaserver bash[1612383]: slot prompt_clear: id  3 | task -1 | clearing prompt with 5820 tokens
Feb 04 08:15:07 mediaserver bash[1612383]: srv  update_slots: failed to find free space in the KV cache, retrying with smaller batch size, i = 0, n_batch = 2048, ret = 1
Feb 04 08:15:08 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | n_tokens = 2048, memory_seq_rm [2048, end)
Feb 04 08:15:08 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | prompt processing progress, n_tokens = 4096, batch.n_tokens = 2048, progress = 0.735764
Feb 04 08:15:11 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | n_tokens = 4096, memory_seq_rm [4096, end)
Feb 04 08:15:11 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | prompt processing progress, n_tokens = 5567, batch.n_tokens = 1471, progress = 1.000000
Feb 04 08:15:11 mediaserver bash[1612383]: slot update_slots: id  2 | task 680 | prompt done, n_tokens = 5567, batch.n_tokens = 1471
Feb 04 08:15:11 mediaserver bash[1612383]: slot init_sampler: id  2 | task 680 | init sampler, took 0.30 ms, tokens: text = 5567, total = 5567
Feb 04 08:15:14 mediaserver bash[1612383]: slot print_timing: id  2 | task 680 |
Feb 04 08:15:14 mediaserver bash[1612383]: prompt eval time =    5695.84 ms /  5567 tokens (    1.02 ms per token,   977.38 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:        eval time =    1055.30 ms /    60 tokens (   17.59 ms per token,    56.86 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:       total time =    6751.14 ms /  5627 tokens
Feb 04 08:15:14 mediaserver bash[1612383]: slot      release: id  2 | task 680 | stop processing: n_tokens = 5626, truncated = 0
Feb 04 08:15:14 mediaserver bash[1612383]: srv  update_slots: all slots are idle
Feb 04 08:15:14 mediaserver bash[1612383]: srv  log_server_r: done request: POST /v1/chat/completions 192.168.0.104 200
Feb 04 08:15:14 mediaserver bash[1612383]: Template supports tool calls but does not natively describe tools. The fallback behaviour used may produce bad results, inspect prompt w/ --verbo>
Feb 04 08:15:14 mediaserver bash[1612383]: srv  params_from_: Chat format: Hermes 2 Pro
Feb 04 08:15:14 mediaserver bash[1612383]: slot get_availabl: id  2 | task -1 | selected slot by LCP similarity, sim_best = 0.968 (> 0.100 thold), f_keep = 1.000
Feb 04 08:15:14 mediaserver bash[1612383]: slot launch_slot_: id  2 | task -1 | sampler chain: logits -> ?penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> top-p -> min-p -> ?xtc ->
Feb 04 08:15:14 mediaserver bash[1612383]: slot launch_slot_: id  2 | task 743 | processing task, is_child = 0
Feb 04 08:15:14 mediaserver bash[1612383]: slot update_slots: id  2 | task 743 | new prompt, n_ctx_slot = 7168, n_keep = 0, task.n_tokens = 5810
Feb 04 08:15:14 mediaserver bash[1612383]: slot update_slots: id  2 | task 743 | n_tokens = 5626, memory_seq_rm [5626, end)
Feb 04 08:15:14 mediaserver bash[1612383]: slot update_slots: id  2 | task 743 | prompt processing progress, n_tokens = 5810, batch.n_tokens = 184, progress = 1.000000
Feb 04 08:15:14 mediaserver bash[1612383]: slot update_slots: id  2 | task 743 | prompt done, n_tokens = 5810, batch.n_tokens = 184
Feb 04 08:15:14 mediaserver bash[1612383]: slot init_sampler: id  2 | task 743 | init sampler, took 0.32 ms, tokens: text = 5810, total = 5810
Feb 04 08:15:14 mediaserver bash[1612383]: slot print_timing: id  2 | task 743 |
Feb 04 08:15:14 mediaserver bash[1612383]: prompt eval time =     271.77 ms /   184 tokens (    1.48 ms per token,   677.05 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:        eval time =     197.38 ms /    12 tokens (   16.45 ms per token,    60.79 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:       total time =     469.15 ms /   196 tokens
Feb 04 08:15:14 mediaserver bash[1612383]: slot      release: id  2 | task 743 | stop processing: n_tokens = 5821, truncated = 0
Feb 04 08:15:14 mediaserver bash[1612383]: srv  update_slots: all slots are idle
Feb 04 08:15:14 mediaserver bash[1612383]: srv  log_server_r: done request: POST /v1/chat/completions 192.168.0.104 200

So why did I have to do it again? Well, because I could see there was a massive token discrepancy from one to the other. I wanted to see what exactly was getting passed so I had to enable “verbose logging” within llama-server and do the whole thing again.

If you’re interested in looking at the nearly 4k lines produced by Hass Local let me know. I also have the corresponding log file for Extended OpenAI which is just a little over 1200 lines. I’d upload them here but it won’t allow me to and I don’t want to take the time to upload them elsewhere and share the link here unless someone feels it’s worth looking at.

Suffice it to say though, I’ll be sticking with Extended OpenAI for the time being.

Dang, didn’t realize prompt processing was that much slower on AMD than Nvidia

prompt eval time =    1901.04 ms /  6841 tokens (    0.28 ms per token,  3598.57 tokens per second)
       eval time =      34.43 ms /     4 tokens (    8.61 ms per token,   116.19 tokens per second)
      total time =    1935.46 ms /  6845 tokens
slot      release: id  2 | task 10904 | stop processing: n_tokens = 8136, truncated = 0

Yeah, drawback of being as old of a card as it is, I can’t even update rOCM drivers as it’s no longer supported.

But, I’m still super happy with the speeds I’m now getting and having the 32gb of VRAM is a worthwhile trade off for me. Looks like based on the logs you posted if I had everything setup exactly as I do now but switched over to nvidia, instead of the LLM processing my request in 1.4 seconds it would probably be close to .7 or so seconds.

As tempting as sub-second sounds to me, I can’t justify the purchase…yet hahaha

EDIT: you just posted new logs, looks like it would be even faster than .7 hahaha

Makes sense, and yeah just to clarify the first logs I posted were actually a vision request from Frigate. The more recent ones are indeed from HA

Yeah, it would be probably around .5-ish if I had the card you do (what card are you using again btw?).

Also, if you ever feel like going the pain in the behind that it is to try out extended OpenAI I’d be curious to see the result (if I don’t break down and buy an NVIDIA card to see for myself haha).

I will say it supports the “pirate weather” entities “out of the box” when you expose them. I didn’t have to do anything elaborate to get weather or even play music from musicassistant using it.

3090 that is slightly underclocked to reduce power usage

Taking a deeper look at your logs and it appears to be a caching problem, the follow up queries seem to be similar speeds.

Here we can see that the extended openai prompt is ~2000 tokens and the follow up request only used an additional 24 tokens.

Feb 04 08:03:03 mediaserver bash[1612383]: prompt eval time =      91.53 ms /    24 tokens (    3.81 ms per token,   262.21 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:        eval time =     187.35 ms /    12 tokens (   15.61 ms per token,    64.05 tokens per second)
Feb 04 08:03:03 mediaserver bash[1612383]:       total time =     278.88 ms /    36 tokens
Feb 04 08:03:03 mediaserver bash[1612383]: slot      release: id  3 | task 365 | stop processing: n_tokens = 2125, truncated = 0

Meanwhile for hass local ai we can see that the entire prompt is ~5000 tokens and the follow up request used an additional 184 tokens.

Feb 04 08:15:14 mediaserver bash[1612383]: prompt eval time =     271.77 ms /   184 tokens (    1.48 ms per token,   677.05 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:        eval time =     197.38 ms /    12 tokens (   16.45 ms per token,    60.79 tokens per second)
Feb 04 08:15:14 mediaserver bash[1612383]:       total time =     469.15 ms /   196 tokens

The speeds for follow up requests seem similar.


If things are properly warmed up then hass local ai should not be re-processing 5000 tokens. For example here is my follow up request with it

prompt eval time =     104.59 ms /    99 tokens (    1.06 ms per token,   946.55 tokens per second)
       eval time =     230.37 ms /    25 tokens (    9.21 ms per token,   108.52 tokens per second)
      total time =     334.96 ms /   124 tokens
slot      release: id  2 | task 10970 | stop processing: n_tokens = 8165, truncated = 0

Each of my posted logs are the result of one single voice command, there is no “follow up” so to speak. The flow was:

  1. Fresh install of each integration
  2. Configure voice assistant to use the integration
  3. Ask “turn off the hallway and ktichen lights”
  4. Ask “turn off the hallway and ktichen lights”
  5. Ask “turn off the hallway and ktichen lights”
  6. Grab only the logs for the step 5, all previous logs are not present

So each integration was using a “warmed up” instance so to speak. Just simply saying “turn off the hallway and kitchen lights” results in two separate sets of “prompt eval time” results in the log.

You can see what I mean by looking at the timestamp for either, but this is the “extended openai conversation” logs…those two separate “prompt eval times” appear in the same second:

Those aren’t from two separate requests, that’s just me saying “turn off the hallway and kitchen lights”

There were two times before anything shown in those logs where I asked it the same thing to make sure the model was loaded and warmed up. For “extended openai conversation” the first request takes about 3.5 seconds, subsequent runs are less than 1.5 seconds. What you see in that log is the result of only the third request.

That goes for the “hass local openai” integration as well, just with much longer times.

Thanks for explaining, then that definitely seems like a caching issue in both cases. I replicated your test, here is an example

Here is the first (warm up) request for the lights and fan

prompt eval time =    1603.35 ms /  5950 tokens (    0.27 ms per token,  3710.98 tokens per second)
       eval time =     578.15 ms /    62 tokens (    9.33 ms per token,   107.24 tokens per second)
      total time =    2181.50 ms /  6012 tokens
...
prompt eval time =     103.24 ms /   155 tokens (    0.67 ms per token,  1501.39 tokens per second)
       eval time =      79.59 ms /     9 tokens (    8.84 ms per token,   113.07 tokens per second)
      total time =     182.83 ms /   164 tokens

and then there is the subsequent exact same command

prompt eval time =      51.98 ms /    22 tokens (    2.36 ms per token,   423.21 tokens per second)
       eval time =     596.17 ms /    64 tokens (    9.32 ms per token,   107.35 tokens per second)
      total time =     648.16 ms /    86 tokens
...
prompt eval time =     112.82 ms /   117 tokens (    0.96 ms per token,  1037.06 tokens per second)
       eval time =      82.55 ms /     9 tokens (    9.17 ms per token,   109.03 tokens per second)
      total time =     195.37 ms /   126 tokens

So the second request does not re-process the full prompt, which is why after warming up things are so fast all the time. Not sure if that would be a llama.cpp setup difference or something with the integrations config.

Thank you for sharing that haha.

I just went back and looked at the logs and I think the answer has been staring me in the face. There’s a key difference between my “extended OpenAI” and “hass OpenAI” logs:

The “hass OpenAI” must just require a larger context window than “extended” does and I didn’t have a large enough window set (I initiate llama-server using the “-c [context limit here]” flag since I’ve got two models running on the same card).

Now I’m going to have to retry this again later today hahaha

If you are not already I highly recommend setting your kv cache to be quantized. It considerably reduces memory usage without any noticeable loss in accuracy.

That’s why I prefer to run Qwen3-VL 30B-A3B, I can have more room for multiple context slots with large sizes.

      # Quantize Cache
      - "--cache-type-k"
      - "q8_0"
      - "--cache-type-v"
      - "q8_0"

      # Performance
      - "--flash-attn"
      - "on"

      # Support Qwen3 Template
      - "--jinja"

      # Increased batch size for prompt ingesting performance
      - "--threads"
      - "12"
      - "--batch-size"
      - "2048"
      - "--ubatch-size"
      - "1024"

      # token context shared across slots
      - "--ctx-size"
      - "72000"
      - "--parallel"
      - "4"