Chapter 5: Building a Local AI Farm
All right.
We have finally arrived at the question many people wanted to ask back in Chapter 1:
What hardware should I buy?
Now we can answer it with something better than:
“Somebody on Reddit says this GPU is good.”
The useful starting point is the workload.
A machine doing speech recognition has a different job from one serving a large reasoning model.
A box answering one conversation at a time has different requirements from one handling several voice satellites, vision requests, and background AI Tasks at once.
So before we shop, we need to size the work.
First, Do You Even Need a Farm?
Probably not.
A perfectly useful local AI environment might be:
HOME ASSISTANT
      │
      ▼
ONE AI MACHINE
      │
      ├── speech
      ├── LLM
      └── embeddings
For this chapter, I am using farm loosely to mean:
the collection of local compute resources providing AI services to your home
Your farm may have one machine.
Congratulations on your tiny farm.
Please resist buying a rack until we finish the chapter.
Start With Jobs
Write down what you actually expect the system to do.
For example:
- speech to text
- text to speech
- conversational LLM
- larger reasoning model
- vision
- embeddings
- background AI Tasks
- persistent agent workloads
Then ask:
How often does it run?
Speech may happen constantly.
A large reasoning job might run a few times per day.
How fast must it respond?
Voice is extremely sensitive to latency.
A nightly household summary can take longer.
How large is the model?
A 4B model and a 32B model have very different memory requirements.
How many jobs overlap?
One request is easy.
Two voice users, a camera analysis, and a background task at the same time create a serving problem.
How much context does it need?
A household agent may receive system instructions, tool definitions, Home Assistant state, history, retrieved information, and the user’s request.
Once you can describe the jobs, hardware becomes much easier to discuss.
A Quick Note About Wake Words
For most modern purpose-built Home Assistant voice satellites, wake-word detection does not need to become part of your central AI farm.
Supported ESPHome satellites can use microWakeWord directly on the satellite.
VOICE SATELLITE
      │
      ▼
 microWakeWord
      │
      ▼
ASSIST PIPELINE
That is generally the architecture I recommend when building your own satellites.
Home Assistant also supports openWakeWord, where detection happens centrally. If you deliberately use that architecture, include it in your service planning.
For most of this chapter we will focus on:
speech to text
conversation / LLM
text to speech
vision
embeddings
background AI work
Model Size
Language models are commonly described with numbers such as:
3B
8B
14B
32B
70B
The B generally refers to billions of parameters.
More parameters usually means more model data must be stored and processed.
It does not automatically mean a better model.
Architecture, training, specialization, and the workload matter enormously.
For hardware planning, however, one thing is unavoidable:
The model weights have to fit somewhere.
And that takes us to memory.
Memory Is Usually the First Wall
A model needs memory for its weights.
The inference engine also needs space for things such as:
- context
- KV cache
- runtime buffers
- concurrent requests
So if a model file is 20 GB, a machine with exactly 20 GB available is probably not your ideal configuration.
You need headroom.
On conventional discrete GPUs, the number people usually care about first is VRAM.
SYSTEM RAM          GPU VRAM
   64 GB              24 GB
                         │
                         ▼
                       MODEL
Keeping most or all of the active model on the GPU is generally best for performance.
If part of the model spills into system RAM, modern inference software can often still run it, but performance may drop as data crosses between CPU memory and GPU memory.
That gives us two separate questions:
Capacity
Can the model fit?
Performance
Can it run fast enough to be useful?
A server producing one token per second technically runs the model.
Your family may develop strong opinions about it as a voice assistant.
Unified Memory
Some systems use a shared memory architecture where CPU and accelerator can access a large common pool.
       UNIFIED MEMORY
        /          \
      CPU          GPU
For local AI, this is very attractive.
A conventional desktop might have:
128 GB SYSTEM RAM
       +
24 GB GPU VRAM
There is plenty of total memory, but only 24 GB is directly available as GPU memory.
Unified-memory systems can make a much larger pool available to the accelerator.
For people building a capable local Home Assistant agent, persistent harness, claw-like system, or general AI workstation, I commonly point them toward three platform families:
- Apple M-series systems with substantial unified memory
- AMD Strix Halo / Ryzen AI Max
- NVIDIA DGX Spark / GB10 systems
All three are interesting because they let you put a lot of accelerator-accessible memory in one compact machine.
Apple Silicon
Apple M-series systems combine CPU, GPU, and other accelerators around unified memory.
Higher-end configurations provide enough memory to run model classes that would require expensive discrete GPU setups elsewhere.
They also tend to have excellent power efficiency, which matters for an always-on machine.
A single box can host:
agent harness
local inference
speech services
embeddings
RAG services
background workers
without turning the utility closet into a small data center.
AMD Strix Halo / Ryzen AI Max
AMD’s Ryzen AI Max family, often referred to by the development codename Strix Halo, combines a large shared memory pool with a substantial integrated GPU.
These systems are especially interesting for people who want:
- x86
- Linux or Windows
- compact hardware
- large local model capacity
- enough general-purpose compute to run the harness and supporting services too
For agent workloads, that is a very useful shape.
NVIDIA DGX Spark / GB10
NVIDIA’s DGX Spark uses the GB10 Grace Blackwell platform and provides a large coherent memory pool alongside the NVIDIA software ecosystem.
That makes it attractive for:
- large local models
- CUDA workloads
- persistent agents
- local inference
- RAG
- MCP services
- background workers
And when I say DGX Spark, I am often talking about the broader GB10 platform class, not only NVIDIA’s branded box.
GB10 systems are available from familiar OEMs including Dell, HP, Lenovo, GIGABYTE, ASUS, Acer, MSI, and others.
The AMD side is also expanding through the normal PC and workstation ecosystem.
So these are increasingly normal workstation purchases.
You can shop based on:
- warranty
- serviceability
- cooling
- noise
- storage
- networking
- vendor support
- form factor
That is a lot nicer than buying one mysterious AI science project from one mysterious vendor.
The Catch: All That Memory Costs Money
Unified-memory systems solve a difficult local-AI problem very elegantly.
They give the accelerator access to a lot of fast memory.
And then you have to pay for it.
A lot of it.
Configurations with:
64 GB
96 GB
128 GB
or more
can become expensive very quickly.
The trade is straightforward:
MORE UNIFIED MEMORY
        │
        ├── larger models
        ├── larger context
        ├── more concurrency
        ├── more services
        │
        └── more $$$
So I do not automatically recommend buying the largest configuration available.
Buy enough for the models you expect to run, plus reasonable growth room.
If you genuinely want a large reasoning model, persistent harness, RAG, embeddings, and several supporting services on one machine, that larger pool can make excellent sense.
If your workload fits comfortably inside 16 or 24 GB, you may have much cheaper options.
Unified Memory Is Not Magic VRAM
A 128 GB unified-memory machine should not be mentally translated into:
“I have a 128 GB RTX card.”
Capacity is only one part of performance.
You still need to care about:
- memory bandwidth
- accelerator performance
- software support
- quantization
- context size
- concurrency
A machine may hold an enormous model and still run it too slowly for interactive voice.
Another machine with less memory may absolutely scream with a smaller model.
This distinction matters:
Capacity tells you what fits. Performance tells you whether you enjoy using it.
Memory Bandwidth
Memory capacity answers:
“Can I store this?”
Memory bandwidth answers:
“How quickly can I move it while using it?”
Large language model inference moves a lot of model data through memory.
Two machines may hold the same model and still perform very differently because one has much more bandwidth.
So when comparing local AI hardware, do not stop at:
“It has 128 GB.”
Ask how quickly that memory can actually feed the accelerator.
Quantization, or How We Make a Giant Model Fit
Eventually someone will tell you:
“Just run the Q4.”
This is usually where newcomers smile politely and pretend those words meant something.
So let’s fix that.
Model weights are stored as numbers.
At higher precision, the system keeps more detail in those numbers.
That uses more memory.
Quantization stores them at lower precision.
The model becomes smaller and easier to run locally.
Very roughly:
HIGH PRECISION
      │
      ▼
more numerical detail
more memory
      │
      ▼
QUANTIZATION
      │
      ▼
less numerical detail
less memory
And this is where I use the Face of Bo explanation.
You know your friend who discovered Snapchat filters?
The first filter cleans things up.
Still clearly your friend.
Add a few more and fine detail starts disappearing.
Keep going and eventually the poor human has been smoothed, compressed, enhanced, and processed until they look like the Face of Bo.
Still technically your friend.
Some nuance may have been lost.
That is a surprisingly useful mental model for quantization.
The Snapchat Filter Guide to Quantization
Think of it approximately like this:
FP16 / BF16
original photograph
lots of detail
lots of memory

        │
        ▼

Q8
light filter
still lots of detail

        │
        ▼

Q6 / Q5
more compression
often still excellent

        │
        ▼

Q4
strong compression
very common local-AI territory

        │
        ▼

Q3 / Q2
aggressive compression
Face of Bo approaches
That is an illustration, not a universal quality chart.
Different models tolerate quantization differently.
Modern quantization methods can preserve an astonishing amount of capability.
A good Q4 model may perform extremely well.
Push compression too far and you may start seeing losses in reasoning, coding, tool selection, accuracy, or nuance.
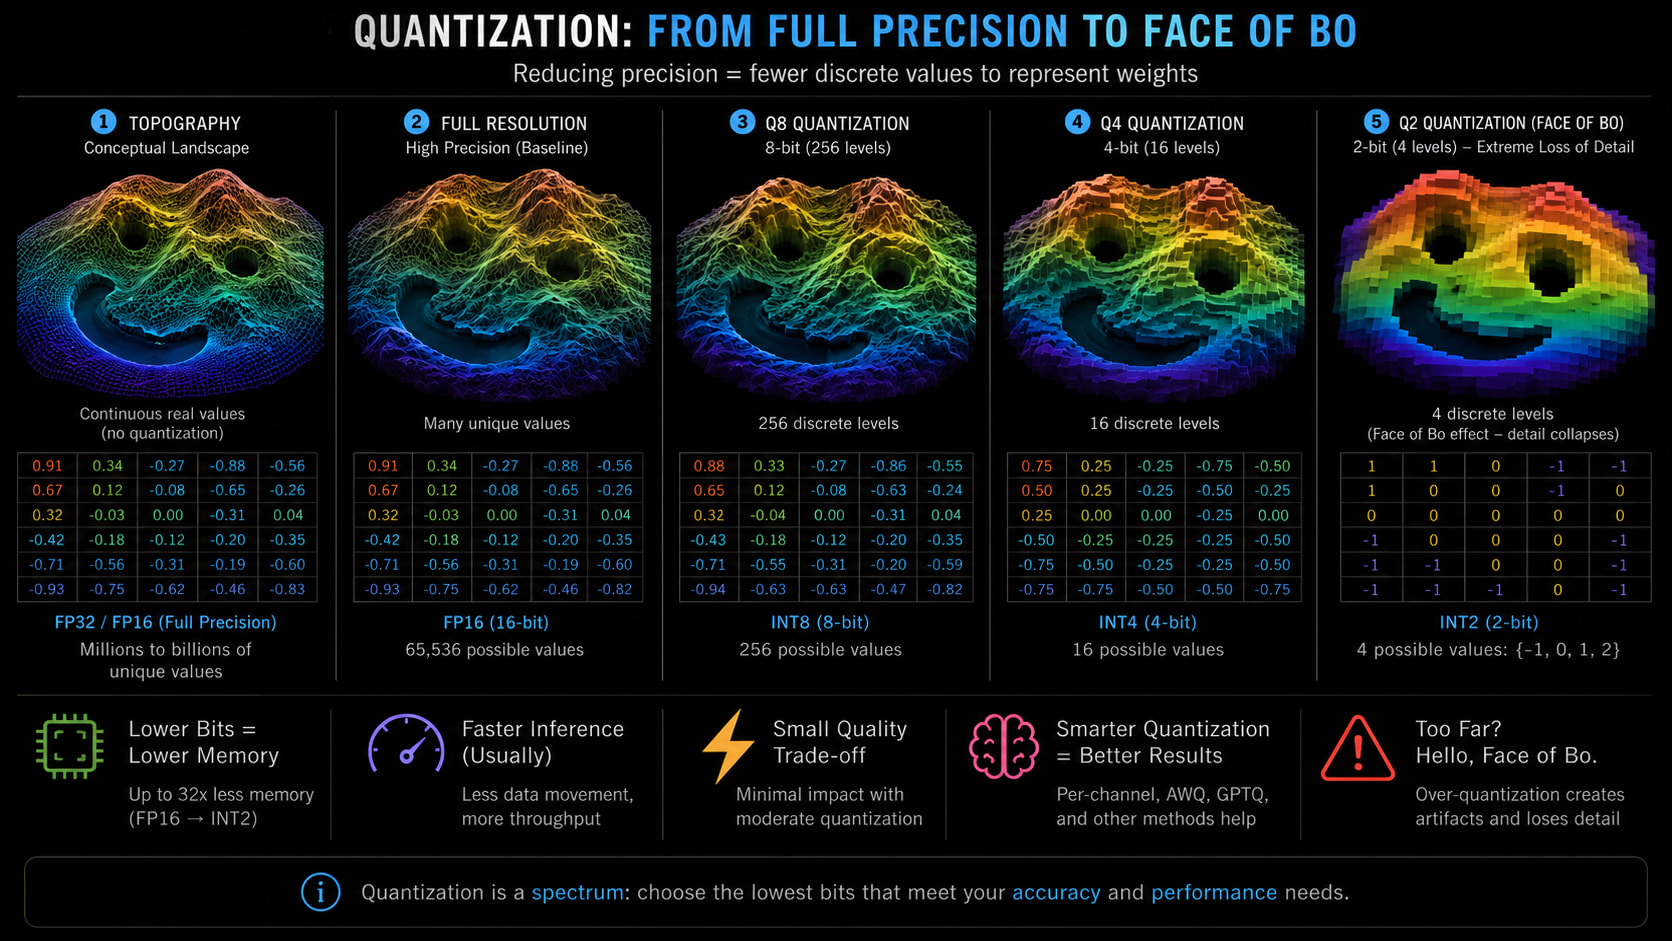
The useful idea is:
We are throwing away some numerical detail so the model becomes smaller and easier to run.
For local general-purpose LLMs, Q4-ish territory is often a very reasonable place to begin testing.
Then test the model on your workload.
For Home Assistant that means things such as:
- conversation
- tool calling
- entity understanding
- following household instructions
- multi-step reasoning
- selecting the right action
Whether the model understands:
“Turn off everything downstairs except the reading lamp.”
matters more to you than whether it won a benchmark by 0.7 percent.
Context Also Uses Memory
The model weights are only part of the requirement.
Transformer inference also keeps information associated with the active context, commonly discussed as the KV cache.
Longer context uses more memory.
Concurrent requests use more memory.
These are very different serving workloads:
8B model
4K context
1 active request
versus:
8B model
64K context
6 active requests
Same model.
Very different hardware requirement.
So model size alone is never the complete sizing answer.
What Can the GPU You Already Own Do?
Before buying an expensive unified-memory workstation, look at the GPU already sitting in your gaming PC.
RTX 30-series and 40-series cards remain very useful local-AI hardware.
Modern software makes them much more flexible than older full-precision assumptions might suggest.
Think about them by VRAM class.
| VRAM | Realistic starting point |
|---|---|
| 4 to 6 GB | Speech, embeddings, specialist models, small LLMs |
| 8 GB | 3B to 8B-class quantized conversational models |
| 10 to 12 GB | Strong 7B to 14B-class models, modest VLM work |
| 16 GB | Comfortable medium models, VLMs, stronger agents |
| 20 to 24 GB | Larger quantized models, serious agent workloads |
| 32 GB | Larger reasoning models, more context and concurrency |
| 48 GB+ | Large local models, multiple services, workstation-class use |
Treat that as a starting map, not a compatibility table.
Quantization, architecture, context, multimodal components, and inference software can move those boundaries considerably.
4 to 8 GB Is Still Useful
Small GPUs can do real work.
They are excellent candidates for:
- speech recognition
- text to speech
- embeddings
- classifiers
- smaller vision models
- small conversational LLMs
An 8 GB card can run a surprisingly capable modern 7B or 8B quantized model.
That may be all you need for routine Home Assistant conversation.
10 to 16 GB Gets Comfortable
This range opens up much more useful local-agent territory.
You can run stronger small and medium models, use more context, experiment with vision, and leave room for tool-heavy conversations.
A 12 GB or 16 GB GPU can be an excellent Home Assistant AI server.
You do not automatically need exotic hardware.
20 to 24 GB Is Serious Consumer AI Hardware
Cards such as the RTX 3090, 3090 Ti, and RTX 4090 provide 24 GB of VRAM.
That is a lot of useful local inference capacity.
It can support:
- larger quantized models
- generous context on medium models
- capable VLMs
- coding harnesses
- persistent agents
- multiple smaller services
A used 3090 remains especially interesting because 24 GB of VRAM can provide a lot of local AI capability for the money.
A 4090 offers the same headline capacity with significantly more modern performance.
For many Home Assistant installations, 24 GB is already plenty of farm.
What About 32 GB and Beyond?
Once you reach roughly 32 GB of accelerator-accessible memory, the question changes.
You gain access to larger reasoning models, larger contexts, heavier VLMs, more concurrency, and multiple simultaneously loaded services.
At 48 GB and above, you are well into workstation-class local AI territory.
At that point you may start choosing hardware based on which large model you want to run rather than whether you can run a useful agent at all.
Modern Software Makes Older Cards Better
Modern inference stacks can use techniques such as:
- 4-bit quantization
- quantized KV cache
- Flash Attention
- GPU layer offload
- CPU fallback
- optimized CUDA kernels
- multi-GPU distribution
That means an older RTX 30-series card may be much more useful today than someone evaluating it under older assumptions would expect.
Before replacing an existing GPU, test it.
You may already own enough hardware to learn a great deal.
GPU Offload and Multiple GPUs
If the model does not quite fit in VRAM, some inference engines can keep part on the GPU and part in system RAM.
MODEL
  │
  ├── GPU portion
  └── CPU / RAM portion
That expands what a machine can run, although performance usually drops as more work crosses between GPU and CPU memory.
Multiple GPUs are another option.
              MODEL
            /       \
         GPU 1     GPU 2
Modern inference software can distribute models across several cards.
That can make configurations such as:
2 × 12 GB
2 × 16 GB
2 × 24 GB
very useful.
There are costs.
You now care more about:
- PCIe lanes
- inter-GPU traffic
- motherboard layout
- power
- cooling
- software configuration
A pair of used 3090s can provide an enormous amount of model capacity.
It can also give your power supply a new hobby.
Prompt Processing Matters
AI benchmarks often emphasize:
tokens per second
Useful number.
Incomplete story.
Before generation begins, the model first has to process the prompt.
That prompt may include:
- system instructions
- Home Assistant state
- tool definitions
- conversation history
- retrieved knowledge
- the user’s request
The user may say:
“Is everything okay downstairs?”
The model may receive thousands of tokens.
So the interaction looks more like:
REQUEST
   │
   ▼
PROMPT PROCESSING
   │
   ▼
FIRST TOKEN OR TOOL CALL
   │
   ▼
GENERATION
For interactive home AI, useful measurements include:
- prompt processing speed
- time to first token
- time to first tool call
- total response latency
Voice makes delays painfully obvious.
Nobody wants to stand in a dark kitchen admiring your benchmark spreadsheet.
One Big Model or Several Specialists?
A farm does not need one giant model doing everything.
You might have:
                 HOME ASSISTANT
                       │
          ┌────────────┼────────────┐
          │            │            │
          ▼            ▼            ▼
      SMALL LLM      VISION       BIG LLM
       routine       images       reasoning
The small model handles common interaction.
The vision model handles images.
The large model handles harder reasoning.
Speech may run separately.
That is often a much better use of hardware than asking one enormous model to do every job in the house.
Serving the Farm
As the system grows, services may separate naturally:
                 HOME ASSISTANT
                       │
       ┌───────────────┼────────────────┐
       │               │                │
       ▼               ▼                ▼
    SPEECH          INFERENCE         VISION
     NODE              NODE             NODE
You might also have embeddings and background workers.
The important thing is the service, not the number of physical machines.
Start simple.
Separate workloads when performance, reliability, or capacity gives you a reason.
Concurrency
Imagine this happening at once:
- someone speaks to Assist
- another satellite gets a request
- a camera asks for vision analysis
- an AI Task runs
- a persistent agent is working
- embeddings are being generated
Now your problem is no longer just model size.
It is:
How many jobs can I serve without making the interactive ones miserable?
Inference servers differ substantially in how they schedule concurrent work.
A system designed for one user may need very little headroom.
A household with many satellites and background agents may need much more.
Latency and Throughput
Two useful terms:
Latency
How long does one request take?
Throughput
How much total work can the system process over time?
Voice strongly favors low latency.
Background indexing can favor throughput.
The best machine for one is not always the best machine for the other.
This is one reason farms often evolve into several specialized services.
Keep the House Boring
Your AI server may:
- reboot
- crash
- run out of memory
- hang during a model load
- lose a driver argument
- disappear during an upgrade
Home Assistant should remain boring.
That is praise.
Lights, leak protection, alarms, and ordinary automations should continue working while the AI server is lying on the floor contemplating its life choices.
Critical deterministic home functions should not depend on experimental inference infrastructure remaining healthy.
Do Not Forget the Boring Hardware Stuff
AI discussions obsess over GPUs.
Your machine still needs:
- CPU
- storage
- networking
- cooling
- power
- ventilation
Models can consume tens or hundreds of gigabytes of disk.
Large GPUs consume serious power.
Power becomes heat.
Heat becomes cooling.
Cooling becomes:
“Why does the closet sound like an aircraft carrier?”
If the machine stays on all day, idle efficiency matters too.
This thing lives in your house.
Eventually somebody pays its electric bill.
A Sensible First Architecture
For many Home Assistant users, this is plenty:
                 HOME ASSISTANT
                       │
                       │ LAN
                       ▼
                AI WORKSTATION
                       │
          ┌────────────┼────────────┐
          │            │            │
          ▼            ▼            ▼
        LLM          SPEECH      EMBEDDINGS
One decent machine.
Enough memory for the models you actually intend to run.
Room to experiment.
Done.
If the goal includes a persistent claw-like harness, the unified-memory platforms discussed earlier become particularly attractive because they can host the harness and a substantial model stack on one compact system.
A More Developed Farm
Later, you might arrive here:
                      HOME ASSISTANT
                            │
                            ▼
                         ROUTER
                            │
         ┌──────────────────┼──────────────────┐
         │                  │                  │
         ▼                  ▼                  ▼
     SPEECH NODE        FAST LLM NODE      HEAVY NODE
      STT / TTS           routine AI       big LLM / VLM
Different hardware handles different workloads.
A router decides where jobs go.
We will deal with that in Chapter 6.
Before You Buy Hardware
Write down five things.
1. Models
What do you actually want to run?
2. Memory
How much memory do those models need at your intended quantization and context?
3. Performance
How fast does each workload need to respond?
4. Concurrency
How many requests could overlap?
5. Growth
Are you experimenting, or building infrastructure you expect to expand?
Those five answers will usually tell you far more than the model number printed on the GPU box.
The Hardware Question Has Become Better
Back in Chapter 1, the question was:
“What hardware do I need for AI?”
Now we can say:
“I need a local conversational model with this approximate memory requirement, this context size, this latency target, and two simultaneous users.”
Excellent.
That is an answerable infrastructure question.
Or:
“I need a large local reasoning model for background agent work. Latency matters less than memory.”
Also answerable.
Or:
“I want fast local speech and conversation, with difficult reasoning sent to a larger model elsewhere.”
Now we are designing a system.
That is much more useful than shopping by GPU vibes.
The Farm Does Not Choose the Model
Imagine your home now has:
- local speech
- a fast local LLM
- a large reasoning model
- a vision model
- a cloud model
Wonderful.
A request arrives:
“What is happening outside?”
Who gets it?
Then:
“Turn off the office light.”
Which model handles that?
Then:
“Analyze the last month of energy use and tell me what changed.”
Where does that go?
We have enough compute.
Now we need traffic control.
And unfortunately, I have to tell the networking people that we are about to use the word router for something completely different.
So next: