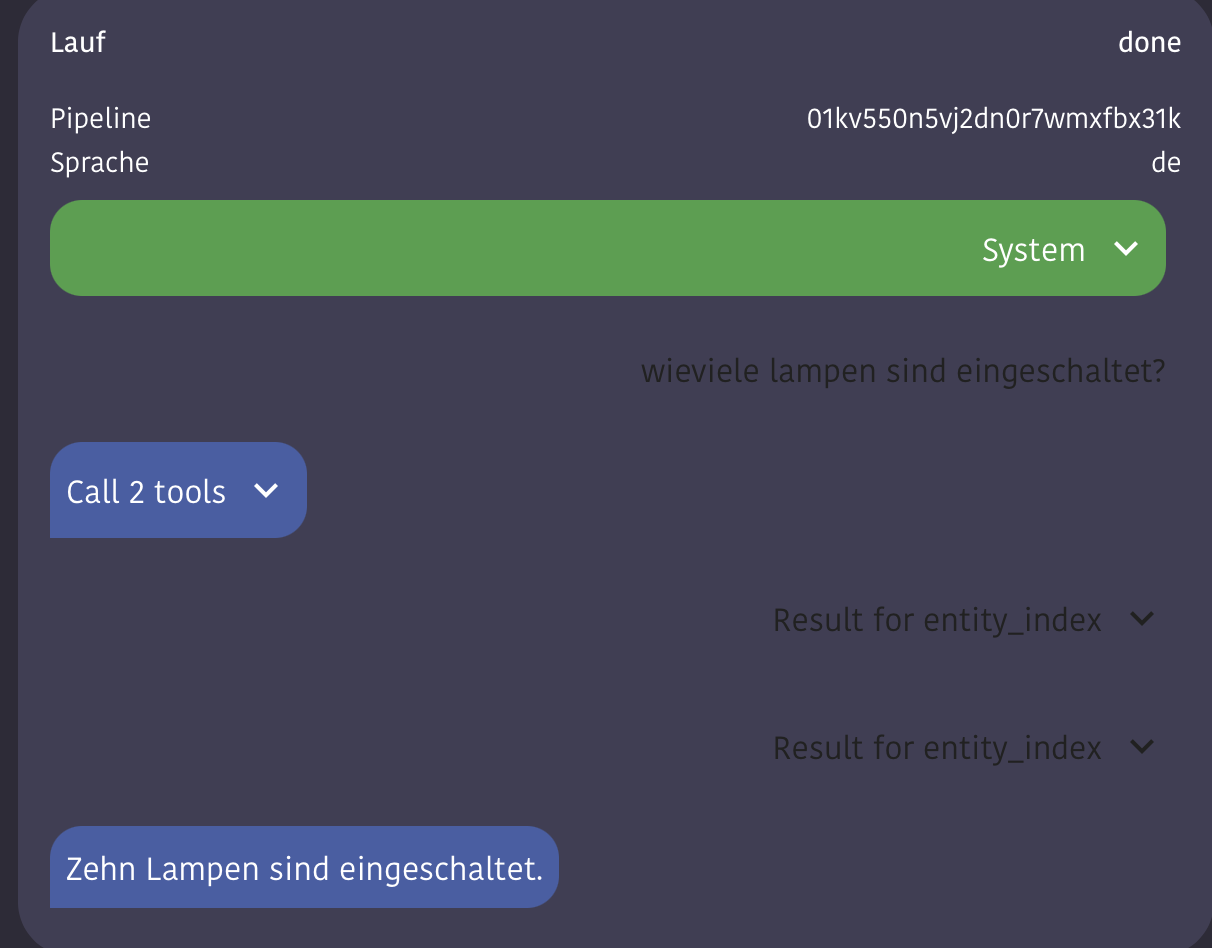
Fast (low latency) cloud models mit OpenAI compatible endpoint: Which do you use and recommend?

I wrote in another thread that I noticed HUGE differences while testing different models and providers with the OpenRouter integration.
Especially compared to the popular OpenAI models like gpt-??-mini.

My main model so far was gpt-4.1-mini, which has now been replaced with gpt-oss-120b hosted by groq (which is a cloud model hosting platform and not to be confused with Grok, the llm from xAI).

They are not the cheapest provider, but the one with the lowest latency that was shown on OpenRouter.
Their gpt-oss-120b pricing is still less than half of the price compared to gpt-4.1-mini from OpenAI.

Sadly OpenRouter (or the HA integration?) seem to have a lot problems.
Regardless of the model or provider I often get API errors or bad response errors in the conversation.
It looks like this isn’t just me, there are a lot other reports here in the forums and on Github.

So I found two integrations that can be used:

How fast is it?

First, I tried a simple question where the answer was in the training data and the models didn’t need to use tool calls: What’s the height of the eiffel tower?

  • gpt-4.1-mini fells snappy here with about 2 seconds reaction time.
  • gpt-oss-120b on groq took below 0.5 seconds in comparison.

That’s not the real reason to switch, right?

But let’s take a look at question with tool calls.
The next try was What outdoor temperature will be tomorrow betwee 8am and 9am?, which will use the Weather LLM script provided by TheFes.

  • gpt-4.1-mini needed 7 seconds to get the answer, and didn’t feel snappy at all anymore.
  • gpt-oss-120b on groq took less than 2 seconds in comparison

Fun part: gpt-oss-120 even used one tool call more compared to gpt-4.1-mini to ensure which date is tomorrow and was still way faster.

And a least, more complex example:
How much solar energy did we export this september compared to last september. Just give me the kwh for both months and calculate the difference. Also tell me the mean outdoor temperature for the garden thermometer for both months.

At least both models were successful and replied with the same, correct values.

  • gtp-4.1-mini took about 35 seconds to complete
  • gtp-oss-120b needed only about 7.5 seconds in comparison

A few words about the hass_local_openai_llm integration linked above:
It seems to be updated with the latest HA development.
You can create seperate entries for assistants or ai tasks.
It also allows to modify the promt and supports STT and TTS streaming.

Feel free to share your own experience in this thread. :slightly_smiling_face:

Thanks for the tip. I managed to install it and it seems to work. So far it indeed feels quite a bit faster than the openai integration. How does the streaming TTS work? Does that only work if you use local TTS? Or can it stream to Google cloud TTS also? I can’t seem to find any docs on how to enable it?

As I use Nabu Casa cloud TTS (which has support for streaming since quite some time), I never investigated which other TTS integrations support it.

It’s explained in the dev docs, and most likely many integrations got updated to support it.

You might have to take a look at the docs of whatever you use if it’s mentioned there.

This is always streaming emulation, as TTS models must receive sufficient data to correctly generate speech. Splitting is primarily done by specific punctuation marks. Most wyoming servers and TTS integrations handle this internally (including Casa Cloud TTS, which uses Azure).
Some cloud services handle this on their end; you just need to send them a stream of text.

Google Cloud is the latter case; StreamingSynthesize can be implemented via RPC. They handle all text segmentation and normalization. But to implement this, someone needs to be willing to take on the challenge.

As for the TTS option in Gemini integration, it’s not particularly suitable for regular use (especially if you modify it into a streaming version), as the generation speed isn’t the fastest, and the request limits at standard levels are quite low.

Got it thanks! I’ll keep playing with it. I doubt though that the TTS streaming is the overall biggest latency contributor :slight_smile:

If you look at the debug view of your LLM you can see how long SST, LLM an TTS took.

Normally the LLM part is by far the largest (‘thinking’, calling tools, maybe repeat this a few times to think about the response and call more tools, generating the final response). So yes.
This is why choosing a fast hoster/model here brings the largest benefit.

TTS streaming is only noticeable if you ask the LLM something that produces a long response. In this case it can be quite noticeable. (E.g summary of today’s news.) But for the most Smart Home replies it’s not that important.

Streaming will affect all responses longer than 60 characters. Therefore, using a TTS with streaming support is highly recommended.

And when assessing the latency of the NLU stage, it is important to take into account that sound synthesis and playback can be performed at this stage.This is especially true if there are multi-turn instrument calls. Long answers (when token and sound generation occur almost in parallel) have already been mentioned.

Original post speed comparison is really neat. Had anyone done something similar with more models?

I did (non-scientifically) test a few models.

Conversation Agent:

STT:

STT:

  • Again, started out with OpenAI, which is absolutely okay.
    In order to tune response speeds, I tested :
  • Google - awefully slow and is also speaking way too slow
  • Elevenlabs - extremely fast, free tier, adjustable speaking speed, got problems with pronunciation of dates and numbers as numerics (at least in German)

For small requests (e.g. turn off a light), the local execution kicks in and I’m to about 1 second for the whole pipeline. LLM Requests start from 2s, while more complex requests with tool calls take 4-7 seconds. Waiting for the LLM (reasoning, tool calls, back and forth) burns most of the time.

Imho Mercury 2 is fastest and best LLM for general use.

Thanks for this comment.

Mercury 2 feels indeed as fast GPT-OSS-120b through groq to me.

Simple test questions like "How many lights are currently turned on" are handled in about a second most of the time (in assist chat mode, voice might add a little additional delay).

(I use it through the [Local OpenAI LLM integration](GitHub - skye-harris/hass_local_openai_llm: Home Assistant LLM integration for local OpenAI-compatible services (llamacpp, vllm, etc) · GitHub with OpenRouters OpenAI compatible endpoint.)

And in first tests it feels smarter when asking complex questions.
Therefore it's also faster in this cases (because it uses less tool calls to solve the problem) and fails less often.

Seems to handle some things differently, so I will try to adopt my prompt in some points to see if this improves the results even further.
But I guess this could become my new default model. :slightly_smiling_face:

@kiwipaulrob do you also see the model calling every tool twice in the assist debug view?

It happens for every tool that the LLM calls for me.
Crazy that it's still so fast. :face_with_tongue:

One more comment about it:

Its architecture with parallel reasoning makes it fast, but reliability and tool calling are IMO not perfect for smart home usage.
It often shows a habit to ignore rules, and if this is the case it will fight hard to ignore your prompts. :face_with_tongue:

Sometimes it also seems less smart in combining tool calls, which also might be due to "ignoring" things you told it.

It definitely shows its strengths in more eloquent summaries and replies.
At least after a few days of playing around with it and trying to adjust my prompts, I decided to move back to gtp-oss-120b.

It's comparable in speed / latency and more reliable.
(And it's also cheaper.)

One more thing I noticed:

Nabu Casa TTS has a lot less latency for me compared to OpenAI with the core integration (which also supports streaming I guess),

So the LLM might not be the only important part here.
But there are other integrations that also feels as fast as NabuCase like e.g. ElevenLabs.

Some updates from my side:

  1. gpt-oss-120b starts to leak reasoning text and tends to repeat itself a lot if you try to give it more specfic rules about how to reply (tried to unify number / unit responses, as many TTS services have problems with these, at least in other languages than English)

    This gave me more and more problems, and I wasn’t able to fix it completely with prompting.

  2. So I tested the Mercury 2 model discussed above again, and other model / provider combinations with a very low latency and hight tokens-per-seconds values.

    a) Mercury 2 doubled tool calls can be fixed by using the latest version of the Local-OpenAI-LLM integration created by @skittle:
    fix: prevent duplicate tool calls from double finish chunks · skye-harris/hass_local_openai_llm@4729ecb · GitHub
    With a little bit more detailed help about the tools and some special cases in the prompt, this model is also working very fine for me now.

    And it’s also very fast regarding time-to-first-token (latency).

    b) Also very fast and way smarter (but more expensive) is MiniMax 2.7, which I haven’t had on my list so far.
    You have to use a whitelist on OpenRouter to only use the fast providers (or directly use a single provider through their own API endpoint) like Fireworks or Groq.
    It’s priced similarly to OpenAIs mini models, so more on the expensive side compared to some other models I used on OpenRouter.

    But it’s responses are very natural and on the point, with very good understanding of complex questions and tool calls.

    If you don’t have kids that talk the whole day to the LLM (mostly music requests), this might be the perfect choice for a cloud based assistant models and still very affordable.

    c) I also tested Gemma4 26B-A4B, as @crzynik seems to be very happy with it as a locally running model. And it’s also very capable and not expensive. The only downside when running hosted: It’s quite slow from token-per-seconds and also has a relative high latency even on the fastest providers that are available for this model on OpenRouter.
    But that might change at a later time …

  3. As already said, not only the LLM latency / speed is very important for a snappy experience, but also the TTS service.

    I’ve made a video to compare my current setup, with what might be very standard for users that don’t have Nabu Casa cloud (which has a very fast TTS service included):

    OpenAI gpt-4.1-mini combined with OpenAI TTS vs. MiniMax 2.7 with Elevenlabs Flash TTS.

    The Flash TTS version has way less latency compared to their bigger TTS model but still sounds great.
    Only downside compared to the bigger one, is that you can’t use the emotion tags inside the text to make the model laugh, cry, scream or pronounce the text in whatever way you want.
    (Which is huge fun and might be worth an extra demo at a later time.)

    You can see how much the TTS latency adds to the complete response time from the Voice PE LED pattern (when it starts to rotate again, the text response is finished and the TTS process starts).

    While the audio starts almost immediately with Elevenlabs Flash, OpenAI gives you an extra second until the response starts to play.

MiniMax 2.7 / Elevenlabs Flash TTS:

gpt-4.1-mini / OpenAI TTS:

This is indication you’re blowing the context window.

Hi Nathan,

will check if I finally got to a problematic size. :face_with_tongue:
If I remember correctly, the context size was visible at least on groqs developer console.

But I’m not sure if this is really the case here with gpt-oss-120b.
I started to use home control from Skye Harris’ Tools for Assist latey, to remove unused HA tools, the whole static context (so the LLM needs to get the correct entities by the index tool based on the labels instead of “everything” at once) and other parts of the system prompt instead of fighting against it in my personal prompt.

So currently my context size at the beginning of a new conversation should be smaller than ever.

It’s also responding fine as along as I ask questions that need long and different answers.
But if my questions are short, and the answers also short and similar, it starts to freak out with tight response rules.

Example:

I told it to write out numbers, separators like comma and units instead of e.g. 26,3°C for more reliable text to speech.

Then 3 questions are enough for problems to appear:

“How’s the temperature in the garden” → correct answer
“In the living room?” → doubled answer like “Living room: twentyfive degree celcius. Living room: twentyfive degree celcius”
“kitchen?” → "The user asked about … .

Once it’s confused like that, most follow-up answers are also affected.

I also found some other reports about that on the web, so might really be a model-specific problem.

edit:
Found it in the dashboard on groq.com:
My current token size of the prompt + a simple question resulted in 17k tokens.
So I should be far away from the 131k that gpt-oss-120b allows in this version.

Sounds like tool call > blammo.

Check what came back in your tools.

What’s blammo? :face_with_tongue:

It calls the entity search tool quite normal, and as there’s only one exposed temperature sensor per room, it also doesn’t get doubled values.
Also the tool doesn’t provide it in a way that suggests to repeat itself I guess …

Here’s the response from the first tool call, the other two look exactly the same (also only one entity returned for the other label combinations TemperatureSensor + room name).

tool_name: llmtool_entity_index
tool_result:
  success: true
  result:
    success: true
    answer: Found 1 matching entities.
    data:
      entities:
        - entity_id: sensor.multisensor_buro_temperature
          friendly_name: Temperatur Büro
          state: "26.7"
          matched_labels:
            - Büro
            - TemperatureSensor
          domain: sensor
          device_id: cda34342ae3f3bf0c89a68eea459148e
          unit_of_measurement: °C
          device_class: temperature
          state_class: measurement
    meta:
      tool: llmtool_entity_index
      count: 1
      total: 1
      entity_scope: filtered_by_labels
      label_names:
        - Büro
        - TemperatureSensor
      location: inside
      label_operator: AND
      state_filter: ""
      verbosity: detailed
      limit: 50

Do you spot anything suspicious here?

Look at your total kv+original context. That return looks nice, but I also don’t know how big you were before you also added this in. I got this early on if I was near the cap and fed ina ‘little’ too much. See what the size is when it starts to get wild. If that’s not it it could also be some wierd conflict instruction.

I can also test a similar call with that tool on my oss20b setup and see what it does. (traveling gimme a day)