Can someone recommend any mini-pc’s capable of running a 30B LLM? From what I’ve read a GPU is very important for functionality. I’m not that familiar with running the LLM’s locally.
-Thanks
Can someone recommend any mini-pc’s capable of running a 30B LLM? From what I’ve read a GPU is very important for functionality. I’m not that familiar with running the LLM’s locally.
-Thanks
What do you mean by 30B? I am interesting in going down the local route as well..
Define what you want to accomplish first Bernie - not the LLM you want. Else you WILL fail.
First a 30b unquantized LLM will require somewhere in the neighborhood of 32GB to load in RAM BEFORE you ever touch KV cache (yeah just the warmup). HA contexts are from 8-32K and will drive that number up linear with token count for a fixed architecture and cache format but feels logarithmic - trust me you’re already cramped and need to squish a little more in without killing perf - depending on the size. That 30b is for Dev work and what I’d load on my DGX Spark, not for HA Agent drive a house work. And whether a quantized model will work wholly depends on the job. Most models fall off the truck FAST when you highly quantize them (quantize: average out the resolution of the weights so they fit in smaller ramspace) Imagine your friend who uses too many Insta filters and now looks like the Face of Bo in all their pics.
Read: A highly quantized 30b or 27b, may perform poorer than a 4b on certain workloads. But a quantized high parameter model may be the right choice - you’re not made of money or VRAM so you’ll have to compromise.
So what do you want to be able to accomplish first, THEN lets size the agent THEN what does it run on…
As for the MiniPC make sure it supports Thunderbolt5 or OCuLink and you can add whatever GPU / NPU you want.
For LLM 30B-34B the Mac mini M4 Pro, 48GB RAM would be a good Choice.
I’ve been using OpenCode in HA. I’ve used some of the free models, and some of the more expensive models like Claude Sonett 4.5. I’ve spent about $10 in about 5 days. Not a lot but then I read for no cost you can get close to this cloud functionality with a 30B LLM. I enjoy giving Home Assistant orders! 
Thanks, noted.
Ok then you’re in a 32G vram card
OR
DGX Spark
Or the upcoming RTX Spark platform
OR
Strix Halo
OR
Apple M4-M5
ALL of these share fast system RAM with the GPU on a sliding window and let yih get the larger model. But for the size you’re talking, 32G (prefer more) JUST for the model then add whatever you need for your software to run like they said before 48… But that’s your starting point.
It’s 30 billion operations I believe. Here’s a breakdown I found:
30 billion PARAMETERS are included in the weights on the Neural Net.
Most of the Open dev models like QWEN3.5/3.6/3.6, Gemma4 dev variants GPTOSS20b. Are this size.
Kimis newest Fable killer is out of reach unless you are daisy chaining DGX boxes.
Squished for space and need to get inside 16G. Go 7b size
If you need Agentic tool use go even smaller for something like Google E4B Gemma (effectively 4B parameters, not kidding) you can get amazing perf in small memorybsoace for large context (what I do for Friday)
Ever wonder why all those Apple M4 macs flew off the shelves last year? Openclaw..
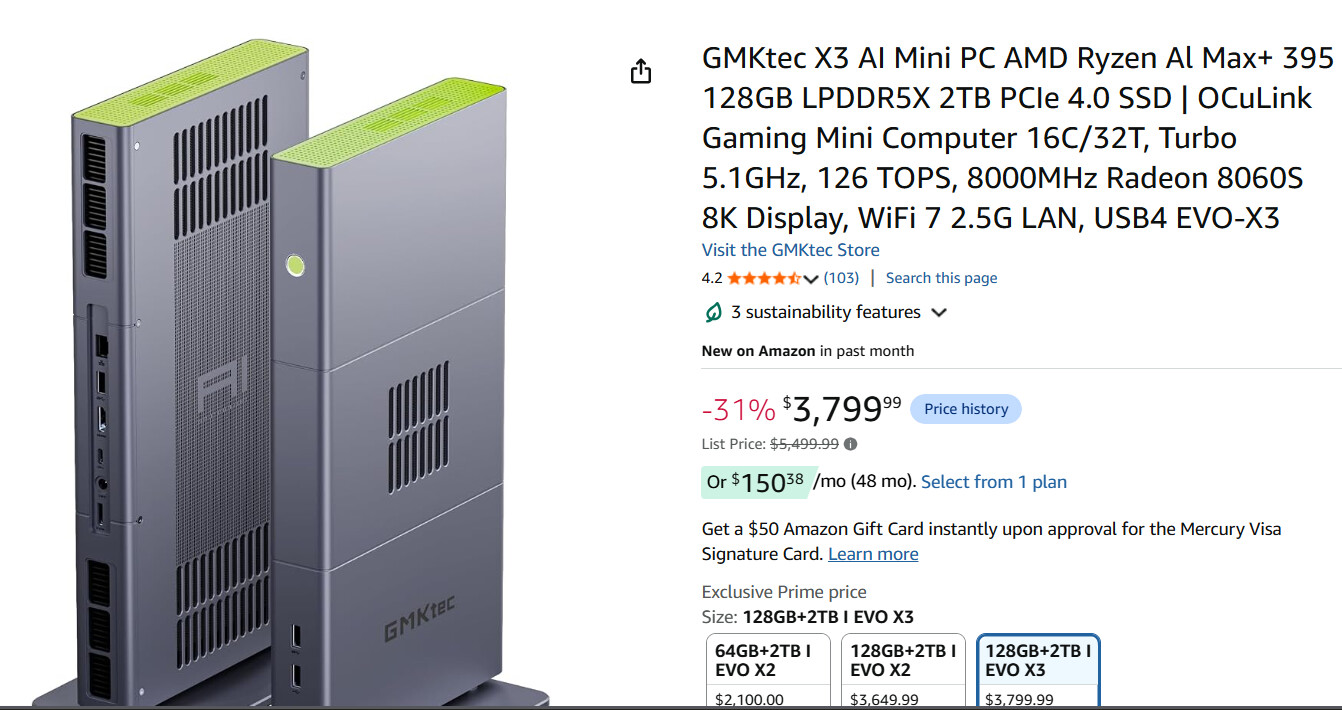
Thanks I’m trying to get over the sticker shock. Those units range from $4k to $7k from the few that I saw. I was hoping to get into 30B hardware for about $2k. I’m debating if it would be cost effective, assuming cloud AI would probably run me maybe $100 to $200 per year, after the novelty wears off.
To be frank.
Not happening with any reasonable assurance that you’ll be happy with it. You can’t even get a 16G RTX for that right now.
That said. You can be reasonably assured with any partner you may have that the prices for these ARE NOT going down anytime soon. (measured in years at this point at least past '27) In fact that DGX spark cost 4K retail last year when I bought it. Prices are INCREASING on ram laden local gear.
Also model capabilities are VASTLY improved. This time last year a Qwen3.5 struggled through simple HA scripts with good grounding and coaching. Today most of the 7B models have little trouble with adequate coaching… That’s not stopping.
I have a 3+ year plan on my DGX now and probably 5 if it keeps up.
So if you pull the trigger on gear. It’s the cheapest you can expect to pay for increasing capabilities for at least three years. Very few tech products claim that mantle.
I would like a new toy.  And my wife would get over it eventually!
 Thanks for the info, I’m thinking about it…
Dell loaned me their version of a DGX for a show. It’s sitting right next to the other one hoping they dont want it back…
My wife asked me if they would (realistically about 1/3 of the stuff i get ends up gaining a home)
Me: Uh this thing is worth 3x its weight in solid silver right now. They’ll ask. THat reminds me it’s been two weeks. I PROBABLY should remind them..
(It’s also a great toy, I’m all in on any of those local platforms - it aint getting cheaper and token economy is a real thing.)
Have you considered the energy costs? The DGX Spark requires a 240W external power supply. Assuming 120W actual consumption = ~1,000kWh/yr. If you live in San Diego, that’s ~$750/yr! (Seattle ~$200/yr, EU €290/yr)
NOT an issue at all. It idles at 15w and sips juice. Its VERY efficient. San Antonio pays approx 7c/kWh… I have the breakdown I did on inference cost in Friday’s Party if you’re interested - wround post 610-620 I think.
Modern machines dont run flat out all the time - gone is the day of the 800w PS drinking power all the time.
I assume you mean 15Watts
Yep I was in mid edit. It also draws lower but 15 is a good idle assumption. WAY better than any other server / workstation class hardware I’ve ever used.
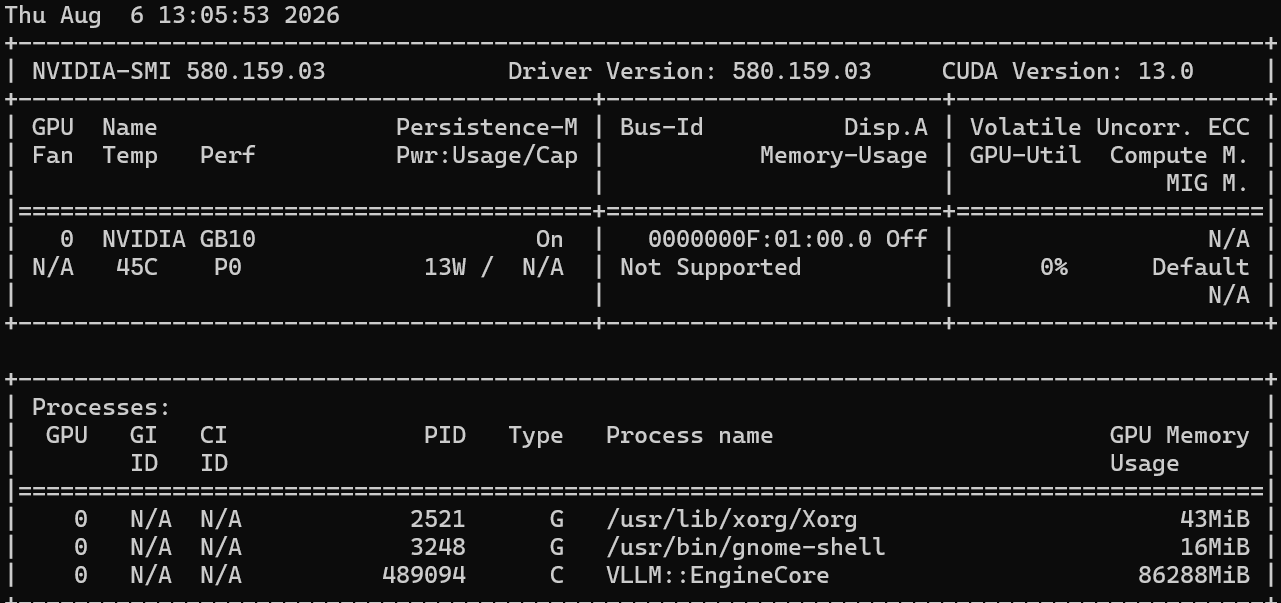
and I just grabbed a snap:
That box is runninng my always on summary pipe right now and can be tapped for opencode, claw, Hermes, other variants of agent.
Also note - thats nvidia/Gemma-4-26B-A4B-NVFP4 loaded currently, it’s my Hermes-Opencode capable but not too much for HA model.
Short version I’m pushing 6-7M tokens a DAY through that now. there is no commercial service on EARTH that can touch my token price v power cost.
Thanks for pointing that out! When I first began researching running a local LLM I was looking at high-end mini-pc’s and the energy cost was minimal. But now that you’ve put it that way, I’m thinking even harder. I currently have a kicked up HA Yellow with CM5, 8GB of RAM, and 500 GB SSD drive. It only uses 5W! I’m reluctant to get rid of it because it rarely breaks 20% in CPU and memory usage.
That’s certainly good to know. It would be idling at 15W most of the time.
If I get the following AI PC and install Ollama, and a 30B LLM, would I be able to point OpenCode running on my Home Assistant Yellow to it and do things like:
-List all automations that have references to living room lamps.
-Create an automation that turn on the porch light at sunset.
-Is my automation “Dryer Finished” optimal?
-Recommend improvements to the “Washer Finished” automation.
I’ve read some accounts that say “no” because Ollama doesn’t have access to your automations.yaml and other config files. I’ve read another account which seems to suggest if you are using OpenCode it passes Ollama the data it needs to function.
-Thanks