Sonoff ZBMINIL2's drop off after successful STANDARD_SECURITY_SECURED_REJOIN

Greetings!

My first post here.

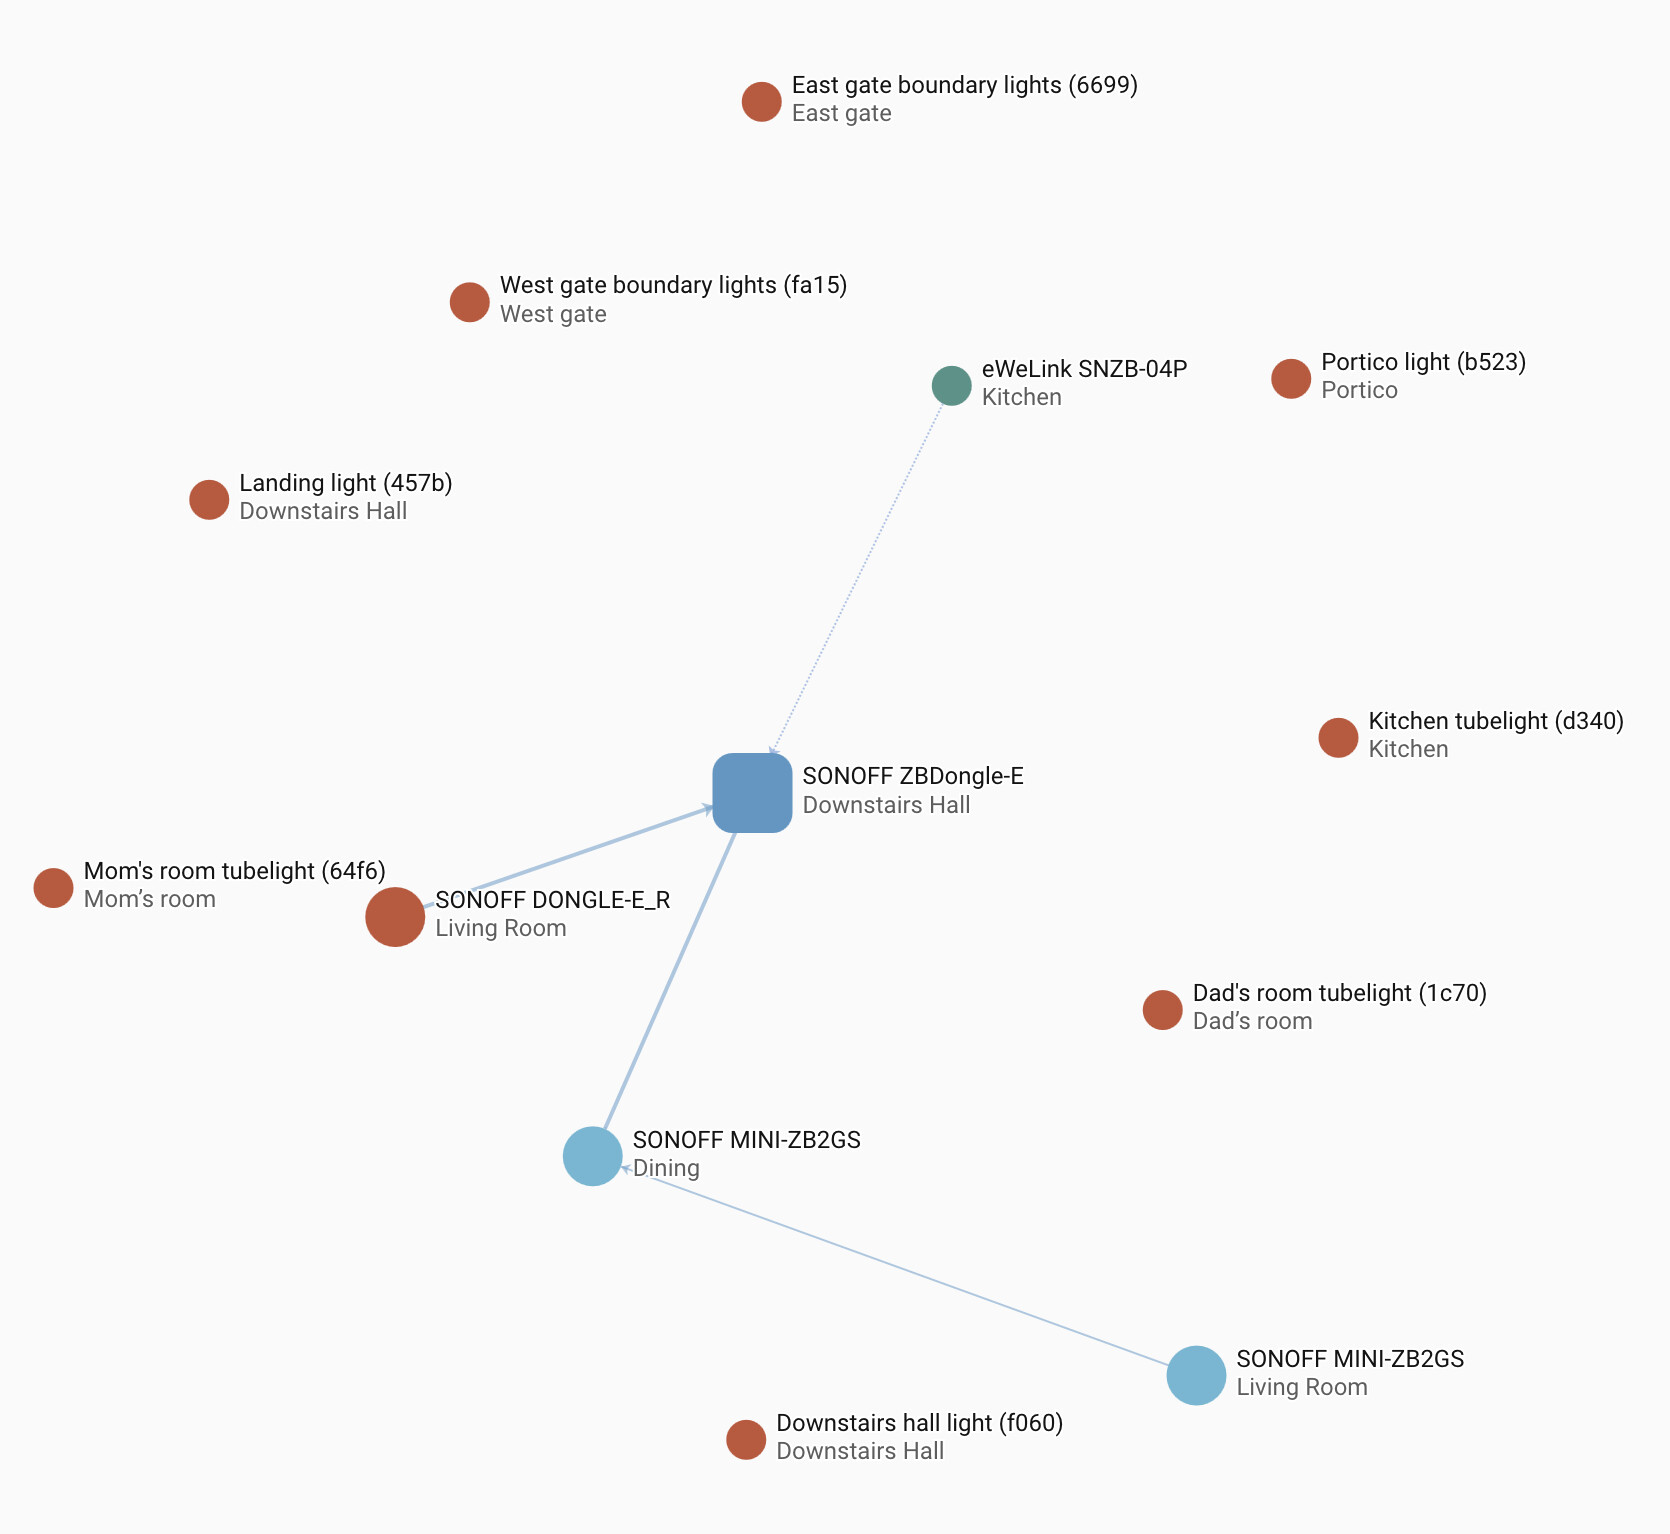
I have a simple network of mostly Sonoff ZBMINIL2s and a couple of routers (screenshot below). I recently had to re-create it and since then all of my 8 ZBMINIL2’s keep dropping off 10 - 20 minutes after I turn them off. In the debug logs, this is the consistent pattern for these devices

2026-08-12 07:26:21.575 DEBUG (MainThread) [bellows.ezsp.protocol] Received command trustCenterJoinHandler: {'newNodeId': 0xB523, 'newNodeEui64': c0:9b:9e:ff:fe:47:96:51, 'status': <EmberDeviceUpdate.STANDARD_SECURITY_UNSECURED_REJOIN: 3>, 'policyDecision': <EmberJoinDecision.DENY_JOIN: 2>, 'parentOfNewNodeId': 0xA3ED}
...

2026-08-12 07:26:23.671 DEBUG (MainThread) [bellows.ezsp.protocol] Received command trustCenterJoinHandler: {'newNodeId': 0xB523, 'newNodeEui64': c0:9b:9e:ff:fe:47:96:51, 'status': <EmberDeviceUpdate.STANDARD_SECURITY_SECURED_REJOIN: 0>, 'policyDecision': <EmberJoinDecision.NO_ACTION: 3>, 'parentOfNewNodeId': 0x0000}
...

2026-08-12 07:26:23.902 DEBUG (MainThread) [bellows.ezsp.protocol] Received command childJoinHandler: {'index': 1, 'joining': <Bool.false: 0>, 'childId': 0xB523, 'childEui64': c0:9b:9e:ff:fe:47:96:51, 'childType': <EmberNodeType.SLEEPY_END_DEVICE: 4>}
...

2026-08-12 07:26:23.955 DEBUG (MainThread) [bellows.ezsp.protocol] Received command trustCenterJoinHandler: {'newNodeId': 0xB523, 'newNodeEui64': c0:9b:9e:ff:fe:47:96:51, 'status': <EmberDeviceUpdate.DEVICE_LEFT: 2>, 'policyDecision': <EmberJoinDecision.NO_ACTION: 3>, 'parentOfNewNodeId': 0xFFFF}

I can link the full logs but I’m not sure if I should do that from security perspective. Please let me know if I should.

As per Claude, the ZBMINI2 is an EndDevice. To save power, it goes into a sleep mode. When it wakes up it somehow loses track of the network key, so it tries an UNSECURE_REJOIN via a router. It’s only explanation for the device leaving the network is a wrong network key due to a restored backup config, which I didn’t do.

I have a lot of questions but the main ones are

a> Is allowing UNSECURE_JOIN like this post says, my only option to fix it?

b> How to make use of the fact that these devices were solid in the old network and consistently drop off in the new one, to debug further?

Some more context:

  1. These same devices were working perfectly for months on a Raspbeerry PI 4 based setup, which died. Couldn’t restore the backup since I didn’t know it was encrypted. So I set up everything again on an Intel NUC (direct install, not VM).
  2. I initially reset all the ZBMINIL2s by pressing the reset buttons on them, and later, by toggling the external switch rapidly, many times, for experimenting.
  3. I have taken care of usual network interference issues, like using a USB extension cable to connect the adapter putting it on a higher level, turning of 2.4GHz wifi, etc. Tried adding the ZBMINIL2s via a router (Sonoff MINI-ZB2GS), etc.
  4. The device I quoted above is ~10 feet from the coordinator’s antenna, with clear line of sight. In fact, one of the devices is 2 feet away from the coordinator with no difference in behavior.
  5. The routers haven’t dropped off even once in the new network. Neither has a battery powered door opening sensor which is quite far away.

Devices in network

  1. SONOFF ZBDongle-E (coordinator) on Intel NUC (HAOS, no VM) with USB ext cable
  2. Sonoff MINI-ZB2GS (x2) - no clear line of sight, but 100% stable
  3. SONOFF ZBDongle-E flashed with router firmware (100% stable)
  4. Sonoff ZBMINIL2 (x8) - all offline
  5. Sonoff eWeLink SNZB-04P door sensor (100% stable)

All device firmware are up-to-date.

Home Assistant versions
Core: 2026.8.1
Supervisor: 2026.07.5
OS: 18.2
Frontend: 20260729.6
I have the same problem—almost identical to yours—with three Sonoff ZBMINI-L2 devices. They worked fine for months until a power outage occurred. After that, they disconnected. I’ve tried reconnecting them several times, but they drop the connection after a few minutes.

Same issue here — 6x ZBMINIL2, exact same symptom pattern. These devices worked flawlessly for almost a year before this started, right around 2026.8.1 (Aug 11).

A few additional data points that might help narrow it down:

  • Signal strength isn’t the cause: I have devices with excellent LQI (190+, direct coordinator child, ~6m line of sight) failing identically to ones with poor signal (LQI 50-70). Ruled this out definitively.

  • None of the affected ZBMINIL2s ever send periodic route record requests (visible via debug log zigpy.topology), unlike every other device on my mesh (35 devices total, routers included) which do so constantly. This means the coordinator has to FORCE_ROUTE_DISCOVERY on literally every single command — visible as repeated retry escalation (NONE → ENABLE_ROUTE_DISCOVERY → FORCE_ROUTE_DISCOVERY) in debug logs.

  • zha.application.gateway logs show a recurring “Cancelling previous initialization task for device ” warning — devices get stuck re-running full init (started initialization → completed initialization) every ~8-15 seconds instead of settling into steady polling.

  • ezsp_counters on my coordinator show NWK_FRAME_COUNTER_FAILURE: 23723 — suspiciously high, consistent with devices doing unsecured rejoins repeatedly and desyncing their frame counter with the coordinator.

  • Rolled back to 2026.8.0 — didn’t fix it (devices were already in a bad state and rollback alone doesn’t reset that). Updated to 2026.8.2 — no change.

Hi there, somehow I am happy to see others having the same issue, ruling out it is me.
The devices worked great with my conbee II setup with deconz, but I recently changed to ZHA with a zbt-2 and the issue started.

Things I tried are:

  1. Change the channel of the coordinator, nothing changed
  2. Remove the devices from the coordinator and resetting the devices and reconnect, nothing changed.
  3. Removing the devices and add them via a router nearby, nothing changed.
  4. Switched from usb3 to usb2 as port for the coordinator, nothing changed.
  5. Repositioned the coordinator, nothing changed.

All other devices in my zigbee network are totally stable and running well. However my 2 sonoff zbmini l2 devices keep giving me headaches.
I feel it is in the latest firmware that has been deployed to the devices, but I don’t know how to rollback the firmware to verify if that was the cause.
I trusted zha when it advised me to do a firmware update to the devices.

I hope someone understands the true cause and can find a fix and share it here.

Yes, all the other Zigbee devices in the network are working without any problems. The firmware on all ZBMINIL2 devices is 0x0000100e, but as far as I remember it’s from 2024, and I haven’t updated the ZBMINIL2s at all since I bought them.

I updated mine last weekend to the same firmware. That was also when the issues started. However I also switched to ZHA and a zbt-2. So it can be a variety of things that caused it.
I came from a conbee 2 stick without issues in deconz. I will try tomorrow to install the conbee 2 in paralel with zigbee2mqtt and see if that becomes stable. If not I can always run it in paralel with deconz again where it functioned fine.
I will keep you posted on my findings

Those ZBMINIL2’s have been 100% stable since I appended this to my configuration.yaml file

zha:
  zigpy_config:
    ezsp_policies:
      TRUST_CENTER_POLICY: 0x0002

There’s some kind of security issue with doing this, so I’m not suggesting that everybody having this issue should also do it, especially since it used to work without these changes earlier.

I don’t remember ever updating any firmware but they all seem to be on the latest one anyway.

Thank you for the information. They worked stable on ZHA before or another coordinator or integration?

Yes, they were absolutely stable on ZHA for many months. The coordinator (HAOS) is on different hardware but the dongle is the same. I did not reflash it.

I just tried bringing them back to deconz where they used to work fine. But there I am unable to pair them.
My expectation is that the firmware update recently broke something.
I will try it now on zigbee2mqtt and see what that does.
I will keep you posted

Unfortunately I did not get my conbee 2 working on zigbee2mqtt. So I am unable to test that.

Hi everyone! I am having the exact same issue. After a power outage, my ZBMINIL2 devices become unreachable. After reconnecting them, they work for a few minutes and then lose connection again. Has anyone managed to find a solution for this?

My system specs:
Core: 2026.8.2
Supervisor: 2026.07.5
Operating System: 18.2
Frontend: 20260729.7

I have had the same problem with a similar configuration, ZBT-2, ZBMINIL2, Core: 2026.8.2. The ZBMINIL2 is on firmware 0x0000100e. The device was being dropped every 30mins to 5 hours. I went around the loop of: changing the hardware, reviewing and adjusting the WiFi channels, moving zigbee repeaters to be nearer the device, rolling back to a previous release of HA etc. None of this worked.
I have now reinstated 2026.8.2 and implemented the config change given by sauravg above. This finally seems to have fixed the problem.The security issue would appear to be very minor - for my setup.
So I am very grateful for this thread - after more than a week I have a solution. Thank you all.

Quite some time ago I used the same fix to solve Aqara disconnects. I don’t know if it is still needed, I am not going to fix anything that is no longer broken. I’m just reporting it here for others having aqara disconnects.

@tony77 I have tried the same. Adding the setup to my configuration.yaml, removing the devices and re-pairing them, but the devices keep loosing connection even though the zbt-2 is just 2 meters away and other routers are close by as well.

Well I thought it was fixed. But after being connected for a coupler of days my zbminil2 has started dropping is connection again. So I am back looking for a solution too.
I did notice that my device would sometimes appear to be linked to a repeater at the far end of the house rather than one only 2m away, or the controller which is also much nearer.

Hi @tony77 , I see exactly the same behaviour. The devices reach out to a router very far away. And in between I have like 6 other routers.

Same symptom here, with two different units of the same model. Adding data
rather than another "me too", because I think two of these points are new to
the thread.

Setup
- 2× SONOFF ZBMINI-L2 (no-neutral), both shipped with firmware 0x0000100E (4110)
- Coordinator: SONOFF ZBDongle-E, EZSP v14 / EmberZNet 8.x, on a USB extension
- HA Core 2026.8.2, HA OS 18.2, ZHA 2.1.0, zigpy 2.1.0, bellows 1.0.0
- Channel 11, small network: 1 coordinator, 3 routers, 2 end devices
- Momentary wall switch, module set to SwitchType.Momentary
- ~20 W non-smart bulb

The failure
The device polls and reports LQI/RSSI every 45-85 s, perfectly steadily, and
then stops mid-stream. No Leave is ever sent. It does not rejoin on its own —
it needs a manual 5 s button hold — and it comes back with the same IEEE and a
NEW short address every single time (29901 -> 27500 -> 41264 here).

Point 1: it is NOT a link problem, and I can show it
Last reading before the most recent drop, 5 minutes before it went silent:
RSSI -56 dBm, LQI 176. The whole preceding 1 h 30 min sat flat between -52 and
-57 dBm. There is no degradation, no rising retry count, no LQI decay. It works
perfectly and then it is simply gone.

Coordinator counters (from /api/diagnostics/config_entry/<zha_entry_id>, no
extra integration needed):
  PHY_CCA_FAIL_COUNT        109   (out of ~150,000 transmissions)
  CHILD_REMOVED              12
  NWK_FRAME_COUNTER_FAILURE  54

CCA failures are essentially zero, so the channel is not congested. Note my
NWK_FRAME_COUNTER_FAILURE is 54, nowhere near the 23,723 reported earlier in
this thread — so I am not assuming we have exactly the same fault.

Control: a SONOFF SNZB-02D end device on the same coordinator kept reporting
throughout every single outage, including a 48.9 h one. The mesh was fine.

Point 2: the module stays alive locally while it is off the network
This is the one I have not seen mentioned here. With the module 12 hours
unavailable in ZHA, I pressed the wall switch and the light came on. The relay
switched. So the device has power and its local logic is running — only the
radio side is dead. That rules out the parasitic-supply/bulb-load theories that
usually come up for no-neutral modules, and points at the Zigbee stack itself.

If you are debugging one of these, this is a free 10-second test worth doing
before you start chasing bulb wattages like I did for two days.

Statistics for unit A over its whole life: 10 drops, 114 h unavailable out of
173 h (66%). Unit B is behaving identically so far, which is why I stopped
believing I had a defective unit.

On the TRUST_CENTER_POLICY workaround
I applied it and verified it in the bellows debug log, because ezsp_policies is
declared as {str: int} with no key-name validation, so `ha core check` will
happily accept a typo. The startup sequence is:

  setPolicy TRUST_CENTER_POLICY = 2     <- from configuration.yaml
  setPolicy TRUST_CENTER_POLICY = 3     <- overwritten by the join-permit window
  setPolicy TRUST_CENTER_POLICY = 2     <- restored

So it does stick on bellows 1.0.0, despite the transient 3 in between. Worth
checking your own log rather than trusting the config check.

One side effect nobody warned me about: 0x0002 is ALLOW_UNSECURED_REJOINS
WITHOUT ALLOW_JOINS, so with this policy active a device that needs a full join
(rather than a secured rejoin) will be refused. My module would not come back
until I explicitly opened the permit window. If you apply this, expect to need
zha.permit when re-pairing.

I will report back in a few days on whether it actually holds.

Started with the same issue when installing two new Sonoff ZBMINIL2s (my first ones). Running the latest HA version. Also had the drop-offs with log entries like

2026-08-26 23:07:10.974 DEBUG (MainThread) [bellows.zigbee.application] Received trustCenterJoinHandler frame with [0xE4C9, c0:9b:9e:ff:fe:47:bf:b4, <EmberDeviceUpdate.STANDARD_SECURITY_UNSECURED_REJOIN: 3>, <EmberJoinDecision.DENY_JOIN: 2>, 0x84CD]

2026-08-26 23:07:13.130 DEBUG (MainThread) [bellows.ezsp.protocol] Received command trustCenterJoinHandler: {‘newNodeId’: 0xE4C9, ‘newNodeEui64’: c0:9b:9e:ff:fe:47:bf:b4, ‘status’: <EmberDeviceUpdate.STANDARD_SECURITY_SECURED_REJOIN: 0>, ‘policyDecision’: <EmberJoinDecision.NO_ACTION: 3>, ‘parentOfNewNodeId’: 0x0000}

After changing the security policy (not a good/real fix as much as I read in the blog) at least the devices stopped dropping off. Working as designed for 3 days now. Also the connection to a very remote router resolved after a while and seems to be ok now.

I’m having the same problem, except I just migrated these devices to HA late last week, and they have dropped off almost immediately. I thought I was doing something wrong.

I’m assuming this will get fixed at some point. Meanwhile, what exactly are the security concerns if the above fix is used? I have a very small zigbee network, all lights, so I’m guessing it’s probably not something I need to worry about.

I’m wondering if the R2’s (with neutral) have the same problem? It seems to be related to the “sleepiness” of these no-neutral devices.