I just install Ollama on a MINISFORUM Mini PC AI X1 Pro. 48 GB of RAM is allocated for GPU usage. On the AI PC itself using the qwen3:30b model, questions are answered in seconds. But OpenCode running in Home Assistant on my HA Yellow Pi 5 & 8 GB of RAM takes 3-4 minutes to answer “What is 2 + 2?”.
I’ve tried different and smaller models, and they are all extremely slow. I’ve tried different values for “context” and “output” which did not help (See configuration below).
Any ideas what could be causing such speed degradation in OpenCode?
Thanks, but this problem is almost certainly with OpenCode. As I said on the AI PC itself Qwen3:30b answers questions including math, in seconds. In OpenCode it takes minutes to answer ANY questions math, or “Is the office lamp on?” took close to 5 minutes!
Math has absolute answers.
AI’s are guessing based on probability machines.
Ask an artist to do calculus, it often doesn’t work out.
Most AI’s can’t even count to 100..
In OpenCode it took 5 minutes to answer the question “Is the office lamp on?”. On the AI computer If I ask qwen3:30b how much is 2 + 2 it answers in about a second. In OpenCode over 2 minutes.
This speed issue isn’t due to math, the problem is with OpenCode.
Did you read my post? Forget about math. ANY question takes minutes to answer in OpenCode, and only seconds on my AI computer. OpenCode is essentially useless when using it with local LLM’s. I’ve done a lot of configuration testing to no avail, and think the slowness is most likely a bug.
“Explain the three body problem in a paragraph or less”
In Ollama on AI PC this question took 6 seconds to answer.
In OpenCode 3 minutes.
It’s not a fair comparison. The default system prompt when using opencode is included with your question. It looks like that’s around 1400 words. It’s probably slow because of the amount of tokens it has to process.
You could test by asking a question of equivalent length and see if you get the same response time as opencode
This has everything to do with opencode and model selection and available vram. Context optimization and caching and a bunch of other thkgs, and nothing at all to do with ha..
Bernie welcome to model capabilities and optimization. Some models suck at some stuff. You’re going to have to spend some time optimizing that new box to figure out what models work on it quickly. Im prob doing Gemma 4 or the new qwen38 sized for 32gb on that machine.
Also Bernie if you think this is OpenCode issue you would want to bring the issue to the developer / the app owner of OpenCode. Discussions here would be discussions… likely would not take you very far if you want to make OpenCode faster.
And yes, on the other hand, optimization is key. You will need to find the good (or balanced… there are always tradeoffs) mix of combination on the HW / SW config.
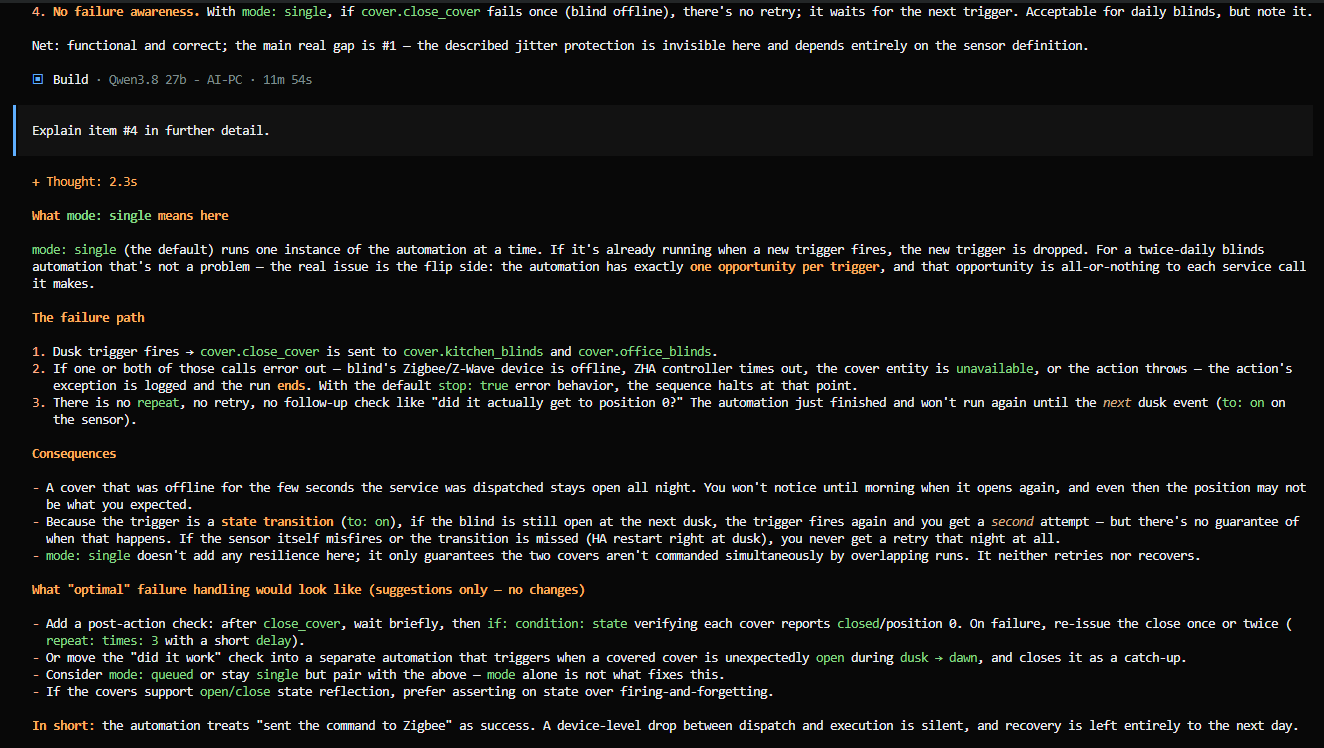
Thanks. I just installed the new qwen3.8.27b which seems a bit faster. It only takes 30 seconds to turn on a light! I also had it analyze one of my automations and it made some intelligent refactoring suggestions. See the screenshot below. Yesterday the qwen3:30b seemed a bit “lost” at times which led me to believe that they need to be trained. However I don’t think that’s the case since OpenCode is the MCP for the AI models, as I understand it.
There’s a lot of ok how is it connected and doing the thing here.
TTFT = Time to first token.
Its 100% a factor of the amount of context size in.
Context in is a factor of how your opencode agent is connected. How the prompt is constructed what tools and ctx is presented. Etc.
I can run an opencode session against my HA rig and tell it to write a script and pewf. Here you go. But if I ask that same llm through ha to connect. To the house and respond I have a 7 second lag due to context load and TTFT vs. Cache mechanics on my LLM server.
So.
Could literally be a million things I don’t have the right info to answer yet. We would need to start at first principals how are. You accessing opencode. How is it connected to HA etc etc.
2+2 on a LLM?
Search the internet and local learnt database. Find twenty million hits. Analyse everyone to look for any variations from the common answer 4. After 2 megawatts of electricity used it finds one reference to a child’s exam paper from a grade 2 exam paper that was loaded up thirty years ago to an obscure repository at an Russian school in Siberia.
It gives a definitive answer: 2.0000000007 as it had to calculate the average across all hits.
Folks: You want that engine to analyse and tell you your light is 97.8% on?
You are using the wrong tool. An LLM is only going to do text analysis efficiently, as that was what it was designed for.
If you want intelligence, artificial or not, let’s see those token$ up front please.
Note I never said that was a good use of or a good idea?
And yes it must load up all the tokens before it can answer. If what’s going on what I think is going on. His llm had to load up all its startup context THEN process it to get the answer.. If I cold start mine it an take up to 30 MINUTES (download model updates, load model, warm up tensor math, kv cache, etc.) Some models are let’s just say… Chatty and like to dump a 1000 tokens thinking about an issue before it gets to the point.
Qwen is one of those Early Mistrals too - can address with thinking options or model choices.
All that happens before it even attempts to answer… (that’s all in that TTFT above)
So asking for basic math is a horrible waste of resources unless you’re trying to find the zeros in Reimann
The math problem was just a speed test. Which OpenCode failed miserbly. On my AI PC I can ask what is 2 + 2 and it answers in seconds. In OpenCode it takes many minutes. Forget about math, ANY question I ask on my AI server regardless of model is answered in seconds, not minutes. If there are a “million” reasons why OpenCode could be so slow then it could take forever to figure out. Frankly It seems like a bug to me, there are other tickets open regarding slowness with local AI. Here’s the ticket I opened. We’ll see…
OpenCode in Home Assistant Extremely Slow Communicating with Ollama #43117
If you use Mistral “Vibe” (stupid name) on a desktop you can see it talking to itself - like three or four boffins sitting round a table. “Perhaps we should…” “Yes, but I don’t think the user wants that…” It can go on for 20 seconds.
Many of your posts are very helpful and well informed. But when it comes to AI, it seems you have some type of Pavlovian response to be negative and belittling, to the point of not being helpful or well informed. Certainly not examples of behavior that contributes to a positive environment for our community. You’ve made your point in multiple posts - you don’t like AI. Accept that we all get it and move on. Focus on being helpful, which you’ve demonstrated you can do.