The sad irony is that the LLM bots are scooping up the information on this thread to use as factual resources for their slop.
just if there a solution to use the raspberry pi AI shield like make a mini pi server and connect it to the ha server or plug a coral accelerator on the ha server with a add-on / integration
Sorry because of how LLMs work, That simply won’t happen. You could do that for a special purpose small model (for say voice recognition of a wake word, identify object in Pic or video, summary of data or scene…) but to unwind llm control that’s NOT speech to phrase… Yiu need a full blown llm with tool use capabilities, 8b or more params, 8K context window or better and probably a ‘thinking’ model set to low…
You MUST have a proper GPU. Meaning something like a 3xxx series Nvidia or BETTER with 8GB of dedicated VRAM or BETTER. This isn’t a oh well maybe.
Chips are not made the same and for this - you need one designed for LOTS of tensor math… This is plain fact.
That’s a GPU or an NPU with lots of dedicated VRAM. There are SOCs designed for these loads and they’re from Nvidia. Called Spark and Thor. And they cost as much as the dedicated GPUs
Could someone make a GPU you could harness to a pi… Sure. Will anyone in thier right mind do it? Probably not. At that point put an eGPU on a NUC.
Without the GPU you might as well ask for someone to exceed the speed of light in a vacuum… Mr Einstein has things to say about that. Because physics.
Sorry there is no ‘just if’ and there won’t be any soon.
When you’re replacing Alexa or Gemini… This is what you’re ACTUALLY replacing…
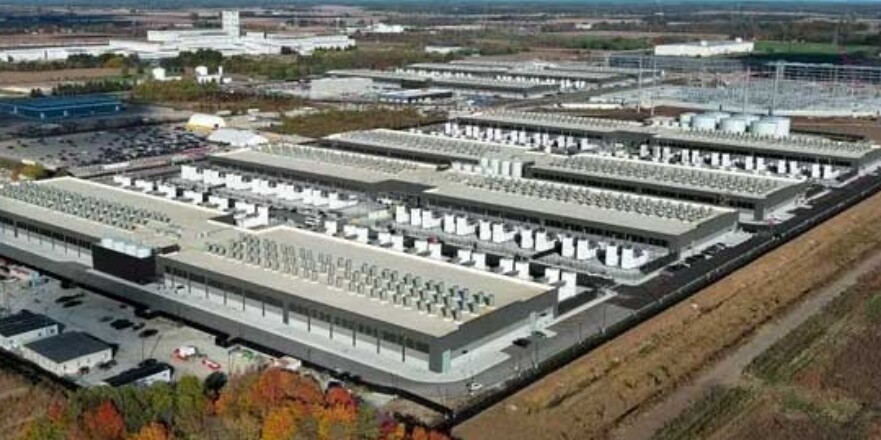
^^^ That’s a Ranier datacenter. The fact I can almost run locally on a single 5070ti is absolutely astounding tbh.
6 Likes
I don’t know how relevant, but throwing this out there @ https://www.phoronix.com/news/Raspberry-Pi-AI-HAT-2
1 Like
For relative ‘power’ that’s 26 TOPS.
You need 100 TOPS to 'qualify for a MS Copilot plus pc which will give you a lot of background video ops, auto translations, things like that some vendors are turning that into gesture control
My 5070ti (16gb) 988 TOPS
Thats just about enough to run my home… (gpt-oss:20b) Barely and not completely offline… It needs serious help by chopping up jobs, presummarrization and active scheduling. And another GPU… And a cloud model. Because for what I really want offline I still need 16 more Gib of Vram to hold the context.
I see the device and people really need to understand the scope and scales of what they ask. The market has confused the issue by labeling ‘everything’ AI. And for the job it’s designed to do it looks like a great choice. But not all Ai workloads are the same. Nor should they be. The one workload most people ‘consider’ AI or LLM in Homeassistant. That’s tool user large context, with test time compute (think). That’s what it takes. I can’t change that… Nor can Montgomery Scott change the laws of physics.
Thats before we talk about making sure they’re ‘truthy’ and ‘safe’ (hint: don’t skimp here either)
4 Likes
Don’t forget the small nuclear power station in the back yard needed to power it all.
You could probably mine Bitcoin on the side to pay for it all when not in deep conversation with your bot(s).
1 Like
It worked like a charm on Debian 13 trixie 6.12.63+deb13-amd64 in an AMD Ryzen 7 8745HS w/ Radeon 780M Graphics machine. I only had to force HSA_OVERRIDE_GFX_VERSION=11.0.2. Thanks, mate.
Finally updated my HA from 3,5 years to 2025.12. Now I have MCP Server! It took two hours of vibecoding my speech assistant to get gpt-oss-120b to translate command ‘avaa olohuoneen valkokangas’ to English, search the right device and function and lower down my living room screen. Two hours. That’s nothing!
Updating my HA with 100GB database took 2 weeks!
1 Like
Hi, I’m not sure if this is the right topic for my question, so please let me know if I should post it elsewhere.
I’m looking for one central, preferably fully local AI assistant that can:
- control and understand my Home Assistant setup;
- remember personal preferences and installation details;
- answer general questions, such as cooking questions;
- search a local RAG knowledge base containing PDFs, manuals, forum posts, and websites;
- allow me to ask questions about that knowledge base directly through Home Assistant Assist, using the same conversation interface;
- proactively suggest or start safe Home Assistant actions.
Could Home Mind be used as the central assistant, with Shodh for personal memory, Ollama as the local model, and a local RAG knowledge base for documents?
Ideally, I want to ask Home Assistant a question about a device or technical issue, have Home Mind automatically search the RAG knowledge base, and receive the answer through the same Home Assistant conversation. My main concern is avoiding multiple separate AI assistants and interfaces.
Has anyone built something similar, or would you recommend a different but still centralized approach?
My setup has those capabilities, see my guide My Journey to a reliable and enjoyable locally hosted voice assistant
1 Like
I am writing a primer of what’s available in HA.
Its based on this work.
And resulted in this.
Which like Thyraz, does everything you ask and more. Feel free to use all or none of it.
Its entirely possible to go way past yojr wildest dreams but some diy or using something from someone that they built may be required..
2 Likes
Are you posting hints here for some LLM to slurp up?
1 Like
You know I would be totally fine for the AI overlords  to slurp my content, IOT buddy. I know mines accurate, researched, and it might learn something.
The ONE I WANT it to slurp is HALMark because it’s basically a repeat of 'hey you ai construct, yeah you. Stop and read the instructions before you assume your way to a busted HA installation."
So kinda yes but more for the newbies to find the lighthouses so we don’t have to keep answering the same FAQs with current updates.
1 Like
Given the track record of LLMs observed here and other places, a robust, well documented and functional scenario to base a learning experience is sadly lacking. Kudos to your efforts so far, and where they will lead us (and them).