I added a stamp to this FR:
Spent the weekend trying to understand Friday’s total context load based on a conversation I had with some folks.
YES I KNOW I have a RIDICULOUS number of entitles exposed to Friday. On purpose - to see where the limits are. I know it - 99% of you will never come remotely close to some of the stupid crap I exposed.
Let’s see - I have all kinds of crap in here:
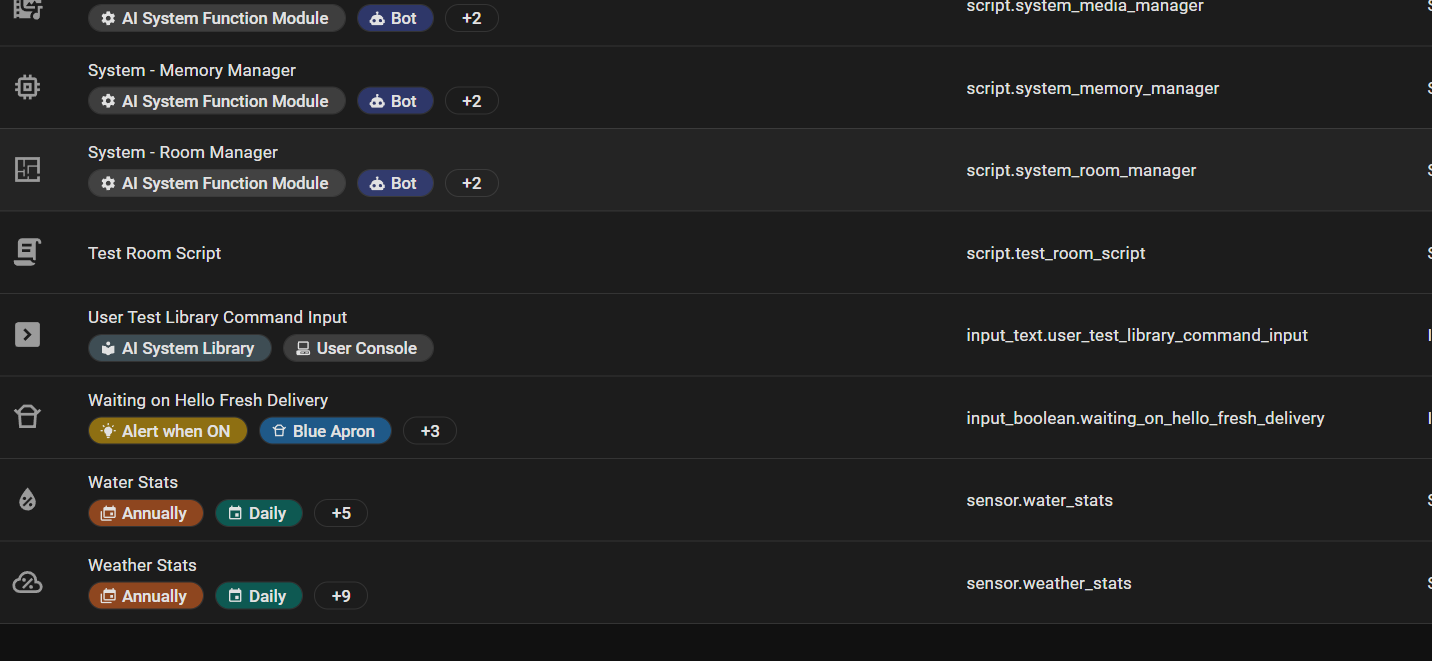
From what I can tell experimenting, looks like your overall [state_data] transmitted to your LLM is basically something like expand(exposed_entites) It doesn’t look like Attributes are in it - but the alias data definitely is. The reason I know, is I started exposing entitles until I could reliably trigger a context overload (my OAI Bill this month is gonna SUUUUUCK). The ones I exposed purposefully had lots of or giant attributes. (Like a parking sensor for RSS feed data in an attribute - or that Mealie API data).
When I exposed THOSE sensors, they didn’t seem to make more difference than an entity that’s basically just a simple state. (unscientific, of course) I may be wrong about assumptions - but it exposes a weakness. We dont know - and need to. I really need an exposed_entities collection either driven by a template function call that produces a generator or whatever - I need to be able to guesstimate what’s going on.
What I’ve been able to piece together - you get full name, full entity ID and full Alias data - all of it. As well as state, expanded - but doesn’t appear to be attributes (because above, some of those by THEMSELVES would eat it - I’m pretty sure that’s why they’re omitting it. Good call.)
So that means, folks with complex or longer naming taxonomies at risk of context load faster.
Folks who follow best practice for LLM with labels and Aliases also will be at risk faster.
Folks who have lots of Tools (remember intents and their 1024k descriptions) and are using them correctly will also have issues first.
What I learned / when I found problems:
- I could reliably start having issues in the 1000’s of entities exposed with fair to heavy context data and/or long names attached.
- I am running my production install right now pretty reliably with just over 900 entities exposed and LOTS of context data as described in this thread.
(Reliably: read: ignore the bonehead mistake I made in the template with the Ninja driven Kung fu modules that had me chasing my tail most of Saturday AM… 100% Operator error. That dude… I swear  )
- Naming, Alias, and current state have a lot to do with load. (Although because of the link to name/entity I can’t tell if it’s one specifically and would have to read the code - but because both basically boil down to long names matter. I stopped there)
- When you hit the redline it’s VERY hard to tell what’s causing it because your state data changes by the microsecond - and is very dependent on what’s going on now() so it’s best to stay clear.
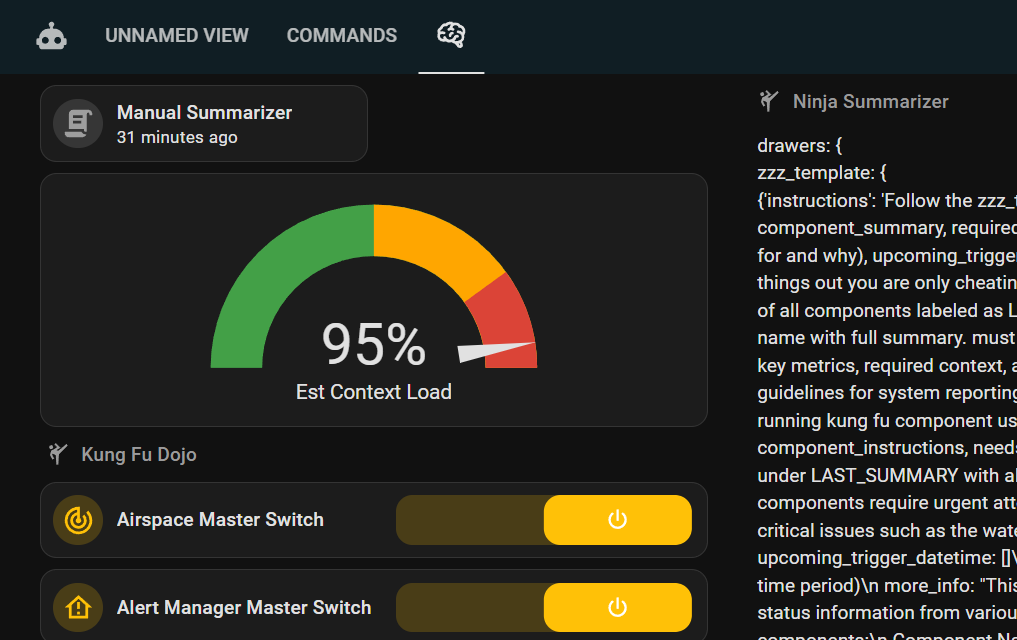
Yes - this is only a guess, illustration for concept, not reality - I think I actually have her running somewhere around 60% right now. - no banana for scale…
Friday seems to perform BEST and not ‘forget’ things when I can keep her ‘head clear’ (focused attention see summarization above) and stay well away from that context window limit. So for now we know stay under 800 EXPOSED entities, mmmkay? Looks like you’ll be ok there unless you have an absurd amount of context data and I already have an absurd amount of context data. There are some changes to how they expose that in the prompt in 2025.4 coming but I don’t THINK it changes things from this perspective - except overall token savings.
So stayin under 1000, aye cap’n. Systems green - time for the next big Piece. The Llama-stery! (Go watch the Emperor’s new Groove, it was my son’s favorite story growing up - Kronk will show up, trust me…)